Longhand MCP Server
io.github.Wynelson94/longhand
Local semantic memory for Claude Code—search your entire session history in ~29ms with zero API calls.
What is the Longhand MCP server?
Longhand is a persistent local memory system for Claude Code that captures every tool call, file edit, and thinking block from your sessions into a searchable SQLite database. It enables semantic recall across your entire project history without sending data to external APIs or summarizing content—everything is stored verbatim and indexed locally on your machine.
Longhand solves the problem of Claude Code session rotation by capturing your complete session history into a local, searchable database. Instead of relying on larger context windows or external APIs, it stores everything on your laptop and lets you recall past fixes, decisions, and conversations via natural-language fuzzy search in ~29ms. This is especially valuable for power users with 20+ sessions who need to find a specific bug fix or decision from weeks ago without re-reading raw JSONL files or paying token costs.
How to install Longhand
Copy-paste configuration for popular MCP clients.
Tools & capabilities
Tools this server exposes to the agent.
recall— Search across all sessions with a natural-language query; returns ranked episodes with context and session IDs.search— Semantic search within a specific session or project; supports context_events parameter to control output size.list_sessions— List sessions across projects with optional filtering; returns session metadata and staleness indicators.get_session_timeline— Retrieve events from a specific session with limit, offset, and tail parameters for browsing history.get_file_history— Fetch the edit history of a specific file across sessions.replay_file— Retrieve the full content of a file at a specific point in session history.find_episodes— Extract and list episodes (fixes, decisions, conversations) from sessions.list_plans— Surface all Write/Edit events to ~/.claude/plans/*.md across your entire history.reconcile— Dry-run or fix (with fix=true) the index to catch any on-disk transcripts not yet ingested.recall_project_status— Get a digest of recent work and staleness status for a specific project.doctor— Diagnostic tool to check store health, transcript format drift, hook errors, and migration status.analyze— Re-ingest and re-analyze sessions (episodes, segments, project/session vectors).get_commit_lookup— Map a commit hash to the session and episode where it was created.
Use cases
- Find a specific bug fix or architectural decision from weeks ago by describing it in natural language, without re-reading raw session files.
- Quickly review what you worked on in a project over the last N days, including all fixes and decisions made across multiple sessions.
- Replay the exact state of a file at any point in your session history to understand how a feature evolved.
- Search for all episodes related to a specific topic (e.g., 'Stripe webhook') across your entire project history in ~29ms.
- Diagnose index staleness and automatically reconcile on-disk transcripts that haven't been ingested yet.
Longhand MCP server FAQ
Longhand is a local memory system for Claude Code that captures your entire session history into a searchable SQLite database. It lets you recall past fixes, decisions, and conversations via semantic search without sending data to external APIs.
Yes. Longhand is open-source (MIT license), runs entirely on your machine, and has zero API costs. You only need Python 3.10+ and pip.
Install via pip: `pip install longhand`, then run `longhand setup` to ingest your history and configure the MCP server. Claude Code will then have access to Longhand's tools automatically.
No. Longhand is 100% local—it reads your existing ~/.claude/projects/ files, stores data in SQLite and ChromaDB on your machine, and makes zero external API calls.
Typical users: 200–400MB. Heavy power users (792+ sessions): ~7.5GB. Once Claude Code rotates source files off disk, Longhand becomes your only copy of that history.
Linux and macOS (Python 3.10–3.14). Windows is not supported; use WSL2 instead. The project is tested daily on macOS and gated in CI on Linux.
README (reference)
Source of truth, from the repository.
Longhand
Using Codex too? Share one memory archive between Claude Code and Codex.



Persistent local memory for Claude Code. Every tool call, every file edit, every thinking block from every Claude Code session — stored verbatim on your machine. Searchable, replayable, and recallable by fuzzy natural-language questions. Zero API calls. Zero summaries. Zero decisions made by an AI about what's worth remembering.
Claude Code quietly rotates your session files after a few weeks. Longhand captures them into SQLite before they're gone. Once ingested, your history stays forever — even after the source JSONL files are deleted. Install early; the past you don't capture is unrecoverable.
If you have 20+ Claude Code sessions in
~/.claude/projects/, Longhand can search across every fix, decision, and conversation you've had in ~29ms — without a single API call.
Does it use a lot of tokens? No — the tools you'll use most are capped by design. A full
recallacross 100+ sessions returns ~4K tokens. Reading one raw session JSONL costs 10–50× more. See Token budget for which tools cap output and which don't.
pip install longhand
longhand setup        # ingest history + install hooks + configure MCP
longhand recall "that stripe webhook bug from last week"
Want to kick the tires first? Run longhand demo for a 60-second walkthrough on a fake 3-session sample corpus — your real ~/.claude and ~/.longhand are not touched. The demo seeds a sandboxed store with a Stripe-webhook bug + Supabase auth migration + downstream 401 fix, then runs cross-session recall and project-status so you can see what the output looks like before committing.
pip install longhand
longhand demo         # sandboxed; cleans up afterwards (pass --keep to explore)
Upgrading to 1.0.0? This is the release that closes the deprecation window 0.13 opened. Everything removed here has been warning since 0.13.0:
- Four CLI aliases are gone:
patterns→recall "<topic>",recap→status --days N,continue→status --session <prefix>,reanalyze→analyze --all. - The
reconcileMCP tool now defaults to a dry run. If you have an agent loop that relied on the implicit heal, passfix=trueexplicitly. Dry runs tell you so in the payload. - Six retired MCP tools left the listing (19 → 13) but still answer forever with a migration note — retired names live in users' own
CLAUDE.mdfiles and must never hard-fail. - New: COMPATIBILITY.md states what 1.x guarantees and what it doesn't.
Your database needs nothing. Migrations are automatic and a 0.11+ store opens on any later 1.x — that's Promise 2, and there's a real 0.11-schema fixture in the test suite proving it.
Upgrading to 1.2.x? No removals, just fixes worth knowing about:
- 1.2.3: MCP
get_session_timeline'stailnow returns the true last N events on sessions over 5,000 events — it used to return the middle.setup's closing hint stopped suggestingrecap(removed at 1.0) and now suggestsstatus --days 7. Recall's footers andget_session_timeline's own tool description stopped namingsearch_in_context(retired from the tool listing at 1.0, though it still answers) and now point atsearch— the footers spell out the call,search(session_id=…, query=…, context_events=5). - 1.2.2:
recallsays so when its top match is much older than the alternatives instead of letting a stale fix read as current (see Recall Example). A Codex context-compaction record (compacted) no longer tripsdoctor's transcript-format-drift warning. - 1.2.1: MCP
get_session_timelinehad a sentinel bug that made every call return exactly one event, ignoringlimit/offset, unlesstailwas passed explicitly — fixed.search's project auto-scoping no longer overrides an explicitsession_id.
Upgrading to 0.13.0? Nothing breaks — that release opened the v1.0 deprecation window, so every old name kept working while pointing at its replacement:
statusis now the single resume command: barestatus= recent digest (wasrecap),status <project>unchanged,status --session <prefix>= session tail (wascontinue). The old commands still run and print a pointer; they're removed at v1.0.- Six MCP tools folded into six survivors with identical parameters (
search_in_context→search+context_events,get_episode→find_episodes+episode_id, etc. — full table in the CHANGELOG). The retired names still answer, prefixed with a migration note. - Hooks can no longer exit nonzero — failures become breadcrumbs in
~/.longhand/logs/and two newdoctorrows (Hook errors,Transcript format) keep them visible. - "Today"/"yesterday" recall windows now follow your local calendar day instead of UTC's; rankings may shift once if you're not in UTC.
- Windows users: this release fixes a serious bug where the ingest-lock liveness check could terminate other longhand processes.
- New:
LONGHAND_DATA_DIRrelocates the store for the CLI, hooks, and MCP server in one move — exceptlonghand config --set, which always writes~/.longhand/config.jsonregardless of the relocated store (#96;--editis currently a no-op, same issue).status --json/doctor --jsonfor scripting.
Upgrading to 0.9.0? Live ingestion captures sessions in flight, plan history is preserved as first-class data, and an optional reconciler job keeps the index honest in the background:
- New
longhand ingest-livecommand runs from Claude Code'sStophook to tail the active transcript between assistant turns. The in-progress session becomes queryable immediately vialist_sessions,get_session_timeline/timeline,get_file_history, andreplay_file— it writes events only, no embeddings, sorecalland semanticsearchstill need the SessionEnd pass (or areconcile --fixpass, which re-ingests with analysis) to see it. - New
longhand plans listcommand andlist_plansMCP tool surface every Write/Edit to~/.claude/plans/*.mdacross your entire history. Plans are now extracted as their own entity alongside episodes. - New
longhand schedule install-reconcilerinstalls an optional launchd job that runsreconcile --fixperiodically — catches anything the live and post-session hooks missed without you ever thinking about it. - The Stop hook coexists with the existing SessionEnd hook: live tails the transcript as it grows; SessionEnd does the full analysis pass when the session closes.
Upgrading to 0.8.1? Staleness signals now propagate everywhere they belong, and reconcile is an MCP tool — Claude can self-heal the index from inside a session:
searchandlist_sessionsnow wrap the response withstale: true+stale_reasonwhen the project they're scoped to has on-disk transcripts not yet ingested. Pre-v0.8.1 these returned clean-looking empty results (same silent-failure shaperecall_project_statuswas built to catch — just one layer up).- New
reconcileMCP tool wrapslonghand reconcile --fix. After a staleness banner fires, Claude callsreconciledirectly instead of asking the user to run a CLI command. list_sessionsdefaultlimitraised from 20 to 50 — active days routinely cross 5+ projects across 5+ sessions; the old default truncated reviews silently.
Upgrading from 0.7.x or earlier? Cleaner recall narratives, plus a real bug-finding test layer underneath (from 0.8.0):
- Pre-v0.8
_compose_fix_summaryprepended a literal"Intent:"label to half of all extracted episodes (49% of the reference corpus). The label leaked into every recall narrative for those episodes. Migration v4 strips it from existing rows on first store open — no command needed. - Diff content in
fix_summarynow truncates at whitespace boundaries with a visible…, instead of landing mid-token (phoneNum',family?:',strin'). Forward-only. - Narrative footer "Other matches" lines now include the session id so you can drill in.
- New canary harness (
tests/fixtures/corpus/) anchors regression tests to real shipped bugs. New recall validator (scripts/recall_diff.py) snapshots and diffs ranking results against your live corpus — catches regressions pytest can't see.
pip install --upgrade longhand
longhand recall "..."   # migration runs transparently on first open
If you're also coming from 0.5.x, run longhand reconcile --fix once to re-attribute multi-project sessions per the v0.6 inference improvements (cd-into-project sessions now attribute to the project where most work happened, not the first-event cwd). If you're on 0.5.8 or earlier, chain them: longhand reconcile --fix && longhand analyze --all. Both are idempotent.
Large history? (>1 GB of ~/.claude/projects) Expect the first-time backfill to take 10–30 minutes on an M-class Mac — most of that wall time is the embedding model running on all your cores (which is why you'll see triple-digit CPU%; that's ONNX doing its job, not a hang). --skip-analysis defers the other pass — episode/segment extraction and project/session-level vectors — not event embedding, which always runs, so it trims some time but not the dominant cost:
longhand setup --skip-analysis   # events stored + embedded; episodes/segments deferred
longhand analyze --all           # fill in episodes + segments + project/session vectors whenever, safe to background
search, timelines, file history, and commit lookup all work immediately after --skip-analysis — every event is embedded regardless of this flag. recall's episode/segment narrative and recall_project_status need the analyze --all pass to have data to draw on. Typical throughput on an M-class Mac is ~1–2 sessions/sec for full analysis.
Status: v1.2.3 — stable, daily-driver tested, security-audited (zero critical findings), on PyPI, available as a Claude Code plugin. Validated against 792 real sessions (786 Claude Code, 6 Codex) across 45 inferred projects (measured 2026-09-27). 617 unit tests passing.
Full docs: Longhand Wiki — getting started, CLI reference, MCP tools reference, architecture, and troubleshooting.
The Inversion
Everyone is solving AI memory by making the context window bigger. 1M tokens. 2M tokens. Context-infinite. The whole industry is racing in the same direction: make the model carry more state.
Longhand goes the other direction. The model doesn't need to carry the memory. The disk does.
| Bigger context windows | Longhand | |
|---|---|---|
| Where it lives | Rented from a model provider | A SQLite file + ChromaDB on your laptop |
| Cost per query | Tokens × dollars | Zero |
| Privacy | Goes through someone else's servers | Never leaves your machine |
| Speed | Seconds to minutes for large contexts | ~29ms search · ~128ms full recall (warm; see Stats) |
| Loss | Attention degrades in the middle of long contexts | Nothing summarized — messages, edits, and thinking blocks stored verbatim† |
| Persistence | Dies when the window closes | Lives until you delete the file |
| Across model versions | Doesn't transfer | Same data, any model |
| Offline | No | Yes |
| Scales with | Provider's pricing | Your hard drive |
† Nine Claude Code entry types (KNOWN_SKIP_ENTRY_TYPES) and, on the Codex side, three top-level record types (CODEX_SKIP_RECORD_TYPES) plus ten event_msg kinds (CODEX_SKIP_EVENT_MSG_TYPES: the UI mirrors of canonical messages, and turn bookkeeping) — mostly pure harness bookkeeping (queue markers, progress pings, usage and state snapshots) — are recognized and skipped rather than stored. That's not quite "zero content dropped," though: one of those types, attachment, can carry a queued follow-up prompt in its own attachment.prompt field, and Codex's encrypted-reasoning and context-compaction (compacted) records are dropped outright. Everything else with real content — every ordinary message, tool call, file edit, and thinking block — is kept verbatim.
The "memory crisis" in AI was an artificial constraint. Storage is solved. SQLite is from 2000. ChromaDB is a mature open-source vector store. Both run on a laptop. Longhand bypasses the crisis by ignoring it — your past sessions are already on disk, written by Claude Code itself, in JSONL files that contain every single event verbatim. Longhand reads those files, indexes them locally, and gives you semantic recall over your entire history without ever sending a token through someone else's API.
Local. Complete. Yours.
Storage footprint: ~7.5GB for a heavy power user (792+ sessions, 269k+ events, months of daily Claude Code usage across 45 inferred projects — measured 2026-09-27, see Stats). Typical users: 200–400MB. Once Claude Code rotates the source files off disk, Longhand isn't a duplicate — it's the only copy.
Platform support
Python 3.10 – 3.14 are all fully supported and gated in CI — branch protection requires the full suite to pass on all five before a PR merges (admins can bypass it — see CONTRIBUTING.md).
Longhand pins chromadb<1.0 for every Python version, not just 3.14. The pin originated with chromadb's newer Rust bindings segfaulting on 3.14 (#4, now closed), and it stays until a 1.x chromadb is verified across the whole matrix.
Windows is not supported. Use WSL2. A windows-latest × py3.12 leg runs on every PR, but it's a non-blocking continue-on-error step — and it fails. 12 core tests fail on every run (hook install/uninstall idempotency, config-file paths, redaction, live-ingest line counting, demo cleanup, and more — tracked in #112), not flaky edge cases. The job shows green in GitHub's UI only because continue-on-error swallows the failed step; it is evidence-gathering, not a claim that Longhand works there. Linux (3.10–3.14) is the only platform CI actually gates; there is no macOS leg. macOS is the author's daily-driver OS and where it's validated by hand (see Stats), but it isn't independently verified in CI.
Two things are macOS-specific regardless of the CI matrix: schedule install-reconciler installs a launchd job and is a no-op elsewhere (use cron/systemd-user on Linux; on Windows, use WSL2). mcp install also only ever writes Claude Desktop's macOS config path (#105) — there's no Claude Desktop release for Linux, and Windows isn't supported (#112); wiring a Windows Claude Desktop to a WSL2 install would mean hand-editing its config to launch Longhand through wsl.exe, which is untested.
Codex Desktop and Codex CLI threads are captured into the same archive from 1.1.0 — see Works with Codex.
Compatibility
Longhand 1.0 makes five promises, each backed by an enforcement artifact in the repo. The full text is in COMPATIBILITY.md; the short version:
- Stable surface — CLI and MCP frozen through 1.x. Removals only at a major version, and only after warning for one full minor.
- Forward data compat — a database written by 0.11+ opens on any later 1.x. Migrations are automatic, one-time, never renumbered. Older code refuses a newer database loudly rather than operating blind.
- Hook guarantees — hooks never raise, never touch the network, never block your prompt.
- Upstream drift is never silent — unknown transcript entries are preserved, surfaced in
doctor, and regression-gated. - Honest metrics — counts reflect real signals, and
doctornever recommends a remedy that cannot work.
Deprecation policy: anything slated for removal warns for at least one full minor release first, and the warning names its replacement. Retired MCP tool names are the one thing that never goes away — they leave the tool listing but keep answering forever with a migration note, because those names live in users' own CLAUDE.md files.
Longhand vs claude-mem
thedotmack/claude-mem is the most popular Claude Code memory tool on GitHub (55k+ stars). It's a good tool. It is also solving the memory problem in the opposite direction from Longhand, and the difference is worth understanding before you pick one.
| claude-mem | Longhand | |
|---|---|---|
| What's stored | AI-generated summaries / "observations" | Verbatim events from the raw JSONL |
| Who decides what's kept | An LLM, at write time | Nobody — no summarizer filters it |
| Compression | Semantic (lossy, by design) | None (lossless) |
| API calls per session | One or more (calls Claude to summarize) | Zero |
| Thinking blocks | Typically folded into summaries | First-class, stored verbatim |
| Deterministic replay | No — summaries can't reconstruct file state | Yes — every diff kept and replayable |
| Model portability | Tied to the summarizer's output | Same data works across any model, forever |
| Runtime | TypeScript, Bun, HTTP worker on :37777 | Python, no server |
| License | AGPL-3.0 | MIT |
The philosophical split: claude-mem asks an AI what was important and keeps that. Longhand keeps the actual bytes and lets you decide later. If you trust a model's judgment about its own past, claude-mem's approach is cheaper at query time (pre-summarized) and easier on storage. If you've ever been burned by a summary that dropped the thing that turned out to matter, Longhand is the tool that never throws anything away.
Both can coexist on the same machine — they operate on the same JSONL files without interfering.
The Principles
Longhand is built on a handful of principles. If you disagree with them, you probably want a different tool.
1. Information doesn't disappear — it moves.
When data goes "missing" it's almost never actually gone. It got compressed, summarized, filed somewhere else, or renamed. Find the raw source and the truth is still there waiting. Claude Code already writes every session to disk as JSONL. That file is the raw source. Longhand just reads it.
2. Summarization is a lossy decision disguised as a convenience.
Most AI memory systems read a conversation and ask the AI to write down "what mattered." The AI is now the gatekeeper of its own memory, and the AI has incentives — brevity, confidence, coherence — that aren't the same as truth. You end up with a story about what happened instead of what happened.
Longhand never summarizes. It stores the complete record and lets you query it.
3. The raw record is cheap. Acting like it isn't wastes it.
A full Claude Code JSONL file is kilobytes to low megabytes. A year of daily sessions is hundreds of megabytes. That is nothing on modern hardware. There is no engineering reason to throw the data away. Summary-based memory isn't saving space — it's giving away information that was free.
4. The thinking is the most valuable part.
When Claude produces a thinking block, that's the reasoning behind the decision — usually invisible to the user, almost always more useful than the final answer. Summary-based memory throws thinking blocks away because they're "internal." Longhand treats them as first-class events. "What was I thinking when I chose to use a conditional update?" pulls the verbatim thinking block that contains the answer.
5. A fix you can't reproduce is a fix you didn't keep.
If you fixed a bug in March, the state of that file when the bug was fixed is a fact. Longhand reconstructs it deterministically by applying every edit in sequence from the session JSONL. No guessing, no AI inference, just literal application of the diffs. You can see the exact state of any file at any point in any past session.
6. Memory should be proactive, not just searchable.
A searchable archive is useful but passive. Real memory answers fuzzy questions. "A couple months ago I was building a game that kept breaking, then you fixed it — bring that fix forward." Longhand parses the time phrase, matches the project, finds the problem→fix episode, and returns the diff. You don't have to know the session ID. You just have to remember that it happened.
7. Deterministic beats clever.
Everything in Longhand's analysis is rules-based. Regex error detection. Hash-based project IDs. Forward-walking episode extraction. No LLMs in the core pipeline. That means fast (~128ms median warm recall — measured 2026-09-27, see Stats), reproducible (same input → same output), and fully local (no API keys, no cloud). An LLM layer could go on top later, but the foundation runs on laws, not on a model's opinion.
8. Local or nothing.
Your Claude Code history is yours. It goes into a SQLite file and a ChromaDB directory in ~/.longhand/. No telemetry. No sync. No account. If your laptop is offline, Longhand works. If Anthropic goes down, Longhand works. If you delete the directory, it's gone.
One boring exception, disclosed in full: the interactive CLI checks pypi.org for a newer Longhand version. Most commands respect a 24-hour cache and print any hint only after their own output, so nothing you're waiting on is delayed. doctor (and setup, which runs it) is the exception — it forces a fresh, synchronous fetch every time, with a 2-second timeout, before it prints its table. The request carries nothing but itself — no telemetry, no identifiers, nothing about your corpus. It's excluded from Claude Code's hooks and from the mcp-server entry point mcp install actually configures for Claude Desktop, but not yet from longhand shared-mcp, mcp serve, or demo — those currently run the same check at exit like any other command (#101). LONGHAND_NO_UPDATE_CHECK=1 turns all of it off. "Zero API calls" means what it always meant: no LLM or cloud service ever touches your data.
What It Actually Does
When you use Claude Code, every session writes a JSONL file to ~/.claude/projects/<project>/<session-id>.jsonl. That file contains every message, every tool call, every thinking block, every file edit with full before/after content, and a millisecond-precise timestamp for each event.
Longhand reads those files. Then it gives you:
- Semantic search across every event you've ever generated
- Filterable search — by tool, file, session, project, and event type — all filters combinable (MCP
search; the CLIsearchcommand has tool/file/session/type but no project filter, and neither has a time-range filter) - Tool call archaeology — "show me Bash commands that touched Supabase" — ranked by relevance, not literally every match; scope to a session or project to cut noise
- File history across sessions — every edit to a specific file, chronologically, across all your sessions
- Session replay — reconstruct any file's state at any point in any past session
- Reasoning retrieval — query Claude's verbatim thinking blocks
- Timeline view — chronological playback with pagination (offset, tail, summary-only scan mode)
- Fuzzy recall — natural-language questions about past work ("that race condition fix from last week")
- Project inference — automatic detection of which projects you've worked on, with categories and aliases
- Episode extraction — automatic detection of problem→fix sequences in your sessions
- Conversation segments — topic-level clustering (stories, design discussions, debugging, planning) so recall finds the why, not just the what
- Git-aware project recall — ask "where did we leave off on X" and get recent commits, unresolved issues, last session outcome in one call
- Git commit extraction — structured extraction of every git commit, push, merge, checkout from sessions, linked to episodes
- MCP server — 13 tools that let Claude query Longhand directly during live conversations
- Auto-ingest hook — drops into Claude Code's
SessionEndhook so new sessions are indexed automatically - Live ingestion — the
Stophook (installed alongsideSessionEndbyhook install; not separately optional) tails the active transcript between turns so an in-flight session is queryable immediately vialist_sessions, timeline, file history, and replay. It stores events only, no embeddings — semanticrecall/searchstill wait for theSessionEndpass, or for areconcile --fixpass to pick it up (the live tail never setsproject_id, so reconcile treats it as needing a full re-ingest) - Plan history — every Write/Edit to
~/.claude/plans/*.mdis captured as a first-class entity, queryable vialonghand plans listand thelist_plansMCP tool - Secret redaction (opt-in) —
longhand config --set redact.enabled=truemasks secret-shaped strings (API keys, tokens, JWTs, DB passwords) at ingest before they reach the index;longhand redact --applyretroactively masks data ingested earlier (see SECURITY.md for the current gap in git commit message coverage, #110) - Background reconciler — optional launchd job (
longhand schedule install-reconciler) keeps the index honest without manualreconcile --fixruns - Context injection —
UserPromptSubmithook auto-injects relevant past context before Claude sees your message (configurable threshold and size cap); prints the same age-gapNote: …line asrecallwhen the injected context is old and stale-looking relative to fresher work - Configurable —
longhand configto tune injection relevance, token budget, and behavior without editing code
Install
pip install longhand
longhand setup
That's it. longhand setup backfills your existing Claude Code history, installs the hooks that keep it updated automatically, registers Longhand as an MCP server for Claude Desktop, prints the one-line command to add it to Claude Code (claude mcp add longhand -s user -- longhand mcp-server), and verifies everything works. About two minutes the first time, zero maintenance after that.
To upgrade later: pip install -U longhand.
Developer install (from source)
git clone https://github.com/Wynelson94/longhand.git
cd longhand
pip install -e .
longhand setup
longhand ingest                       # ingest all your existing Claude Code history
longhand analyze --all                # run analysis (projects, outcomes, episodes, segments)
longhand hook install                 # wires both SessionEnd and Stop hooks (installed together)
longhand prompt-hook install          # (optional) auto-inject past context into new prompts
longhand mcp install                  # register Longhand as an MCP server for Claude Desktop
claude mcp add longhand -s user -- longhand mcp-server  # ...and for Claude Code
longhand schedule install-reconciler  # (optional, macOS-only) launchd job to run reconcile --fix periodically
longhand config                       # view/tune hook behavior (relevance threshold, injection size)
longhand doctor                       # verify everything is wired up
longhand ingest-live isn't in this list on purpose — it's primarily the hidden entry point the Stop hook calls (reading transcript_path from stdin JSON), though it also accepts --transcript <path> directly if you want to run it by hand.
Quick Start
# What's in the archive?
longhand stats
longhand sessions
longhand projects

# Daily-use commands — status is the single resume command (git-status shape)
longhand status                             # what have I been up to (recent digest)
longhand status --days 30 -p bsoi           # filtered digest
longhand status <project-name>              # where did we leave off on a project (git-aware)
longhand status --session <session-id>      # pick up where a session left off
longhand history src/app/route.ts           # every edit ever to a file
# (recap / continue / patterns / reanalyze were deprecated aliases through
#  0.13 and were removed at 1.0 — use status, recall, and analyze --all)

# Semantic search
longhand search "race condition"
longhand search "stripe webhook" --tool Edit
longhand search "why did we" --type assistant_thinking

# Proactive recall (the fun one)
longhand recall "that clerk type error I fixed a couple weeks ago"
longhand recall "the python missing module bug last month"

# Session inspection
longhand timeline <session-id-prefix>
longhand replay <session-id> /path/to/file.ts
longhand diff <event-id>

# Git history
longhand git-log                            # recent git operations across all sessions
longhand git-log <session-id>               # git ops in a specific session
longhand git-log --type commit              # only commits
longhand git-log --query "fix parser"       # search commit messages

# Export
longhand export latest-fix                  # most recent resolved episode
longhand export ep_<id> --out fix.md        # specific episode to file
longhand export <session-id-prefix>         # full session timeline

# Configuration
longhand config                             # show current hook settings
longhand config --set hook.min_relevance=3.0  # tune injection threshold
longhand config --set hook.max_inject_chars=1000  # cap token usage

# Plans + background maintenance
longhand plans list                         # every plan-mode plan you've written
longhand plans list --limit 100             # raise the row cap (default 50)
longhand schedule install-reconciler        # background launchd job (macOS); runs reconcile --fix
longhand reattribute                        # dry-run: find sessions attributed to the wrong project
longhand reattribute --fix                  # apply the moves (idempotent)
longhand db vacuum --prune-aux              # reclaim disk space; --prune-aux deletes ALL event_type='unknown' rows —
                                             #   not just harness noise, but doctor's drift records and the deliberately
                                             #   preserved summary/pr-link/worktree-state/frame-link rows too
Session IDs accept prefix matches — longhand timeline cf86 is enough if only one session starts with that.
Recall Example
$ longhand recall "that stripe webhook I was fixing"

╭─ Project matches ───────────────────────────────────────╮
│ new-product (nextjs web app) · alias: 'stripe' · 1.52   │
╰─────────────────────────────────────────────────────────╯

You asked: that stripe webhook I was fixing

Found it: new-product · 2 weeks ago · session a4ba29d1

### What went wrong
Type error: Property 'current_period_end' does not exist on type 'Subscription'.

### How it was diagnosed
In Stripe's type definitions, current_period_end moved off the Subscription interface. It's still on the actual API payload but the types don't expose it. We need to cast through Record<string, unknown> to access it.
### The fix
Edit on route.ts: 'const periodEnd = sub.current_period_end' → 'const periodEnd
= (sub as Stripe.Subscription & Record<string, any>).current_period_end as number'

Diff:
- const periodEnd = sub.current_period_end
+ const periodEnd = (sub as Stripe.Subscription & Record<string, any>).current_period_end as number

✓ Verified — a test or command succeeded after the fix.

Other candidates (4)
• 2 weeks ago: Type error: Module '"@/lib/utils"' has no exported member 'getInitials'.
• 2 weeks ago: Type error: Property 'role' does not exist on type 'User'.
That's one local command. No API call. The fix came from a session file Claude Code wrote to your disk weeks ago and Longhand had been waiting with the answer the whole time.
Two things not shown above. First, the age-gap warning fires only when the top match is at least 30 days old and at least 30 days older than the newest runner-up, with no time phrase in the query — not just "weeks older." When it fires, a line appears right after "Found it:" — Older than the other matches — the best match is from 6 months ago, but newer related work exists from 2 months ago. If you meant current work, add a time phrase like "this week" or "this month". Ranking is unchanged; it's a warning, not a re-sort. Second, when a candidate comes from conversation segments rather than a clean episode, its footer names the exact follow-up call with the real session id filled in: search(session_id="a4ba29d1", query="...", context_events=5). The weaker "Also possibly relevant" footer (what episodes-recall shows when segments exist in other sessions) currently prints that same call shape with a literal session_id="<session>" placeholder instead — copy the real id from the bullet above it.
MCP Integration
Longhand's 13 tools are the same regardless of client; how you register the server differs.
Claude Code:
claude mcp add longhand -s user -- longhand mcp-server
Or install the Claude Code plugin (ships this repo's .claude-plugin/plugin.json and a bundled .mcp.json that registers the server for you) — see the marketplace/plugin docs for the current install flow. longhand setup step 4 prints the claude mcp add command above; it does not run it for you.
Claude Desktop: run longhand mcp install to wire Longhand into Claude Desktop's config (longhand setup does this too, unless --skip-mcp). This writes only Claude Desktop's config file — it has no effect on Claude Code.
After restarting the client, it has thirteen tools:
Core (searchable archive):
search— semantic search with session, project, tool, file, and event_type filters (all combinable); passcontext_eventswith asession_idto get each match wrapped in its surrounding conversation. When the query text itself names a project and no explicitproject_id/project_name/session_idis given, results auto-scope to that project (payload becomes{auto_scoped_to, auto_scope_hint, hits}) — pass an explicitsession_idto suppress it, or a project filter to make the scoping deliberate; there's currently no other override (#102)list_sessions— recent sessions with project/time filters; passproject_id(plus optionalsince/until) for a project's outcome-enriched session timelineget_session_timeline— chronological view with offset/tail pagination and summary-only scan mode (tail: Ncovers "the latest events / how did it end")replay_file— reconstruct file state at a point in timeget_file_history— every edit to a file across all sessionsget_stats— storage statistics (its description currently promises adata_dirfield it doesn't return — #106)
Proactive memory:
recall— fuzzy natural-language recall (use this first): a narrative built from conversation segments and session timelines, with high-precision problem→fix episodes when the work left clean evidence. Since 1.2.2, an untimed query whose top match is 30+ days old and 30+ days older than the newest runner-up gets a leading note saying so (ranking is unchanged) — add a time phrase to skip the checkrecall_project_status— "where did we leave off on X?" — git-aware project summary with commits, issues, last outcomefind_episodes— structured search for problem→fix pairs; passepisode_idfor full detail on one episode (referenced events, diff, post-fix file state)list_projects— browse inferred projects; passmatchfor fuzzy candidates with scored reasonslist_plans— every Write/Edit to~/.claude/plans/*.mdacross your entire history
Git history:
find_commits— search across all sessions by commit message, hash prefix, or branch name; or pass asession_idwithout a query for one session's chronological git story
Self-healing:
reconcile— wrapslonghand reconcileso Claude can re-attribute and re-ingest from inside a session after a staleness banner; defaults to a dry run (passfix=trueto apply — that default flipped at v1.0)
Left the tool listing at v1.0, still answer forever with a migration preamble: search_in_context → search(context_events) · get_latest_events → get_session_timeline(tail) · get_project_timeline → list_sessions(project_id) · get_session_commits → find_commits(session_id) · get_episode → find_episodes(episode_id) · match_project → list_projects(match)
Output capping is uneven, not universal: search, get_session_timeline, recall, recall_project_status, and find_commits accept max_chars (pass 0 or negative to disable it, though that's rarely what you want); list_sessions and list_projects truncate at a fixed 16,000 characters only in their default modes — list_sessions(project_id=…) and list_projects(match=…) are on the uncapped path below; get_file_history, replay_file, get_stats, find_episodes (its list mode returns up to limit — default 20, max 1000 — not one episode; only episode_id detail mode is scoped to one), list_plans, and reconcile return whatever the query produces, uncapped (#103). See Token budget for the full breakdown.
Once installed, you can ask Claude things like "what did we decide about the auth middleware in last week's session?" and it will actually search its own past work.
Auto-Ingest
longhand hook install adds two hooks to ~/.claude/settings.json — Stop for live tailing between turns, SessionEnd for the full analysis pass at session close. Both are installed together; there's no flag to add one without the other. The installer resolves longhand to its absolute path and wraps each command in Claude Code's hook schema:
{
  "hooks": {
    "Stop": [
      {"matcher": "", "hooks": [{"type": "command", "command": "/abs/path/to/longhand ingest-live"}]}
    ],
    "SessionEnd": [
      {"matcher": "", "hooks": [{"type": "command", "command": "/abs/path/to/longhand ingest-session"}]}
    ]
  }
}
Both commands read transcript_path from the hook's stdin JSON, so no flags are needed in the hook entry itself.
- Stop hook (
ingest-live) runs after every assistant turn. Tails the transcript file and stores new events (plus tool-call pairing and session stats) incrementally, so an in-flight session is queryable vialist_sessions, timeline, file history, and replay while you're still working in it. It never embeds, so semanticrecall/searchstill need theSessionEndpass — or areconcile --fixpass, which re-ingests with full analysis since a live-tailed session never got aproject_idand lands in reconcile'snull_projectbucket. A failure here is silent by design — no stdout, no breadcrumb — since it must never risk disrupting your turn;SessionEndandreconcileare the backstop. - SessionEnd hook (
ingest-session) runs once when a session closes. Does the full analysis pass: project inference, outcomes, episodes, segments, embeddings. A failure here prints one line to stderr and leaves a breadcrumb inlogs/hook-errors-YYYY-MM-DD.log(surfaced bydoctor), then exits 0.
Both are non-blocking and run in one to two seconds. You don't have to think about either of them again.
Optional background reconciler: longhand schedule install-reconciler adds a launchd plist that runs reconcile --fix on a schedule. Catches sessions the hooks missed if the transcript is still on disk — reconcile enumerates from ~/.claude/projects/, so a transcript Claude Code has already rotated away is invisible to it, same as any other tool here.
Works with Codex
Use Codex Desktop or the Codex CLI too? Longhand captures those threads into the same archive, so a question asked in Claude Code can be answered from work done in Codex, and the other way round.
pip install -U longhand
longhand codex-sync                                                  # capture Codex threads on this machine (up to 50/run)
claude mcp add --scope user longhand-shared -- longhand shared-mcp   # keyword search across both clients, from Claude
codex mcp add longhand -- longhand shared-mcp                        # the same server from Codex (Desktop: config.toml, see the docs)
From then on reconcile --fix captures new Codex threads too, so a scheduled reconciler keeps both clients current. A thread is stored exact-record-only while it is being written — verbatim and searchable, no model loaded — and gets the full pipeline 30 minutes after it goes quiet, so recall sees it without you re-running anything, provided something is polling on a schedule (the launchd reconciler, a codex-sync --watch loop, or the codex-sync launchd template below) — codex-sync --semantic runs the full pipeline immediately if nothing is. Threads Codex spawns for itself are skipped by default, UI mirrors are never stored twice, and unknown record shapes surface in doctor like any other drift. Setup, bounds, and the macOS launchd template: docs/codex.md.
Architecture
longhand/
├── parser.py           — JSONL → typed Events (a short list of known harness-bookkeeping entry types is skipped, not stored)
├── codex.py            — Codex rollout capture + 30-minute-quiet finalizer, shared archive
├── replay.py           — deterministic file state reconstruction
├── redaction.py        — opt-in secret-shaped-string masking
├── update_check.py     — best-effort pypi.org freshness check (most commands; the hooks and the hidden `mcp-server` are excluded)
├── types.py            — Pydantic models
├── storage/
│   ├── migrations.py      — version-aware schema evolution
│   ├── sqlite_store.py    — structured data + full raw JSON preserved
│   ├── vector_store.py    — ChromaDB: events, sessions, projects, segments, episodes (5 collections)
│   └── store.py           — unified ingest pipeline
├── extractors/         — per-event (errors, file refs, topics, git ops)
├── analysis/           — per-session (project, outcomes, episodes, embeddings)
├── recall/             — per-query (time parsing, project match, narrative)
├── demo/               — sandboxed sample corpus for `longhand demo`
├── cli/                — Typer CLI with Rich output (`_commands.py`, `helpers.py`)
├── mcp_server.py       — Model Context Protocol server (13 tools)
├── lightweight_mcp.py  — `longhand-shared`: 4-tool keyword-only server, no model loaded
└── setup_commands.py   — hook install, mcp install, config, doctor
Source of truth: SQLite. Every event's raw JSON is preserved as a blob. ChromaDB is the search index — it only holds what's needed for semantic retrieval.
Analysis layer: Runs at ingest time, not query time. Pre-computes projects, session outcomes, and episodes so recall queries are fast. Fully deterministic, no LLM.
Recall pipeline: query → time parse → project match → episode search → rank → load artifacts → narrative. A full recall call issues several vector searches (events, projects, episodes, segments, plus relaxation retries), then loads artifacts and composes the narrative. Measured 2026-09-27 on the author's live corpus, warm and in-process (see Stats): a single vector search is ~29ms median; a full recall call is ~128ms median.
Comparison
| Longhand | Summary-based (Mem0, MemPalace, LangMem) | |
|---|---|---|
| Source | Raw Claude Code JSONL | AI-generated summaries |
| Tool calls captured | Every one, verbatim | Whatever the summarizer kept |
| File edits | Full before/after diffs | Usually not captured |
| Thinking blocks | First-class events | Usually discarded |
| File state replay | Deterministic | Not possible |
| Problem→fix extraction | Rules-based, at ingest | Depends on summarizer |
| Fuzzy recall | Yes, with artifacts | Text search over summaries |
| What gets "decided" | Nothing — store everything | The AI decides what matters |
| Local-first | Yes | Most |
| Completeness | Every message, edit, and thinking block, verbatim† | Whatever the summarizer kept |
| LLM calls to function | Zero | Varies |
Summary memory and Longhand solve different problems. Summary memory is good for long-term personal assistants that need compressed context across many conversations. Longhand is good for developers who need forensic access to their past Claude Code work — the kind of access where you need the exact diff, not a paraphrase.
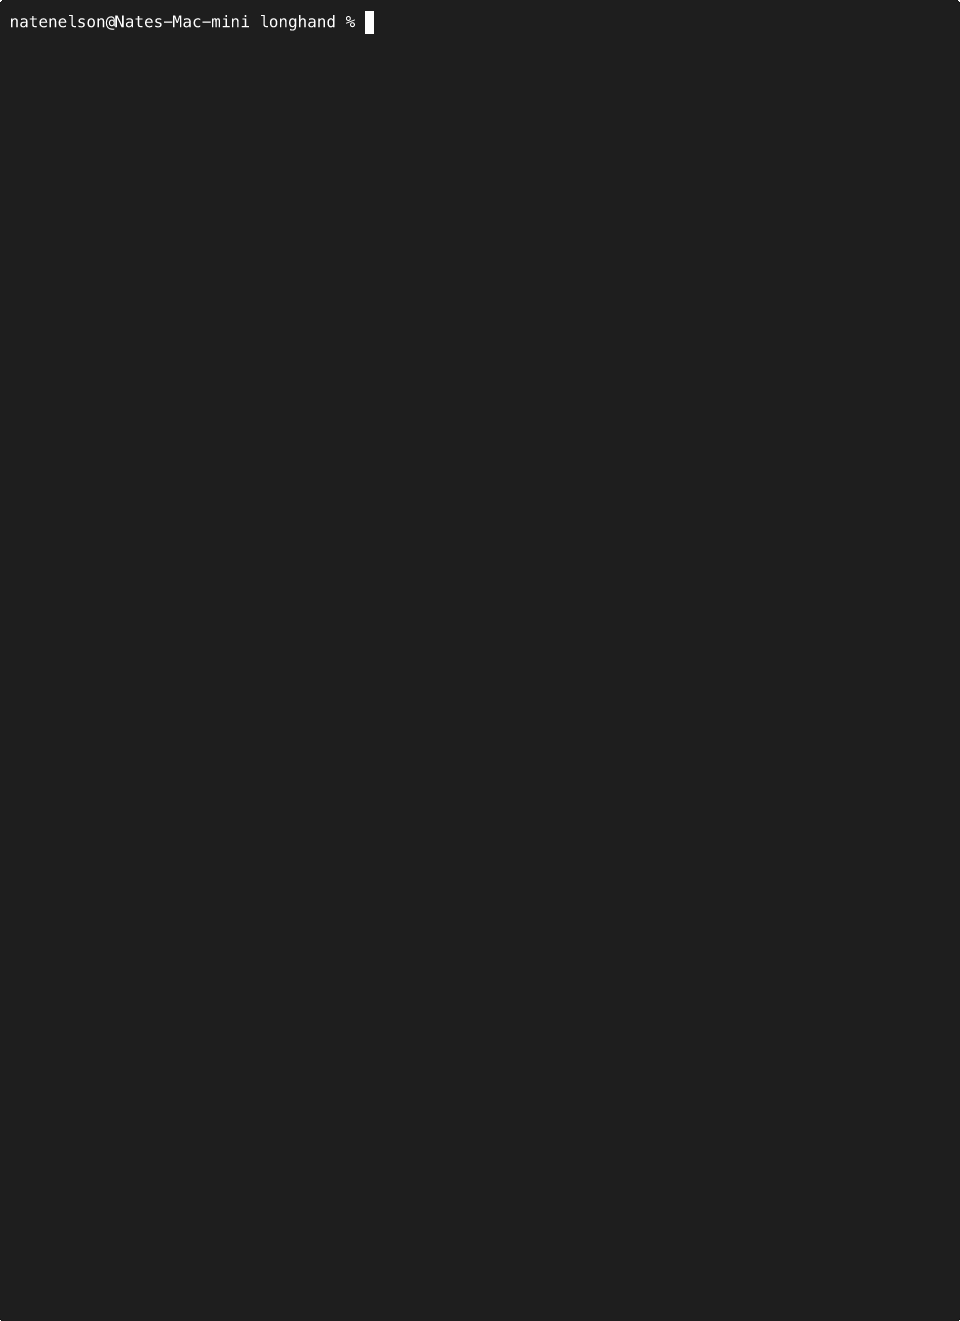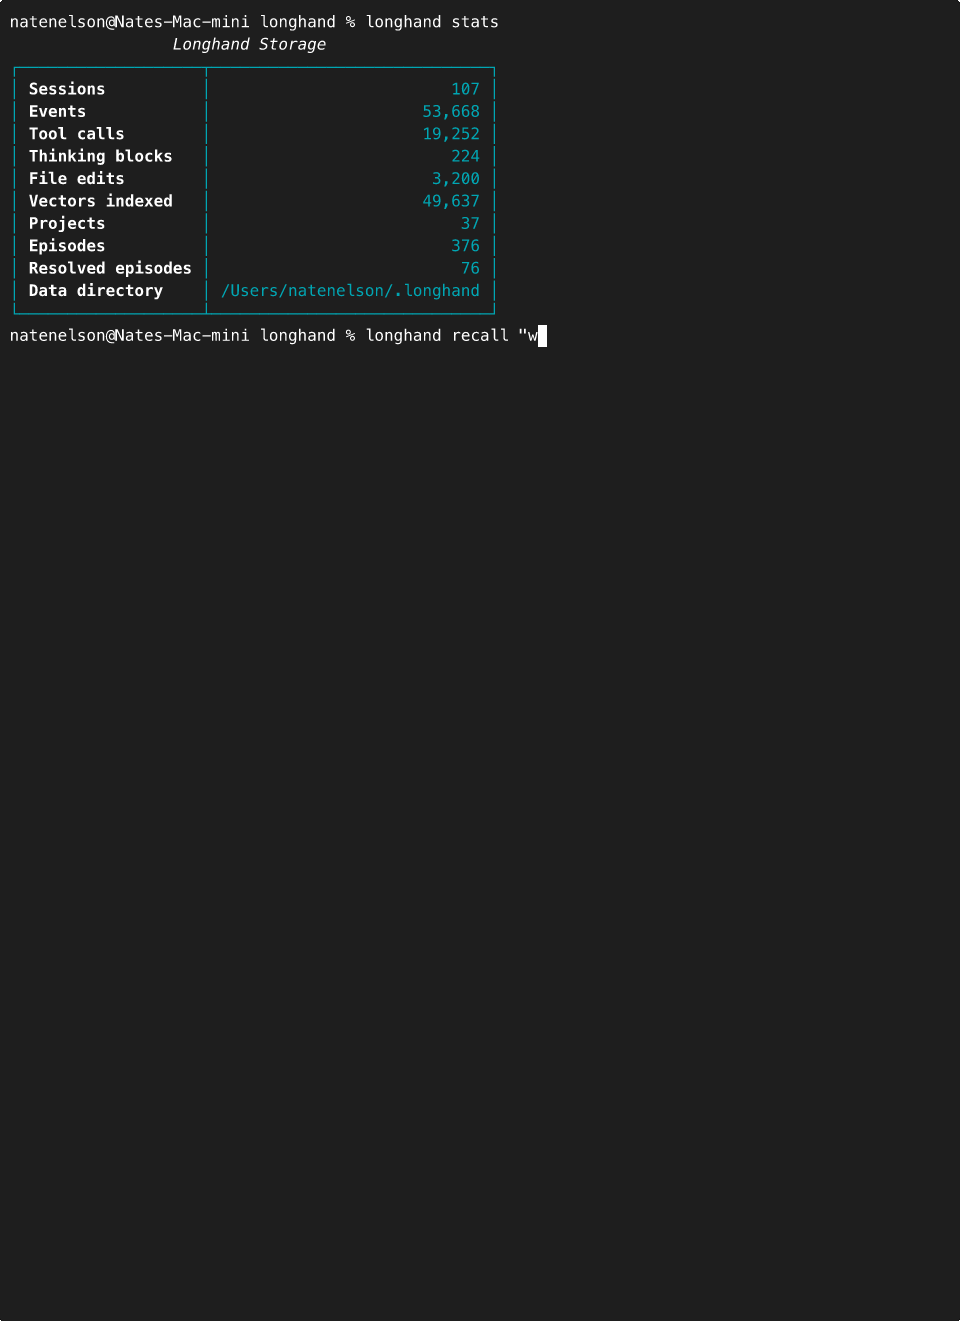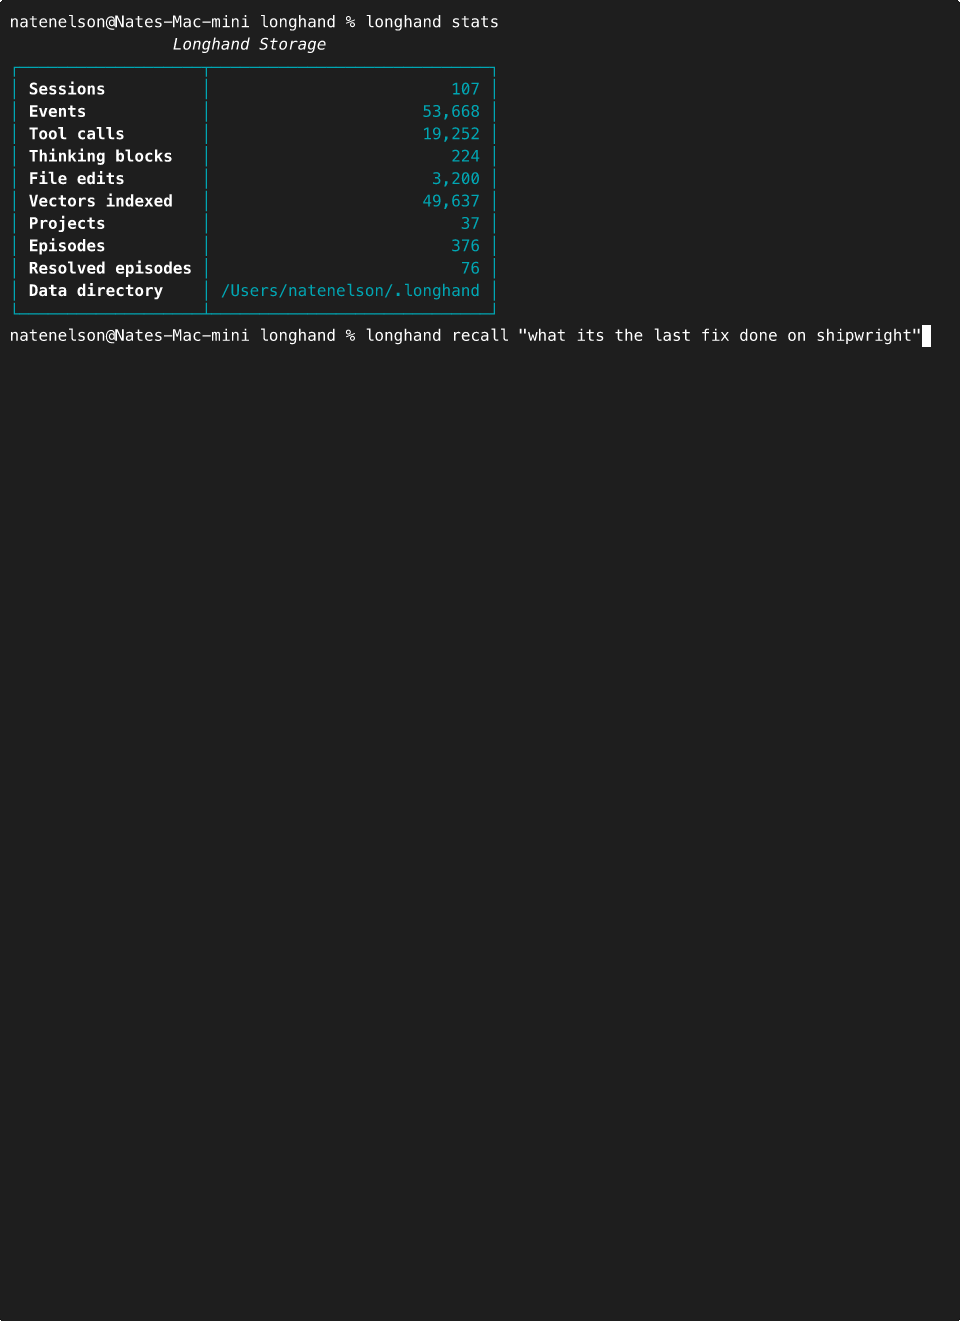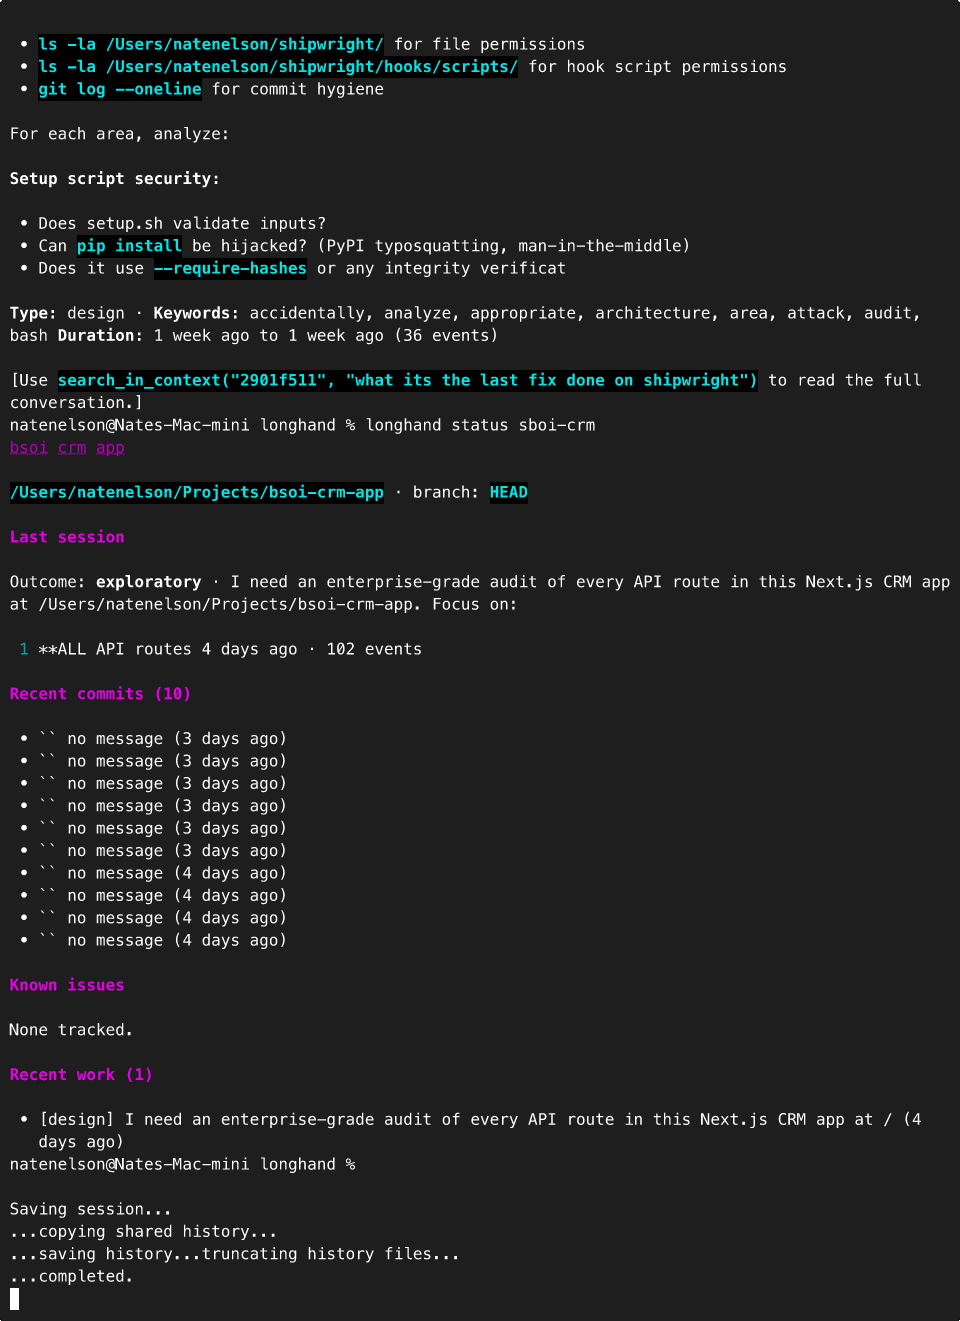
Stats
Corpus, measured 2026-09-27 against the author's live store (Apple M4, macOS, code at main):
- 792 sessions (6 of them Codex)
- 269,067 events
- 45 projects inferred automatically
- 1,809 problem→fix episodes extracted
- 6,632 conversation segments (design, story, debugging, discussion, planning)
- 3,723 git operations extracted
- Storage footprint: 5.9 GB SQLite + 1.6 GB ChromaDB
Latency, benchmarked on the same corpus and date — warm, in-process, the 8 scripts/recall_diff queries:
recall(full pipeline): ~128ms median (16 runs)- Vector search: ~29ms median (24 runs)
- SQL timeline read: ~1.6ms median (24 runs)
- First
recallcall in a fresh process (model + index load, cold start): ~0.6s
Token budget
The single most common question: does Longhand consume a lot of tokens when Claude uses it?
Mostly no — but the cap isn't universal, so read this table. Five of the 13 tools truncate their output and append a pagination hint before Claude ever sees it; two more cap at a fixed size, but only in their default mode; six return whatever the query produces, uncapped (#103). In practice get_file_history/replay_file are naturally scoped to one file (though a long edit history or a big file can still come back large); find_episodes is the one to watch — its default list mode has no natural scope and can return up to limit (max 1000) full episode rows uncapped, while only its episode_id detail mode is scoped to a single episode.
| Tool | Default output cap | Adjustable? |
|---|---|---|
search | 12,000 chars | max_chars |
search in context mode (context_events) | 20,000 chars | max_chars |
get_session_timeline | 16,000 chars | max_chars |
recall, recall_project_status | 16,000 chars | max_chars |
find_commits | 12,000 chars | max_chars |
list_sessions, list_projects (default mode) | 16,000 chars | no — fixed |
list_sessions(project_id=…), list_projects(match=…) | none | no — uncapped |
get_file_history, replay_file, get_stats, find_episodes, list_plans, reconcile | none | no — uncapped |
Ceiling on the max_chars parameter (MAX_OUTPUT_CHARS) | 200,000 chars | pass 0 or negative to disable truncation entirely |
Why this matters — the comparison:
- Reading one raw session JSONL directly: 50K–200K tokens per session (Claude Code sessions are typically 1–5MB each).
- Bigger-context-window approaches: every prompt pays the full history, every time.
- Summarizer-based memory tools: cheap per-query but they already threw away the thinking blocks.
Longhand is flat-cost: the cap is per-call, not per-corpus. Recalling across 10 sessions and recalling across 1,000 sessions both come back in the same token envelope. And Longhand itself makes zero API calls — the only tokens consumed are the MCP payload Claude reads back. No LLM sits between you and your data.
Tuning: the five tools listed above accept a max_chars parameter that can be lowered per-call. summary_only: true on get_session_timeline drops the content field and shrinks payloads ~10×.
617 unit tests passing, covering the listing and dispatch of all 13 MCP tools (only list_plans's handler isn't separately call-tested). Full security audit: zero critical findings, zero high findings. ~/.longhand/ is created with 0700 permissions on the main store-open path (several early-write paths don't yet apply that mode — #99); all SQL is parameterized; all inputs are bounded. Dependencies: chromadb, posthog, typer, rich, pydantic, mcp.
Author
Nate Nelson. Idaho Falls. No computer science degree. Fourteen industries of building software by describing what I see and letting the translation happen.
GitHub: Wynelson94
License
MIT. Do whatever you want with it.
Related MCP servers
A coding and development harness on local models or hosted APIs, for code, review, research and ops.
View repository →
ResearchZosho
Deep research assistant that checks its citations against the sources and keeps what it found.

Solana Mainnet verification, intelligence, machine receipts, and agent logistics through MCP.

QMD MCP
Local QMD search and bounded index maintenance through a Streamable HTTP MCP server.

SageMath
Sandboxed SageMath MCP server with 40 tools for symbolic math, calculus, linear algebra, and verification.

io.github.XCP/mcp-server
Interact with Counterparty — the token protocol on Bitcoin. Query, compose, sign.