CogniRepo MCP Server
io.github.ashlesh-t/cognirepo
Persistent memory and context for AI agents—FAISS, AST, call graphs, and 35 MCP tools for 50–80% token reduction.
What is the CogniRepo MCP server?
CogniRepo is an MCP server that provides persistent memory, semantic search, and code intelligence for AI agents like Claude and Cursor. It indexes codebases using FAISS embeddings, AST reverse indices, and knowledge graphs to enable fast symbol lookup, architectural summaries, and cross-session context retention—all fully offline and without API keys for indexing.
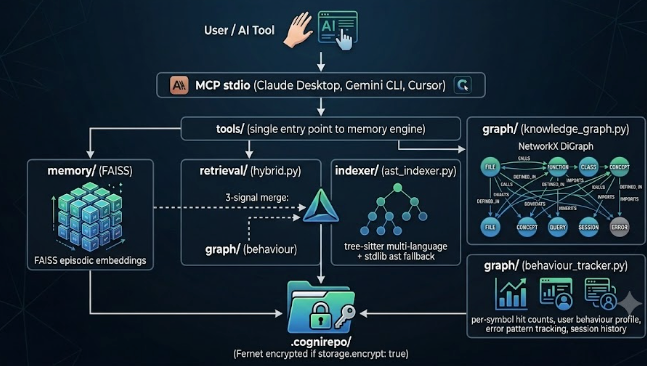
CogniRepo sits between your codebase and AI tools, accumulating project knowledge across sessions. It combines semantic memory (FAISS vector store), episodic logs (event journals), knowledge graphs (function/class/import relationships), and AST indices for O(1) symbol lookup. On codebases ≥15K LOC, it reduces token usage by 50–80% compared to naive file reads, and enables AI agents to remember decisions, errors, and architectural context from prior sessions.
How to install CogniRepo
Copy-paste configuration for popular MCP clients.
Tools & capabilities
Tools this server exposes to the agent.
context_pack— Token-budget code + memory context retrieval for every session startlookup_symbol— O(1) symbol lookup returning file and line numberwho_calls— Trace callers and dynamic dispatch fallback for impact analysissearch_token— Word-level reverse index across names, docs, and commentsretrieve_memory— Semantic similarity search over stored memoriessearch_docs— Full-text search in all .md documentation filessemantic_search_code— Vector search over code symbols onlysubgraph— Local knowledge graph neighbourhood around an entitygraph_stats— Node and edge count and graph health metricsepisodic_search— BM25 keyword search in event historydependency_graph— Import and dependency relationships for modulesexplain_change— What changed in a file or function with git cross-referencearchitecture_overview— Pre-computed LLM architectural summariesget_user_profile— User interaction style, depth preference, and vocabulary profileget_session_history— Recent conversation exchanges across sessionsrecord_user_preference— Store style or format preferencesget_error_patterns— Recurring errors with prevention hintsrecord_error— Log an error for future avoidanceget_agent_bootstrap— Single-call session start with brief, context, profile, and errorsget_session_brief— Architecture, hot symbols, and index health
Use cases
- Reduce token usage by 50–80% on large codebases by retrieving only relevant code context before each AI query
- Resume coding sessions where you left off by retrieving prior conversation history, decisions, and error patterns across days or weeks
- Trace function calls and dependencies across your entire codebase in <1ms to understand impact of changes before refactoring
- Build institutional memory of architectural decisions, past errors, and design rationale so AI agents avoid repeating mistakes
- Enable seamless handoff between AI tools (Claude, Cursor, Gemini) by sharing indexed project knowledge and context across agents
CogniRepo MCP server FAQ
CogniRepo is an MCP server that provides persistent memory and code intelligence for AI agents. It indexes your codebase using FAISS embeddings, AST analysis, and knowledge graphs to enable fast symbol lookup, semantic search, and cross-session context retention—all offline and without API keys for indexing.
Yes. CogniRepo is MIT-licensed and open-source. Indexing, memory storage, and all 35 MCP tools work fully offline. Optional API keys (Anthropic, Gemini, OpenAI, Grok) are only needed for the `cognirepo ask` command; they are not required for any MCP tool or indexing.
Install via pipx: `pipx install cognirepo`. Then run `cognirepo setup` in your project—it automatically configures Claude Desktop and Cursor with the correct MCP connector. Each project gets its own isolated connector to prevent data mixing.
Python 3.11+. CPU-only embeddings (fastembed/ONNX) are the default—no PyTorch or CUDA required. Optional GPU support is available via `pipx inject cognirepo 'cognirepo[gpu]'`.
CogniRepo is most effective on codebases ≥15K LOC where institutional memory across sessions adds value. On smaller repos (<10K LOC), native file reads are faster. Use CogniRepo when you need persistent error tracking, architectural decision records, cross-session context, or cross-agent handoff.
No API keys are required for indexing, memory storage, or any of the 35 MCP tools. Optional API keys (Anthropic, Gemini, OpenAI, Grok) are only needed if you use the `cognirepo ask` command for multi-model orchestration.
README (reference)
Source of truth, from the repository.
CogniRepo
mcp-name: io.github.ashlesh-t/cognirepo
Persistent memory and context for any AI tool. Not a chatbot — infrastructure.


lookup_symbol returns file:line very quickly — grep takes 2–8 seconds. On Python repos ≥ 15K LOC, CogniRepo cuts AI coding agent token usage by ~30–78% vs. a targeted grep+read baseline (up to 96–99% vs. reading every matching file naively) — benchmarked on Flask, FastAPI, Celery, and Ansible (5,900+ files). Works with Claude Code, Cursor, and Gemini CLI. Fully offline. No API keys required for indexing or any of the 35 MCP tools.
What it does
Every AI conversation starts from zero. Claude, Cursor, Gemini — none of them remember what you fixed yesterday, which files relate to which features, or what decisions were made last sprint. CogniRepo fixes that.
It sits between your codebase and any AI tool, providing:
- Semantic memory — FAISS vector store with sentence-transformer embeddings. Store decisions, docs, architecture notes. Retrieve them with natural language.
- Episodic log — append-only event journal. Know what happened before that error.
- Knowledge graph — NetworkX DiGraph linking functions, classes, files, imports, inheritance chains, call relationships, and concepts. All queryable.
- AST reverse index — O(1) symbol lookup across your entire codebase in any supported language.
- User behavior profiling — tracks how you prompt so Claude adapts its response style without you having to re-explain preferences every session.
- Error tracking — records errors with prevention hints so Claude avoids repeating the same mistake across sessions.
- Session history — persists conversation exchanges so any session can resume where the last one ended.
- Architectural summaries — auto-generated on first init; built entirely from the local AST index (no API key needed). File → directory → repo summary tree, embedded into FAISS for semantic search.
- Multi-model orchestration — classify query complexity → build context → route to the right model. Claude for deep reasoning, Gemini Flash for quick lookups. All automatic.
Every AI tool that connects gets the same accumulated project knowledge. Memory persists across sessions, across tools, across time.
When to use CogniRepo
Most effective on codebases ≥ 15K LOC. On small repos (< 10K LOC), native file reads are fast enough that the MCP tool schema overhead (~3,500 tokens for 35 tools) takes more than you save. Break-even is roughly 4 tool calls on a medium-sized repo.
CogniRepo vs. claude-context / similar tools:
| Feature | CogniRepo | claude-context / similar |
|---|---|---|
| Pure code retrieval | ✓ (FAISS + graph + AST) | ✓ Often faster on first use |
| Episodic memory (what happened last sprint) | ✓ Persistent BM25 + vector | ✗ |
| Cross-agent handoff (Claude → Gemini → Cursor) | ✓ last_context.json shared | ✗ |
| User behaviour profile (adapts depth/style) | ✓ get_user_profile() | ✗ |
| Error pattern avoidance (learns from past fails) | ✓ record_error() | ✗ |
| Architectural decision records | ✓ record_decision() | ✗ |
| Multi-repo org graph (microservices) | ✓ CHILD_OF / CALLS_API edges | ✗ |
Conclusion: prefer CogniRepo when you value institutional memory across sessions. Use simpler tools when you just need one-shot code retrieval on a small codebase.
Why it helps — measured numbers
Benchmarked across 6 real open-source repos (FastAPI, Flask, Celery, Ansible, Moby/Docker, Kubernetes) using 30 structured prompts tested against Claude, Gemini, and Cursor/Codex.
| Metric | Value | Notes |
|---|---|---|
| Token reduction — Python repos | 50–84% | FastAPI FA-2: 12 000 → 2 500 · FA-4: 2 000 → 450 · FL-4: 8 000 → 1 250 |
| Token reduction — average (all tested) | ~60% | Across FA/FL/CE/AN where both baselines were captured |
| Token reduction — complex dynamic codebases | 20–35% | Celery CE-4/CE-5; deep async/dynamic-dispatch patterns reduce gains |
| Symbol lookup latency | < 1 ms | vs. grep at 2–8 s on large repos |
| Accuracy vs. baseline | equal or better in 100% of tests | No regression observed; FA-2 accuracy improved Moderate → High |
| Cross-agent context handoff | ✅ validated | CE-4: Claude primed index, Gemini CLI consumed it — 35% token saving, same accuracy |
| Dynamic dispatch coverage | honest gap | CE-3 (APScheduler beat dispatch) returned NA for both; CogniRepo does not fabricate call chains |
| Go/multi-language coverage | grammar now ships | Moby MO-2 showed 67% savings; MO-3-5 / K8-* not yet re-run since Go tree-sitter grammar landed (COGNIREPO-500, 2026-09) |
Honest limits: CogniRepo adds the most value on Python repos with clear static structure. Dynamic dispatch patterns (Celery beat, plugin registries), deep Go codebases, and Ansible's 22-level variable precedence chains reduce retrieval confidence. The tool reports uncertainty rather than hallucinating call chains.
Measured: lookup latency and token reduction (4 external repos)
Indexed 4 real repos, measured with cognirepo index-repo + cognirepo benchmark --json on
v2.4.0+ (2026-09-17). CPU-only, no GPU.
| Repo | Files | Lookup latency | Token reduction (naive) | Token reduction (targeted) | context_relevance |
|---|---|---|---|---|---|
| flask | 92 | 0.002 ms | 97.3% | 29.5% | 80.5% |
| fastapi | 1,178 | 0.003 ms | 97.6% | 63.5% | 97.1% |
| celery | 444 | 0.003 ms | 99.7% | 77.7% | 100.0% |
| ansible | 4,196 | 0.008 ms | 96.1% | 28.6% | 56.6% |
Measured 2026-09-17. Lookup latency < 0.1 ms on all repos. "Targeted" is the realistic baseline (grep + read top-2 matching files, approximating what an agent would actually do); "naive" reads every matching file in full and is an upper bound, not a realistic comparison. moby and kubernetes are indexable (Go support confirmed, COGNIREPO-500) but not yet in this table — hours of indexing, scheduled separately. Full numbers and methodology, including precision@k, symbol hit rate, and memory recall: docs/METRICS.md.
Run cognirepo benchmark on your own codebase to reproduce. See docs/METRICS.md.
How it works
Quick start
Requirements
- Python 3.11+
- API key (optional — only needed for
cognirepo ask):ANTHROPIC_API_KEY,GEMINI_API_KEY,OPENAI_API_KEY, orGROK_API_KEY. Indexing, memory, summarization, and all MCP tools work fully offline.
Install
Recommended — pipx (global, one command, works on all distros)
pipx install cognirepo
That's it. cognirepo setup handles the rest — it installs optional extras (languages,
security, providers) via pipx inject automatically when you enable them in the wizard.
Why pipx? It creates an isolated venv for cognirepo automatically so
fastembedand all deps install cleanly. Thecognirepocommand is then globally available in every directory — no per-repo venv needed.Arch Linux / Debian 12+ / Ubuntu 24.04+: Do NOT
pip installinto system Python. These distros enforce PEP 668 and block system-wide pip installs. Use pipx.
Install pipx first (if needed)
# Arch Linux
sudo pacman -S python-pipx

# Debian / Ubuntu
sudo apt install pipx

# macOS
brew install pipx

# Any platform (fallback)
pip install pipx --user
Inside a virtual environment (alternative)
python -m venv .venv && source .venv/bin/activate
pip install cognirepo
# extras are installed by the setup wizard automatically
Development install (from source)
pipx install -e '.[dev,security,languages]'
# or inside a venv: pip install -e '.[dev,security,languages]'
Note: CPU-only embeddings are the default (fastembed/ONNX, no PyTorch/CUDA required). For GPU:
pipx inject cognirepo 'cognirepo[gpu]'then install torch separately.
Run
# One-command onboarding (init + index + auto-configure MCP for Claude/Cursor/VS Code):
cognirepo setup

# Or step by step:
cognirepo init --no-index     # scaffold .cognirepo/
cognirepo index-repo .        # index your codebase (required before MCP tools work)
cognirepo index-repo . --daemon  # index and run watcher in background

# Check everything is working:
cognirepo status                        # shows symbol count, graph nodes, signal warmth
cognirepo doctor                        # full health check

# Query through multi-model orchestrator:
cognirepo ask "why is auth slow?"

# Manage background watchers:
cognirepo list                          # show all running watcher daemons
cognirepo list -n <PID> --view          # tail the log of a specific watcher
cognirepo list -n <PID> --stop          # stop a watcher
First-time setup:
cognirepo init+cognirepo index-repo .must complete before MCP tools (context_pack,lookup_symbol,who_calls, etc.) return data.
Connect your AI tools
Claude Code / Claude Desktop (recommended — project-scoped)
Run cognirepo init inside your project — it asks if you want to configure Claude and
automatically writes .claude/CLAUDE.md and .claude/settings.json with the correct
project-locked connector.
Each project gets its own isolated connector named cognirepo-<project>:
{
  "mcpServers": {
    "cognirepo-myproject": {
      "command": "cognirepo",
      "args": ["serve", "--project-dir", "/abs/path/to/myproject"],
      "env": {}
    }
  }
}
The --project-dir flag locks the MCP server to that project's .cognirepo/ directory.
When Claude has multiple projects open simultaneously, each connector reads only its own
memories — never mixing data across projects or teams.
Cursor / Copilot
cognirepo export-spec
cp adapters/cursor_mcp_config.json .cursor/mcp.json
# Restart Cursor — CogniRepo tools appear in the tool selector
Docker
cp .env.example .env          # add your API keys
docker compose up mcp         # MCP stdio server
MCP Tools — complete reference
All 35 tools are available to Claude, Cursor, and any MCP-compatible client.
Core retrieval
| Tool | Description | When to use |
|---|---|---|
context_pack(query, max_tokens=2000) | Token-budget code + memory context | Every session — FIRST call before any file read |
lookup_symbol(name) | O(1) symbol lookup → file + line | Before grepping for a function |
who_calls(function_name) | Trace callers + dynamic dispatch fallback | Impact analysis, refactoring |
search_token(word) | Word-level reverse index across names, docs, comments | Finding where a concept lives |
retrieve_memory(query, top_k=5) | Semantic similarity search over stored memories | Before answering — pull past context |
search_docs(query) | Full-text search in all .md files | Documentation lookups |
semantic_search_code(query, language=None) | Vector search over code symbols only | Code-specific semantic queries |
subgraph(entity, depth=2) | Local knowledge graph neighbourhood | Understand symbol relationships |
graph_stats() | Node/edge count and graph health | Check if graph has data |
episodic_search(query, limit=10) | BM25 keyword search in event history | Find past decisions or incidents |
dependency_graph(module, direction="both") | Import/dependency relationships | Module coupling analysis |
explain_change(target, since="7d") | What changed in a file/function + git cross-ref | Understanding recent changes |
architecture_overview(scope="root") | Pre-computed LLM architectural summaries | Big-picture questions |
User & session intelligence
| Tool | Description | When to use |
|---|---|---|
get_user_profile() | User's interaction style: depth pref, question types, vocabulary | Call at session start — calibrates Claude's response style |
get_session_history(limit=10) | Recent conversation exchanges across sessions | Resuming context from prior sessions |
record_user_preference(key, value, context="") | Store a style or format preference | When user corrects interpretation or states a preference |
Error tracking & prevention
| Tool | Description | When to use |
|---|---|---|
get_error_patterns(min_count=1) | Recurring errors with prevention hints | Before proposing a fix — check if it has failed before |
record_error(error_type, message, file_path, query_context) | Log an error for future avoidance | After any error Claude or user encounters |
Session start
| Tool | Description | When to use |
|---|---|---|
get_agent_bootstrap() | Single-call session start: brief + last context + profile + errors (~300 tokens vs ~900) | Preferred first call — replaces the 4-call sequence |
get_session_brief() | Architecture + hot symbols + index health | First call when you need granular parts separately |
get_last_context() | Most recent context_pack snapshot from prior session | Resume where previous agent left off |
Memory & storage
| Tool | Description | When to use |
|---|---|---|
store_memory(text, source="") | Persist a memory to the FAISS index | After solving bugs, recording decisions |
log_episode(event, metadata={}) | Append event to episodic journal | Track milestones, incidents, deployments |
record_decision(summary, rationale="") | Record architectural decision to episodic memory | When making non-obvious design choices |
supersede_learning(old_memory_id, new_text) | Deprecate and replace an outdated memory in one call | When a past decision or fact has changed |
Reporting
| Tool | What it returns | When to use |
|---|---|---|
generate_insights(since="90d", repo_path=None) | Self-contained HTML repo-history report (timeline, decisions, challenges, activity, index health), sourced only from real stored records | "What happened in this repo" / repo-history requests — see Repo insights below |
Cross-repo (organization)
| Tool | Description | When to use |
|---|---|---|
org_search(query) | Search memories across all org repos | Multi-repo context queries |
org_wide_search(query) | Search across every project in the org | Broadest cross-repo sweep |
org_dependencies(depth=2) | Bidirectional inter-repo dependency graph | "What does this service depend on?" |
cross_repo_search(query, scope="project") | Project-scoped or org-scoped search | Finding shared components |
cross_repo_traverse(symbol, direction="both") | Traverse org graph from a repo or symbol | Tracing bugs across service boundaries |
find_symbol_path(from_symbol, to_symbol) | Shortest call-graph path between two symbols, across services | Tracing a request flow end-to-end |
get_service_endpoints(repo_path) | HTTP endpoint registry for a service | Listing a microservice's API surface |
list_org_context() | Org metadata + sibling repos | Understanding repo relationships |
link_repos(src_repo, dst_repo, relationship) | Record cross-repo dependency | When you discover one repo imports another |
Knowledge graph — what gets indexed
The knowledge graph is significantly richer than a simple call graph.
Node types
| Type | Description |
|---|---|
FILE | Every indexed source file |
FUNCTION | Function and method definitions with docstrings |
CLASS | Class definitions with base classes |
CONCEPT | Semantic concepts extracted from docstrings and identifiers |
QUERY | Recorded query nodes (for retrieval scoring) |
SESSION | Conversation session nodes |
ERROR | Recurring error pattern nodes |
MEMORY | Cross-agent memory nodes (synced from Claude/Gemini) |
Edge types
| Type | Direction | Description |
|---|---|---|
DEFINED_IN | symbol → file | Symbol lives in this file |
CALLS / CALLED_BY | bidirectional | Function call relationships with purpose labels |
IMPORTS | file → file | Python import dependencies |
INHERITS | class → parent | Inheritance hierarchy |
CO_OCCURS | file ↔ file | Files edited together (behavioural co-edit signal) |
RELATES_TO | concept → symbol | Semantic concept linkage |
QUERIED_WITH | query → symbol | Retrieval tracking for scoring |
IMPORTS and INHERITS edges are built automatically during index-repo from Python AST.
Use subgraph("MyClass", depth=2) or dependency_graph("mymodule") to query them.
User behavior profiling
CogniRepo tracks how you interact across sessions and builds a profile that Claude uses to calibrate its responses — without you having to repeat preferences every session.
What gets tracked
- Depth preference — inferred from average query length:
concise/medium/detailed - Question types — distribution across:
why,what,how,fix,explain,where,refactor,add - Domain vocabulary — top terms that appear frequently in your queries
- Code focus — percentage of queries referencing code identifiers (symbols, functions)
- Sample queries — last 3 queries for Claude to infer framing style
Accessing your profile
# MCP tool (Claude calls automatically at session start):
get_user_profile()

# CLI:
cognirepo user-prefs
Example profile output
{
  "depth_preference": "detailed",
  "top_question_type": "how",
  "question_type_distribution": {"how": 12, "why": 8, "fix": 5},
  "top_terminology": ["auth", "token", "session", "middleware", "validate"],
  "code_focus_percent": 73,
  "framing_hints": "prefers detailed responses; often asks 'how' questions; domain vocabulary: auth, token, session",
  "total_queries_tracked": 47
}
Claude receives framing_hints at session start and adjusts response length, code density,
and terminology accordingly. The profile accumulates over time — more accurate the more you use it.
Error tracking & prevention
CogniRepo logs every error that occurs during sessions — whether it's a Python exception, a failed build step, or a tool call that went wrong. Errors are stored with:
- Dedup signature — prevents the same error from inflating the count
- Prevention hint — a targeted suggestion to avoid the same error class
- Occurrence context — last 5 occurrences with file path and error message
- Query context — the query or action that triggered the error
Logging errors
# MCP tool (Claude calls after errors):
record_error("TypeError", "expected str got int", "config/parser.py", "fix config loading")
Viewing error patterns
# MCP tool:
get_error_patterns()
Returns:
[
  {
    "error_type": "TypeError",
    "count": 7,
    "files": ["config/parser.py", "api/handlers.py"],
    "last_seen": "2026-04-22T10:30:00Z",
    "prevention_hint": "Wrong type — validate inputs at function boundary.",
    "recent_context": "expected str got int in parse_config"
  }
]
Built-in prevention hints
| Error class | Prevention hint |
|---|---|
NameError | Undefined variable — check imports and scope before use |
ImportError | Import failed — verify package is installed and module path is correct |
AttributeError | Object missing attribute — check type, None-guard, or spelling |
TypeError | Wrong type — validate inputs at function boundary |
KeyError | Missing dict key — use .get() with default or check existence first |
IndexError | List out of range — guard with len() check before access |
OSError | File/IO error — always guard file ops with try/except OSError |
SyntaxError | Syntax error — run a linter before committing |
Timeout | Timeout — add explicit timeout parameter and retry logic |
AssertionError | Assertion failed — review invariants; do not use assert in prod |
Session history
Every cognirepo ask exchange is persisted to .cognirepo/sessions/.
Sessions are indexed by UUID and retrievable via:
# List recent sessions:
cognirepo sessions

# MCP tool — Claude calls at session start to resume context:
get_session_history(limit=5)
Each entry returns: session ID, created timestamp, message count, model used, and the last user/assistant exchange for quick context scan.
Architectural summaries
cognirepo init automatically prompts to run cognirepo summarize after the first index.
This produces a 3-level LLM summary of the entire codebase:
- Level 1 — repo-wide summary (what the project does, key modules, entry points)
- Level 2 — per-directory summaries (what each package is responsible for)
- Level 3 — per-file summaries (what each file contains, key functions/classes)
Summaries are stored in .cognirepo/index/summaries.json and served via the
architecture_overview MCP tool — zero token cost for Claude to understand the big picture.
# Auto-prompted on first init. Run manually anytime:
cognirepo summarize

# Fully local — no API key required. Reads from ast_index.json, runs in < 1 second.
# File summaries are also embedded into FAISS for semantic architecture queries.
Repo insights
What CogniRepo can tell you about your repo: generate_insights() (or cognirepo insights)
turns everything CogniRepo has recorded about a project — episodic events, architectural
decisions, open challenges, branch/commit activity, index health — into one self-contained HTML
report. Sourced only from real stored records; nothing fabricated. Screenshots below are from a
real report generated on this repo (cognirepo insights --since 365d), not mockups:
cognirepo insights --since 90d # writes .claude/insights/<repoName>-insights.html
Multi-model orchestration
cognirepo ask automatically picks the right model for each query:
| Tier | Score | Default model | Use case |
|---|---|---|---|
| QUICK | ≤2 | local resolver | Single-token / trivial — zero API, fastest path |
| STANDARD | ≤4 | Haiku | Quick lookup, factual, single symbol |
| COMPLEX | ≤9 | Sonnet | Moderate reasoning |
| EXPERT | >9 | Opus | Cross-file, architectural, ambiguous — full context, best model |
cognirepo ask "where is verify_token defined?"       # → QUICK, answered locally
cognirepo ask "why is auth slow?"                    # → EXPERT, Claude with full context
cognirepo ask --verbose "explain the circuit breaker"  # show tier/score/signals
Provider fallback chain: Grok → Gemini → Anthropic → OpenAI.
All errors are logged to .cognirepo/errors/<date>.log — no raw tracebacks shown to users.
Language support
| Language | Extensions | Install |
|---|---|---|
| Python | .py | built-in |
| JavaScript / TypeScript | .js .ts .jsx .tsx | cognirepo[languages] |
| Java | .java | cognirepo[languages] |
| Go | .go | cognirepo[languages] |
| Rust | .rs | cognirepo[languages] |
| C / C++ | .c .cpp .h | cognirepo[languages] |
Full details and roadmap: docs/LANGUAGES.md
Storage layout
.cognirepo/
  config.json              ← project settings (project_id, model, retrieval weights)
  vector_db/
    semantic.index         ← FAISS flat index for semantic memory
    ast.index              ← FAISS IndexIDMap2 for code symbols
    ast_metadata.json      ← parallel metadata for ast.index rows
  graph/
    graph.pkl              ← NetworkX DiGraph (optionally Fernet-encrypted)
    behaviour.json         ← per-symbol hit counts, user profile, error patterns
  index/
    ast_index.json         ← reverse symbol index + file records
    manifest.json          ← git SHA + platform info for integrity checks
    summaries.json         ← LLM architectural summaries (Level 1–3)
  memory/
    episodic.json          ← append-only event journal
  sessions/
    <uuid>.json            ← conversation session files
    current.json           ← pointer to most-recent session
  errors/
    <date>.log             ← daily error logs (full tracebacks, never shown to users)
  learnings/
    learnings.json         ← structured learnings: decisions, bugs, prod issues
Everything under .cognirepo/ is .gitignored by default — never committed.
Fernet encryption is opt-in at storage.encrypt: true in config.json.
CLI reference
# Setup
cognirepo init                  # scaffold + configure; auto-indexes + auto-summarizes
cognirepo setup-env             # interactive API key wizard
cognirepo test-connection       # test API key connectivity
cognirepo migrate-config        # migrate deprecated config keys

# Indexing
cognirepo index-repo [path]     # AST-index a codebase
cognirepo summarize             # generate LLM architectural summaries (auto-prompted on init)
cognirepo seed --from-git       # seed behaviour weights from git history
cognirepo verify-index          # verify AST index integrity
cognirepo coverage              # per-directory symbol counts

# Querying
cognirepo ask <query>           # route through multi-model orchestrator
cognirepo retrieve-memory <q>   # similarity search
cognirepo search-docs <q>       # full-text search in .md files
cognirepo log-episode <event>   # append episodic event
cognirepo history               # print recent episodic events
cognirepo sessions              # list recent conversation sessions

# Memory management
cognirepo store-memory <text>   # save a semantic memory
cognirepo user-prefs            # view/set global user preferences
cognirepo prune [--dry-run]     # prune low-score memories

# Health & monitoring
cognirepo prime                 # generate session bootstrap brief
cognirepo status                # live retrieval signal weights + index health
cognirepo doctor [--fix]        # full health check; --fix auto-repairs common issues
cognirepo benchmark             # run quantitative value benchmarks

# Organization
cognirepo org create <name>     # create local organization
cognirepo org link <org> [path] # link repo to organization
cognirepo org list              # list organizations

# Daemon management
cognirepo list                  # list MCP servers, running daemons
cognirepo watch                 # manage background file-watcher daemon
Future Plans
Priorities drawn from the v0.3.0 benchmark findings and community feedback. Now at v2.0.0 — some items below have since landed; each is annotated where that's the case.
Near-term
- Go call-graph indexing — done (COGNIREPO-203): Go receiver-qualified method calls
(
recv.Method()) now resolve throughwho_calls/CALLS edges — tree-sitter's Goselector_expressionnames its method fieldfield, notproperty(the JS convention the extractor previously assumed), so method calls were silently dropped; fixed in_ts_collect_calls(intelligence/indexer/ast_indexer.py). A second bug in the same function — a call-collection recursion depth cap of 12, too shallow for a Go method wrapping an if-statement around a composite-literal call argument — was also raised (to 60). Go IMPORTS edges fromgo.mod-resolved local package imports are implemented (_extract_imports_go/_resolve_go_import_to_file). Live-verified againstcognirepo_test_repo/advanced/moby: 4/4 hand-verified callers resolved (100%, vs. the 90% target) after both fixes. cognirepo ask— done: multi-model orchestrator (QUICK/STANDARD/COMPLEX/EXPERT tiers) is implemented and wired as a real CLI command (_cmd_ask_local,interface/cli/main.py). Streaming REPL mode (see Longer-term) is not yet built.- Incremental re-index on save — done: the file-watcher daemon (
cognirepo watch) debounces writes (config.json→indexing.debounce_ms, default 500ms) and batches indexer/graph saves;tests/test_watcher_debounce.pycovers this including flush-on-shutdown. - CLAUDE.md mandatory-call relaxation — benchmark feedback (Moby tests) flagged that forcing
context_packbefore every file read adds latency under memory pressure. A--fastmode that skips the tool-first gate for files under 50 lines is not yet implemented.
Medium-term
- Kubernetes / 2M-LOC scale validation — K8-1 through K8-5 test suite not yet completed. Goal: full scheduling-decision trace at < 8 000 tokens with CogniRepo vs. > 50 000 without.
- Plugin-registry pattern detection — done (COGNIREPO-203): a static, annotation-only
heuristic pass tags symbols reachable via dynamic dispatch — celery-style
@task/@shared_taskdecorators,register(...)-style plugin-registration calls, Python__init_subclass__hooks, and packaging entry-points (pyproject.toml[project.entry-points.*]/setup.cfg[options.entry_points]) — withdispatch:"dynamic"plus aRELATES_TOedge to adynamic_dispatchCONCEPT node (_detect_dynamic_dispatch,_apply_entry_points_dispatchinintelligence/indexer/ast_indexer.py). Annotation-only by design — never fabricates a CALLS edge. Live-verified againstcognirepo_test_repo/medium/celery's real@shared_taskfunctions. - BM25 over symbol names — partially done:
core/_bm25.pyis used byintelligence/retrieval/hybrid.pyas the circuit-breaker fallback ranker (and by episodic search) when embeddings are unavailable, but it isn't yet the primary ranking signal for symbol-name partial-match recall (e.g.HttpClientmatchinghttp_client) in the normal (embeddings-available) retrieval path. - Cross-session memory warm-up — Ansible benchmark noted episodic/memory retrieval is low-value on fresh sessions.
cognirepo primeexists but is not run automatically oninit; will make it opt-in default.
Longer-term
cognirepo askstreaming REPL — full interactive session with tier routing, session persistence, and sub-agent delegation.- Ruby, PHP, C#, Swift grammar support — tree-sitter grammars exist; need
_TS_FUNCTION_TYPES/_TS_CLASS_TYPESmappings and call-extraction rules per language. - Similarity edges in knowledge graph — done (COGNIREPO-202): post-index FAISS k-NN pass over already-embedded FUNCTION/CLASS symbol vectors adds a
SIMILAR_TOedge (cosine ≥ 0.80, max 5/node, cross-file only) between near-duplicate symbols, both directions. Gated viaconfig.json→indexing.similarity_edges(default on below 20k candidate symbols). Weighted (discounted) intointelligence/retrieval/hybrid.py::_graph_score. - VS Code / JetBrains extension — surface
lookup_symbol,context_pack, andwho_callsdirectly in the editor sidebar without requiring an MCP-capable host.
Documentation
| Document | Description |
|---|---|
| docs/ARCHITECTURE.md | System design, component responsibilities, data flow |
| docs/architecture/SPECIFICATION.md | Technical spec, complexity signals, storage layout |
| docs/USAGE.md | Complete CLI, MCP, and Docker reference |
| docs/METRICS.md | Quantitative benchmarks: token reduction, lookup speedup, recall |
| CONTRIBUTING.md | How to add adapters, tools, and language support |
| SECURITY.md | Vulnerability reporting, data handling, trust model |
| docs/LANGUAGES.md | Language support details and roadmap |
Community
Questions, feedback, or just want to see what others are building? Join the CogniRepo Discord.
Want to contribute? See CONTRIBUTING.md — issues labeled
good first issue are
scoped for a first PR.
License
CogniRepo is licensed under the MIT License.
- Free to use, study, modify, and distribute
- Use in proprietary products and commercial services — no restrictions
- No requirement to open-source your application
See LICENSE for full details.
Related MCP servers

Lexicon
Fixes the names and jargon speech-to-text gets wrong before your agent acts on a dictated prompt.
Phantom Secrets
Protect AI agents from leaking API keys by replacing real secrets with scoped phm_ tokens and a local proxy.
webfetch
License-first federated image search with attribution, dimensions, and download tooling.

Track DSA/LeetCode practice with spaced repetition, ships with NeetCode 150.

KAKA, an ancient amnesiac crow from klaash.club. Get a live introduction or his response log.

io.github.ashwinvis/scb-opendata-mcp
Statistics Sweden’s open data made available as an MCP server, using Python and FastMCP