qikly MCP Server
io.github.gal-a/qikly
Generates tests from acceptance criteria, then converges code with an agent that never sees them.
What is the qikly MCP server?
The qikly MCP server is a test-driven development tool that generates test suites from acceptance criteria before any code is written, then uses an AI agent to implement code against those tests without ever revealing the criteria to the coding agent. This structural separation ensures the tests remain independent of the implementation, catching bugs the code itself might not reveal.
qikly solves the problem of AI-generated code and tests both passing when written by the same model. It splits the workflow: a test-generation agent writes integration and system tests from your acceptance criteria, then a separate coding agent implements the code without seeing those criteria—only receiving pytest failures to fix. The result is an executable pytest suite and complete audit trail proving the code meets your specification, not just that it passes tests shaped by the same model that wrote it.
How to install qikly
Copy-paste configuration for popular MCP clients.
QIKLY_PROJECT_ROOTThe folder holding your tasks, the one with inputs_private/. Set it when your editor has a different folder open, which is common.
Tools & capabilities
Tools this server exposes to the agent.
--score-code and --score-tests— Mutation-based fault injection: plants faults in your code and runs your existing test suite against them to identify gaps in test coverage, with no API key required.--scaffold— Generates a project structure and task file from your module, ready for test generation and code convergence.--example— Creates a bundled example project (ADAS_HEADWAY) in your directory to demonstrate the full workflow.--explain— Shows offline what each agent receives: displays the specification with acceptance criteria withheld from the coding agent, proving the separation mechanism works.--demo— Runs a complete end-to-end example with API calls, generating tests and converging code in under a minute.--init and --criteria-from— Converts existing code into a task file, or lifts acceptance criteria from tickets and specifications.--generate-criteria and --check-criteria— Drafts acceptance criteria from requirements alone, and detects contradictory criteria before code generation begins.--refine-criteria— Reads a converged implementation to propose additional criteria the initial specification may have missed.Test generation and repair loop— Generates integration, system, and unit tests; runs pytest; on failure, sends only the failure text (not criteria) back to the coding agent to produce FIX and PATCH until convergence or retry budget exhaustion.
Use cases
- Verify that AI-generated code for data transformation (ETL, merge, calculation, validation) actually meets your acceptance criteria, not just passes tests written by the same model.
- Audit existing test suites by injecting faults into your code and measuring which bugs your tests catch and which they miss.
- Generate comprehensive test coverage from a written specification before writing any implementation code.
- Create reproducible, auditable records of why each line of code exists: which assertion forced it, what the model concluded, and what changed in each repair cycle.
- Ensure independent verification in regulated domains (automotive, medical devices, fintech, defence) where the test suite must not be shaped by the implementation it judges.
qikly MCP server FAQ
qikly is a test-driven development tool that generates test suites from your acceptance criteria before any code is written, then uses an AI agent to implement code against those tests. The key innovation: the coding agent never sees the acceptance criteria—only pytest failures—ensuring tests remain independent of the implementation.
The `--score-code` command (mutation-based fault injection on your existing tests) is completely free and requires no API key. Setup commands like `--scaffold` and `--example` are also free. Running `--demo` or full convergence requires an API key and costs under a cent per run.
Install via pip: `pip install --upgrade qikly`. Then run `qikly --install-skill` to teach Claude Code, Cursor, Codex, Gemini CLI or GitHub Copilot how to drive qikly. For VS Code, use the one-line MCP setup badge in the README.
No authentication is needed for `--score-code`, `--scaffold`, `--example`, or `--explain`. Running `--demo` or full test generation and code convergence requires an API key (OpenAI, Anthropic, or other supported providers configured in your environment).
Developers and teams using AI coding agents on self-contained Python modules (ETL, calculations, validation, merging). It works best for one module at a time in small to mid-sized repositories, and fits naturally in regulated domains (automotive, medical, fintech, defence) where verification must be independent.
A pytest suite (integration, system, and unit tests), JUnit XML reports, and a complete audit trail recording the provider, model, settings, every failing test, every FIX with root cause analysis, and every PATCH as a diff. The suite is durable and reproducible—you keep it and run it in CI.
README (reference)
Source of truth, from the repository.
qikly
<!-- The MCP Registry proves that whoever lists a server owns the package it points at, by looking for this line in the README that PyPI serves. It is a comment so it does not render, and it must match the `name` in server.json exactly. --> <!-- mcp-name: io.github.gal-a/qikly -->




New: an agent Skill.
qikly --install-skillteaches Claude Code, Gemini CLI, Codex, Cursor or GitHub Copilot how to drive qikly. What the Skill contains.
The problem: Your AI writes both the code and its tests. How do you know the tests are really valid?
Who it is for: a developer or team pointing an AI coding agent at a
self-contained Python module that transforms data, for example an ETL step, a
merge, a calculation or a validation routine, who does not want to trust a
green suite when the same agent wrote both the code and the tests. It suits one
module at a time in small to mid-sized repositories: when a test fails, only
the files that failure names are loaded, so runs stay small and quick. It fits
most naturally where verification already has to be independent, such as
automotive, medical devices, fintech and defence: ADAS_HEADWAY, a bundled
example, checks following distance from forward-radar samples. See What it is for.
Start here
pip install --upgrade qikly
--upgrade rather than a bare install, because the Skill ships inside the
package: pip install qikly on a machine that already has an older one
prints "Requirement already satisfied", changes nothing, and
--install-skill then writes that older Skill.
Start on your own code, not on ours. The first row needs no API key, no task file, no specification and no decision from you, and it answers the question you probably arrived with.
| If you want to | Run | Costs |
|---|---|---|
| Find out what your tests would not have noticed | qikly --score-code my_module.py --score-tests tests/ | nothing, no API key |
| Point it at your own module and write tests from a spec | qikly --scaffold my_module.py | nothing to set it up |
| Start from a finished example in a project of your own | qikly --example | nothing to set it up |
| See the split for yourself, on a bundled task | qikly --explain CALC_TAX | nothing, no API key |
| Watch a real run end to end | qikly --demo | needs a key, about half a minute and well under a cent |
The first row is the one to try in a meeting. Point it at a module or a package, with the tests you already have. It plants one fault at a time in a copy of your code, runs those tests against each one, and names the faults nothing noticed. Both flags are needed: one says what to break, the other says what should notice. No model is called, nothing of yours is modified, and no code leaves your machine. It says nothing about qikly and everything about the suite you are already trusting.
--demo works in a throwaway demo/throwaway_<timestamp>/ folder it expects you to
delete. It is for watching, not for building in. --example and --scaffold
create a real project in the directory you are standing in, and those are the
two to build from.
Then five steps from your module to a first run.
qikly.com is the two minute version of this page, and the one to send to somebody else.
The idea
Imagine a student who writes the exam paper, writes the answer key, and then sits the exam. They pass, and nobody would accept that as evidence they know the material. That is what happens when one model gets a specification containing the acceptance criteria and writes both the code and the suite that checks it: everything goes green, and the green means nothing.
qikly takes the answer key away from the student. It generates a test suite from the acceptance criteria, then writes an implementation and repairs it against that suite until every test passes or a retry budget runs out, recording every failure, every piece of reasoning and every diff.
<!-- An image rather than a mermaid block, because PyPI prints mermaid as source. It is rendered from the diagram in docs/design_1_case_study.md by tools/render_flow_diagram.py, and a test fails when the two drift. --> <img src="https://raw.githubusercontent.com/gal-a/qikly/main/docs/images/qikly_flow.png" width="660" alt="How a run works. The full specification splits into requirements plus interface, which both agents receive, and acceptance_criteria, which only the test-writing agent receives and which never reaches the coding agent. The coding agent writes the implementation, the test-writing agent writes the pytest suite, and the suite runs. A pass gives converged outputs: code, suite and audit trail. A fail sends pytest's output for the failing tests back to the coding agent as the repair loop, with no acceptance criteria, until the retry budget is spent and the run stops without converging but keeps the audit trail. Unit tests alone are written last, from the code.">The part that makes the result mean something: the coding agent never sees
acceptance_criteria. It gets the specification with that section stripped
out, the same vague brief a developer works from, while test generation gets
it in full. When a test fails, the agent sees pytest's output for that test and never
the acceptance criteria. Without that asymmetry both sides read the same spec
identically and every test passes first try, which proves nothing.
Purple is what the coding agent can see. Teal is what the standard is
written from. They never touch. A run that never converges is still worth having: it exits
non-zero, names the blocking tests, and keeps the same complete record. The purple arrows are the repair loop, and that is where
almost all of a run happens: a failing suite sends the agent the failure text
and nothing else, it produces a FIX and a PATCH, and the suite runs again,
until the stage passes or the retry budget runs out. It never sees the criteria
themselves, so it cannot write code shaped to a bar it was handed.
tests/test_withholding.py fails the build if any call site lets one through.
A run works through three stages, integration then system then unit:
- Integration and system tests are generated first, from the spec alone, before any code exists. They cannot see an implementation because there is not one yet.
- The coding agent writes the implementation, from the spec minus the criteria.
- pytest runs. On failure the model produces a FIX (failure summary, root cause, plan, and the files it intends to touch) and then a PATCH (a unified diff of only those files), applied all or nothing. Repeat until the stage passes or the budget is spent.
- Unit tests are generated last, once real code exists for them to name. This is the only stage allowed to see the implementation.
- Clearing a stage re-runs the earlier ones, so a later fix cannot silently break something that already passed.
Every arrow back into FIX carries the pytest error text and nothing else, which means the failing tests and not the specification they came from. Unit tests come last because they are the only ones that need to name real functions, which makes them the only stage allowed to read the implementation. Re-running the earlier stages after each success is what stops a later repair quietly breaking something that already passed.
Test generation sees the requirements, the input and output contract, and every acceptance criterion in full. It writes integration, system and unit tests against the standard.
The coding agent sees the same specification with the criteria section removed, plus the text of whatever test just failed. The same vague brief a developer usually works from.
Two ways to get a test suite, and what each can prove
<!-- Two columns, with each row's label inside its cells, so the table stays narrow enough to wrap on a phone instead of scrolling sideways. -->| Code-derived suite<br><sub>most commercial test generators, and qikly's own unit tests</sub> | Spec-derived suite<br><sub>qikly's integration and system tests</sub> |
|---|---|
| Written from the code as it is today | Written from the acceptance criteria you wrote |
| You supply nothing but the repository | You supply a written statement of what correct means |
| Catches behaviour changing tomorrow | Catches behaviour being wrong today |
| Cannot catch the code being wrong now: today's bug becomes tomorrow's assertion | Cannot catch anything nobody wrote down |
| Right choice when nobody wrote the intent down and you need a safety net | Right choice when the intent exists in a ticket, a spec page or a Gherkin file |
Both are useful and they answer different questions. qikly is not purely one
or the other: integration and system tests are written from the criteria
before any code exists, the unit stage is written last from the code that just
passed them, and --refine-criteria reads a converged implementation to
propose criteria the first draft missed. Each of those reads the code on
purpose, and none of them can question it.
What makes this different
The tests come from the standard, not from the code. This is the one that matters most. Every other AI test generator in this space writes its tests from an implementation that already exists, so it can only describe what the code already does. That makes an excellent regression harness, and it cannot tell you the code is wrong. qikly writes the integration and system suites from the acceptance criteria before any implementation exists, so the standard cannot have been shaped by the thing it judges.
The withholding is a mechanism you can watch. Not a prompt asking a model to ignore a section, and not a convention someone has to remember. One command prints what each side is given and the difference between them, offline and free:
qikly --explain <MY_TASK> # e.g. qikly --explain MERGE_SALES
Eleven criteria go to test generation. Twelve lines are removed before the
coding agent sees the same file. tests/test_withholding.py fails the build if
any call site ever lets one through, including one added next year by someone
who has never read this. It is a property of the code, and it takes thirty
seconds to check.
What you get is an executable suite you keep. The output is pytest files and JUnit XML. Read them, run them, put them in CI, and when one fails in six months it fails for a reason you can inspect and argue with. A suite is a durable asset in a way a model's verdict is not: a verdict cannot be re-run against tomorrow's commit.
It helps you write the standard, not just check against it. --init and
--scaffold turn existing code into a task, --criteria-from lifts criteria
out of a ticket you already wrote, --generate-criteria drafts a first bar from
requirements alone, and --check-criteria looks for two statements anywhere
in the specification that no implementation could satisfy at once, including
two acceptance criteria that disagree with each other.
Every run is reproducible, and the whole trail is kept. A run records the provider, the model, the settings and the version that produced it, next to every failing test, every FIX with its stated root cause, and every PATCH as a diff. You can read back exactly why a line of code exists: which assertion forced it, what the model concluded, and what it changed. The record survives a run that never converges, which is when you most want it.
"Why not just use two different models?"
It is the first thing most people ask, and it does help a little. It does not reach the underlying issue, because both models still read the same criteria and so both still write to them: the code is still built to satisfy the standard it is about to be judged by, and changing who types it does not change what they were shown. It is also a habit rather than a mechanism, and nothing checks the two stayed different.
The two compose nicely, incidentally, since qikly picks a provider and model per agent role. You can withhold and use two models.
"Why not just add a reviewer agent?"
The newer version of the same question, and the one worth answering carefully, because independent verification steps are now shipping in mainstream coding agents: a second agent, often from a different model family, reviews what the first one produced.
It helps, and it does not reach this. A reviewer given the same specification has read the same acceptance criteria, and resolves the same ambiguity the same way. It will catch a mistake that is visible from that context: an inconsistency, a requirement plainly skipped, an obvious bug. It cannot catch the case this tool is built for: a line that could be read two ways, read once, with both the code and the standard written from that single reading. Nobody is wrong, so nothing looks wrong.
The problem was never that nothing was checking. It is that everything checking had already seen the answer key. Withholding is what makes the check structural rather than one more opinion drawn from the same context, and it is enforced by a test rather than by an arrangement someone has to remember to keep.
There is a second difference, and it outlasts the run: a reviewer emits a verdict, and this emits a pytest suite you still have in six months.
"Doesn't a failing test give the criteria away?"
It gives away one case, and that is by design. When a test fails, the coding agent sees pytest's output for it: the test name, its source down to the failing line, its docstring if it has one, and the assertion error. In the case study, that a tax rate of 150 was accepted when it should not have been. Since a test's docstring often paraphrases the rule it was written from, assume the criterion behind a failing test is effectively visible once it fails.
Of the tests it has not failed, it sees the names and nothing else. Pytest
lists every test it collected, so the agent knows a check called
test_tax_exempt_zero_rate exists and is green; it does not see that test's
body, docstring or assertions.
What the agent never receives is the specification itself. The acceptance criteria are stripped from the task before it is prompted, and no criteria text reaches a FIX or PATCH prompt.
Three things travel through a failing test, and they are not equally costly to close:
| What travels | What it gives away | Needed for the repair? | Default |
|---|---|---|---|
| The docstring prose | a paraphrase of the criterion | yes | shown. Narrow it with diagnostic_feedback: staged, which starts at the least detail that can locate a fault and adds more only when a patch changes nothing |
| Test names, passing ones included | that a rule exists, often with its subject: test_tax_exempt_zero_rate | no | shown. Closing it means dropping pytest's -v, which is where the per-test statuses the reports are built from come from. A trade, named rather than taken |
# Criteria: 2 markers | which criterion this test came from, and how many exist | no | withheld. A criterion's number is not a rule, so this is the one narrowing that costs nothing. traceability_markers_visible: true restores it |
The markers stay in the suite on disk either way, so the coverage report and anyone reading the tests still see which criterion each one enforces.
That does not undo the separation, because independence is a property of how the suite was written, not of how much feedback the code's author receives afterwards. The integration and system suites are generated from the criteria before any implementation exists, and nothing the coding agent learns later can reshape a test that is already written. A repair that games the one visible failure still has the rest of the suite in its way, and earlier stages run again each time a later one clears.
It is the position a developer is in when CI goes red: they see what broke, not
the test plan. The agent in the case study wrote tax_rate > 100 only because a
test told it 150 was wrong. Had it been handed the criteria, it would have
written the bound first time, and the green would have proved nothing.
Design rationale, and the harder problem of where acceptance_criteria comes
from in the first place: docs/design_1_case_study.md,
the first of three parts.
What it is for
Built for self-contained Python modules that transform data, not for a large existing repository: ETL, merges, calculations, validation. That is the layer where a wrong answer looks like a right answer, and where a test written from the rule is the only thing that catches it.
Where it does not fit today: an existing large repository. PATCH prompts load only the files a FIX names, and while a large file is now excerpted rather than loaded whole, there is no cross-file index. See Where it fits today.
How to use the tools in this project
Four ways in, and the table under the quick start says which command each one needs:
-
Verify code you did not write. Supply an implementation through
seed:and the suite is written from your acceptance criteria by an agent that never reads that code. A suite generated from the same context as the code is a model agreeing with itself. A module or a whole package: pointseed.implementationat a directory and it is copied in under its own name, sofrom mypkg.money import to_centsresolves as it does in your own tree and every module in it can be repaired.The limit is worth saying plainly: qikly cannot know what the author of supplied code saw. Withholding is a property of a run qikly performed, not of a file you hand it. If the same person or model wrote that code with the criteria open, this gives you an independent suite, not an independent author. What it does give, always, is a suite that was not derived from the code, which is the half a code-derived generator cannot give you at all.
-
Start from a spec. No code yet: get a first implementation and the suite that justifies it, in
outputs/, never in your source tree. -
Bring your own tests. Seed any stage and the loop becomes a repair procedure rather than a generator.
-
Run a catalog unattended. Non-zero exit on any non-convergence, so a scheduler or CI job can run many specs and keep the reports.
The free commands, in detail
Three commands that make no model call, need no API key, and cost
nothing. --explain is the first row of Start here; this
is what it and its two neighbours actually do.
qikly --explain MERGE_SALES   # what each side is shown, and the difference
qikly --validate              # check your task files: YAML, criteria, fixtures
qikly --explain MERGE_SALES --json
qikly --explain MERGE_SALES --html   # the same, as a page to share
--explain is the one worth running first. It prints the acceptance criteria
that test generation receives, then the same task file as the coding agent
receives it, then the diff: on MERGE_SALES, all eleven acceptance criteria
are removed, along with the acceptance_criteria: key they hang off. It builds
those strings through the same function a real run
uses, so it shows the mechanism rather than a description of it.
Add --html and it also writes qikly_explain_MERGE_SALES.html: both views
side by side with every withheld line highlighted, in one file that loads
nothing from anywhere. Attach it to a pull request, put it in a slide, or
screenshot it for a post.
--validate reads your task files and nothing else: that they parse, that
acceptance_criteria is a list rather than one long string, that fixture paths
resolve, and that criteria name values instead of adjectives. It is also
available as a pre-commit hook, qikly-validate, deliberately the free check
rather than the paid one.
What --demo looks like
The second row of Start here, in full. It needs a provider key:
export GEMINI_API_KEY=...     # PowerShell: $env:GEMINI_API_KEY = "..."
qikly --demo
Python 3.10+ and GNU patch; on macOS run brew install gpatch first.
It runs a bundled task end to end in a throwaway demo/throwaway_<timestamp>/
folder, in about thirty seconds, writes nothing outside it, and expects
you to delete the folder afterwards rather than build there.
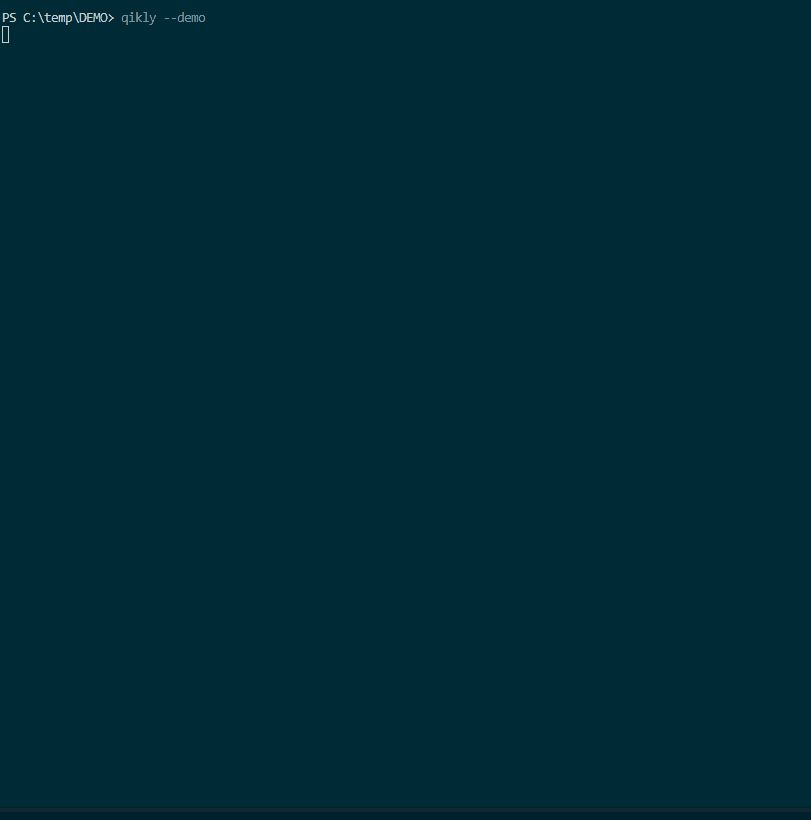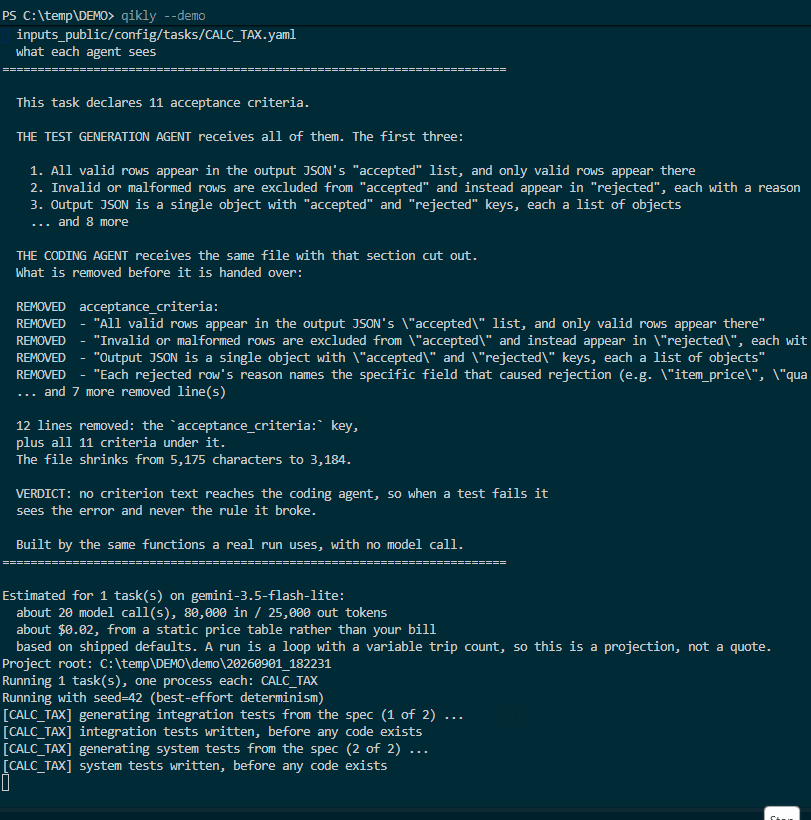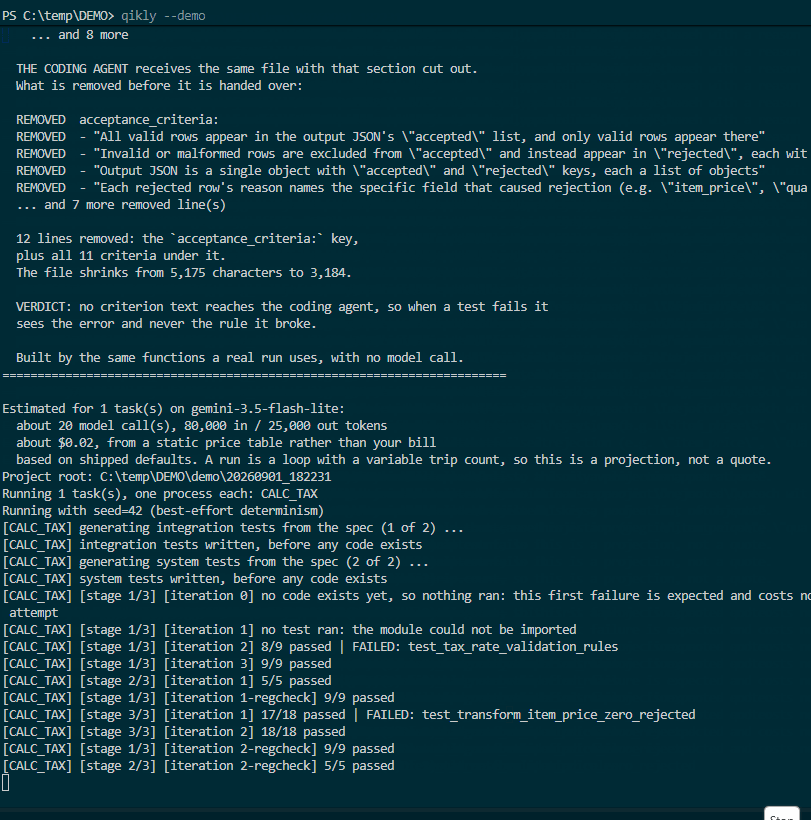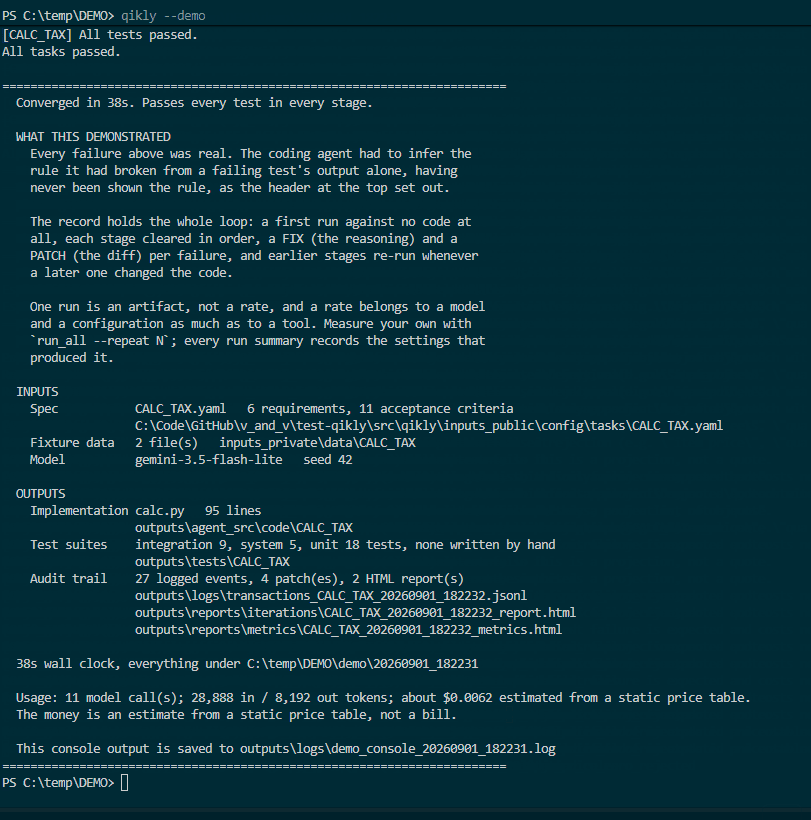
That is a real run on gemini-3.5-flash-lite, 38 seconds, not sped up.
Tried it? Tell us what happened, whether it worked, stalled or never got past install.
Running
python run.py                            # every task found
python run.py --tasks ETL_ADDRESS        # one
python run.py --tasks ETL_ADDRESS,ETL_EMAIL
python run.py --demo --tasks MERGE_STOCK # isolated, any task
Each task runs in its own process, concurrently, with console output prefixed
[task_id]. Exit code is non-zero if any task did not fully converge.
Expect some runs to stall, by design. Roughly 8 runs in 10 finish with the code passing every integration and system test. Roughly 6 in 10 pass everything including unit tests. Nearly the whole gap between those two figures is the unit stage.
Those are round numbers because they were measured three times: a 427-run sweep,
a 140-run sweep sixteen days later on the same tasks and settings, and a 400-run
sweep after correcting the benchmark itself, when eight of the ten tasks turned
out to be carrying acceptance criteria that no input row could trigger. All
three landed inside each other's intervals. All three used
gemini-3.5-flash-lite, a small cheap model chosen to make repeated sweeps
affordable, so treat them as a floor. Three sweeps agreeing is worth more than
any one of them's decimal places, so the decimal places are not quoted.
A run that exhausts its budget exits non-zero, names the tests that blocked it, and keeps the full record. It never reports success on code its own tests reject.
Thirteen example tasks ship with the tool across five domains, listed in docs/design_3_mechanism.md.
Measuring rather than producing. One run is an artifact, not a rate: the same task with the same seed converges on some runs and not others. To claim how often anything converges, repeat the sweep and read the interval:
python -m qikly.orchestrator.run_all --repeat 10
That writes an aggregate report with confidence intervals and groups the non-converging runs by what they got stuck on. Details in docs/design_3_mechanism.md.
When a run does not converge
A stall is a normal outcome, not a broken tool: the run exits non-zero, names the blocking tests, keeps the whole record, and ships nothing.
The first thing to try is a stronger model, which moves convergence more
than any setting in this file and costs one environment variable. After that,
in triage order: read the timeline report, check for a collection error
(nothing ran at all), rule out a forgotten setting with --trends, look for the
same patch repeating (a criterion fighting the model's priors), and run
--check-criteria, --validate and propose_fixtures.
Each of those, with the signature to look for and the fix: docs/TROUBLESHOOTING.md.
Questions people ask before they start, including what runs before you commit an API key and whether anything leaves your machine: docs/FAQ.md.
Pointing it at code you already have, including which of your modules it may change and what a run says when the defect turns out to be in one it may not: docs/EXISTING_CODE_AND_HELPERS.md.
Output
Everything is namespaced by task_id so concurrent runs never collide:
| Path | Contents |
|---|---|
outputs/agent_src/code/<task_id>/ | The implementation the coding agent wrote. Cleared (backed up under old/<timestamp>/) at the start of each run. |
outputs/tests/<task_id>/{integration,system,unit}/ | The generated test files for this run. |
outputs/data/<task_id>/ | The task's actual output artifact (e.g. output.json). |
outputs/logs/transactions_<task_id>_<run_timestamp>.jsonl | Append-only structured log of every test run, FIX, PATCH, and apply outcome: the source of truth for the run. |
outputs/logs/patches/<task_id>/<run_timestamp>/<fix_id>.diff | Every patch the agent generated, whether or not it applied. |
outputs/reports/junit/<task_id>_<run_timestamp>.xml | JUnit XML for the run, one <testsuite> per stage. The one artifact here another system reads: import it into Xray, qTest or TestRail, or publish it from CI. Per-stage files sit beside it, each holding that stage's final state. A stage that never ran is absent rather than reported as an empty pass. |
outputs/reports/iterations/<task_id>_<stage>_<run_timestamp>.txt | Live-appended one-line-per-attempt pass/fail summary (what streams to the console). |
outputs/reports/iterations/<task_id>_<run_timestamp>_report.html | Start here. A single-page debugging timeline for the run. Open it in a browser. Generated automatically at the end of every run.py invocation (path printed to console), or on demand: python -m qikly.orchestrator.reports.report [--task ID] [--run TIMESTAMP]. Links to the matching metrics report; stays focused on the narrative, no duplicated numbers. |
outputs/reports/metrics/<task_id>_<run_timestamp>_metrics.html | A numbers-first companion: a KPI row (iterations, FIX/PATCH attempts, regressions caught, apply-failure rate, run duration), a per-stage iteration chart, and a FIX/PATCH outcome breakdown. Links back to the matching debugging timeline. Same generation triggers as the timeline report, or on demand: python -m qikly.orchestrator.reports.metrics_report [--task ID] [--run TIMESTAMP]. Scoped to one run today; see Where it fits today. |
outputs/reports/run_summary/<task_id>_<run_timestamp>.json | The same numbers as the metrics report, as JSON instead of HTML, so runs can be compared across time by a script. Written automatically at the end of every run.py invocation. Stays on your disk. The only network calls this project makes are to your configured LLM provider and, unless disabled, a check for a newer release at startup (see Version check). |
outputs/reports/aggregate/aggregate_<timestamp>.{html,json} | Many runs at once, rather than one: see Running everything at once for what it reports and why. Written by --repeat, or on demand: python -m qikly.orchestrator.reports.aggregate_report [--task ID] [--last N]. Reads the run_summary/ JSONs only, so no LLM calls and free to re-run. |
Two kinds of test data, from two different sources
Worth knowing before you prepare your fixture data, because it decides what your data has to contain:
| Where the rows come from | Which stages use them | |
|---|---|---|
| Invented | The test-writing agent makes them up from your acceptance_criteria, and writes them straight into the Python | unit, integration |
| Yours | Your fixture data (e.g. the CSV files named in the task's inputs: list) | system |
The test-writing agent never sees your fixture data. It is handed the task file and, for unit tests, the code, and nothing else, so when it writes
invalid_prices = ['0', '0.00', '-5.00', 'abc', '']
those five values came from reading a criterion, not from a row in your files.
Your data still decides what gets proven. The system stage is the only one that runs the real pipeline over the real files. So a criterion no row reaches is checked in miniature by an invented row, and never checked on the path your code will actually take. The run goes green and one rule was never exercised end to end. That is why the bundled sample data carries awkward rows on purpose, and why there is a command for finding the gap:
qikly --propose-fixtures --tasks MY_TASK
It reports which criteria nothing in your data reaches and proposes a row for each, next to the criterion it was proposed for. It writes a file for you to read and copy from, and never edits your fixtures: a row is only right or wrong relative to the criterion it was proposed for, and fixtures that grow in whatever direction a model finds interesting stop resembling the data you actually process.
Your own data, in full
The fourth row of Start here, in full: make the two directories, drop your fixture data in, write the task file, run it. Nothing is written into the package and nothing is written into your source tree. The walkthrough with the task file explained field by field is in docs/QUICK_START_ON_YOUR_OWN_DATA.md.
qikly --init                    # creates inputs_private/ and a starter task
qikly --tasks MY_TASK
Want to watch it work before writing anything? qikly --example adds a
worked example that runs as it stands: a module, the two task files a
scaffold of it produces, sample data, and the requirements and
acceptance_criteria already written, each at the path a real task uses.
It is the one command here that puts a file in your project root,
my_metrics.py, and you can delete the lot when you are done. Which
starter is which, --init against --example, is set out in the quick
start below.
docs/QUICK_START_ON_YOUR_OWN_DATA.md has the
rest: the task file field by field, getting the split between requirements
and acceptance_criteria right (decisions in one, their consequences in the other, and the gap between them is the whole mechanism),
lifting criteria out of a ticket you already wrote, seeding your own
implementation or test suites, where each file is read from, and proposing the
fixture rows a criterion needs before any test can reach it.
Configuration and LLM provider
Gemini by default; OpenAI and Anthropic are supported. One provider per run.
export GEMINI_API_KEY=...
qikly --demo
docs/CONFIGURATION.md has every
environment variable, the settings.yaml keys, timeouts, how much determinism
each provider actually gives you, and how to notice an SDK changing under you.
Keys, PowerShell, CI and what a wrong key looks like:
docs/PROVIDER_KEY_SETUP.md.
Version check
On startup the CLI makes one request to pypi.org and prints a single line if
a newer release exists. Set QIKLY_NO_VERSION_CHECK=1 to turn it off.
It never changes a run: every failure path is silent, the timeout is 1.5 seconds, it happens once per invocation rather than once per task, and it reads only the public PyPI and GitHub release indexes you already rely on to install software.
Where it fits today
Stated plainly, because the fit matters more than the feature list.
It targets self-contained Python modules. PATCH prompts load only the files
a FIX names. A file over roughly 16,000 characters is no longer loaded whole:
it is parsed, the definitions the FIX and the failure name are reproduced in
full, everything else collapses to a one-line signature, and elided ranges are
marked so a diff still applies. Raise the threshold with QIKLY_MAX_FILE_CHARS.
What that is not is a repository story: there is no cross-file index, and
excerpting reduces size rather than bounding it. A module with four hundred
functions still yields four hundred signature lines, so 57k characters becomes
30k, which is smaller and still large. The retrieval is a lookup rather than a
similarity search, because the FIX and the failing test already name the
symbols.
GNU patch is required, not any patch. Apple and BSD ship an
implementation that rejects --fuzz, which is what lets a diff with slightly
wrong line numbers apply at all. qikly now tells you when it finds one, instead
of reporting it as an ordinary failed hunk while every remaining attempt in the
run regenerates diffs that could never land.
Patches apply without asking, by default. They land in the disposable
outputs/agent_src/code/ tree with a timestamped backup, never in your working
copy, and an unattended loop that stopped to ask would not be unattended.
--review-patches puts a person in the path, --dry-run generates every patch
and applies none. A declined patch is kept and logged, because a rejection is
evidence no test can produce.
Budget exhaustion is a normal outcome, not a rare edge case. A run that cannot satisfy its own suite exits non-zero, names the blocking tests, and ships nothing. That is the property worth having. Three of the four causes are defects in the specification rather than in the model, so most stalls are fixed by editing text: see the stall taxonomy.
Two stall signatures, and they mean opposite things. The same patch
repeating byte for byte is the model correctly disagreeing with an artificial
rule. No retry budget fixes that: widen the criterion, or move the decision
into requirements where the agent can read it as a given rather than as an
error to correct. A different patch each attempt, never resolving the same
test, is an ordinary bug that the failure text alone does not localise, and a
stronger model is the first thing to try. Compare successive diffs under
outputs/logs/patches/<task>/<timestamp>/ to tell which one you have. Stalls
concentrate in the unit stage, which is also the only stage written with sight
of the code.
Test generation can miss a criterion you wrote. A correct, hand-written
criterion can end up with no test asserting it, so the coding agent is never
forced to satisfy it. Root-caused to the test-generation prompt asking for
coverage of "properties the criteria say must hold" without requiring every
criterion to be covered, so long lists got sampled down. The prompt fix reduces
the gap rather than closing it. Treat as a live gap, and --explain plus
the generated suite are how you check it on your own task.
Criteria refinement can tighten a bar, not discover one. The reviewer reacts to what an implementation actually does, so it is good at finding validation gaps in behaviour the code already attempts and cannot surface a behaviour the requirements never asked for. How much it sharpens a bar is an open question.
One provider per run, and no cross-run trend reporting yet: the metrics report covers a single run.
Features
Split three ways, because a single list mixed things that are not alike: what the loop guarantees whatever you type, what you type, and what you are left holding afterwards.
What the loop does on its own
| What it does | |
|---|---|
| Withheld acceptance criteria | The coding agent never receives them. Enforced by tests/test_withholding.py, not by an instruction |
| Staged test generation | Integration, then system, then unit. Integration and system are written before any implementation exists, so they cannot be shaped to it |
| Regression re-checks | Every stage that has already passed is re-run after each later fix, so a repair cannot quietly break an earlier stage |
| Retrieval within a file | A module over ~16k characters contributes the definitions the failure names, in full, plus a one-line signature for everything else. Deterministic, AST-based, no index and no extra model call |
| Seeded inputs | Supply your own implementation or any test stage instead of generating it |
| Independence evidence | For code you supply, git is asked whether the criteria were settled before the implementation's first commit, and the answer is printed with the bounds of what it shows, because a run cannot enforce a separation it did not perform |
| Any provider | Gemini, OpenAI or Anthropic, selectable per agent role |
| Concurrent tasks | Each task in its own process, output prefixed [task_id] |
| Run provenance | Every summary records the model, provider, date and generation settings, because a convergence rate belongs to a configuration as much as to a tool |
| Approval gate | --review-patches prints each diff and waits for y/N; --dry-run generates every patch and applies none |
Commands
| What it does | |
|---|---|
| Show the withholding | --explain TASK prints what each side is given and the difference. No model call, no API key |
| Offline validation | --validate checks task files for free: valid YAML, criteria as a list, fixture paths that resolve, criteria naming values not adjectives |
| Scaffold from code | --scaffold FILE reads an existing module and writes a task that tests that code, or with --fresh one that writes a fresh implementation of the same interface |
| Draft criteria | --generate-criteria writes a first bar from requirements alone, for a task that has none |
| Score a drafted bar against yours | --compare-criteria TASK drafts criteria from your requirements alone, then reports what a generated bar would have missed, treating yours as ground truth |
| Contradiction check | --check-criteria asks whether any implementation could satisfy the description, the requirements and the criteria at once, and whether the criteria agree with each other, before a stage budget is spent |
| Import criteria from a ticket | --criteria-from FILE reads bullet lists, an "Acceptance Criteria" section, or Gherkin scenarios out of a ticket you paste into a file |
| Jira import | --criteria-from-jira PROJ-412 reads criteria from a named field or the issue description, through the same parser the file importer uses |
| Document plus code, in one command | --scaffold module.py --from-doc feature.md writes the task file with the criteria taken from the document and the interface read from the module. requirements is left for you on purpose: the coding agent reads it, and a feature page usually restates its own criteria in the prose above them. |
| Fixture proposals | A separate agent names the criteria no input row can trigger and proposes the smallest row that would. It never edits your data |
| Convergence trends | --trends shows each task's rate over time from summaries already on disk, marking any period where the model or settings changed |
| Machine-readable output | --json on --explain and --validate |
What you keep
| What it does | |
|---|---|
| Executable output | Plain pytest files you keep, read, and put in CI long after the run |
| JUnit XML | outputs/reports/junit/<task>_<timestamp>.xml, the format Xray, qTest, TestRail, Jenkins, GitLab and GitHub Actions all ingest |
| Full audit trail | Every test run, FIX, PATCH and apply outcome in an append-only log, plus HTML timeline and metrics reports |
| Cost forecast | Printed before a run starts, from your own history when you have any, labelled as a projection rather than a price |
| PR comments | --pr-comment renders the latest run as markdown; the template workflow updates one comment in place rather than adding many |
| Pre-commit hook | qikly-validate, the free check, so a hook never bills you for typing git commit |
| GitHub Action | gal-a/qikly@v0.5.7, uploading the suite, the code and the JUnit XML |
Use it in CI
Listed on the GitHub Marketplace as Qikly Test Generation.
The Action runs one task and keeps what came out: the generated pytest suite, the code that satisfies it, and a JUnit XML file that CI dashboards and test-management tools already read.
- uses: actions/checkout@v5

- id: qikly
  uses: gal-a/qikly@v0
  with:
    task: CALC_TAX
  env:
    GEMINI_API_KEY: ${{ secrets.GEMINI_API_KEY }}
Two working templates are in this repository, meant to be copied out rather
than run here:
qikly-example.yml
runs on demand, and
qikly-pr-example.yml
comments the result on a pull request.
Three things worth knowing before you wire it up.
It does not fail your build by default. A run that does not converge is a
normal outcome, not a broken pipeline, and a tool whose first impression is a
red X on someone's main branch does not get a second look. Set
fail-on-stall: true when you want it enforcing rather than reporting.
Every trigger spends money. Both templates are workflow_dispatch on
purpose. Move to on: pull_request once you know what a run costs you, and
scope it by paths: to the task files so an unrelated commit does not pay for
a run.
Two ways to pin, and the choice is yours. @v0 is a moving alias that
this project repoints at every release, so you receive fixes without receiving
a breaking change. @v0.5.7 is an exact pin that never moves, so nothing
changes under you and nothing reaches you either. The templates use @v0
because most people want the fixes; use the exact form if your policy requires
it.
Use it from your coding agent
qikly runs as an MCP server, so an agent in any MCP host can start a run and read the result without you leaving the conversation. It is tested in VS Code and Claude Code so far. With uv installed there is nothing else to install. In Claude Code:
claude mcp add qikly -- uvx --from "qikly[mcp]" qikly-mcp
In VS Code, the Install qikly MCP badge at the top of this page writes the same command for you.
No qikly tool returns your acceptance criteria, on success or on failure. Your agent sees which tests failed and the pytest output, never the rule it broke.
docs/mcp.md has the four tools, other hosts,
installing with pip instead, what to do when the server does not start, and
how to keep the generated tests out of your agent's reach.
Or as a Skill, which teaches rather than calls
qikly --install-skill
That copies a Skill into .claude/skills/qikly in the directory you are
standing in. A Skill is a folder your agent reads: it tells the agent when
qikly is the right move, which line of a spec is a decision the coder needs and
which is a consequence to withhold, what a stalled repair loop means, and which
commands cost nothing. No server, no configuration.
It loads, and is then used correctly, in Claude Code, Gemini CLI, Codex and
Cursor: first time in each, in a project with a rival testing skill installed
beside it and a request that never mentioned qikly. The agent had a competing
option and no hint, which is what makes that worth reporting.
--install-skill agents,
cursor or gemini write where those tools document their own folders, and
copilot writes the instruction file GitHub Copilot reads instead, which is
the one path here nobody has watched load yet.
The two are not alternatives. The MCP server is code, so it can enforce:
no tool returns your criteria, and a test fails the build if that ever changes.
A Skill is instructions, so it can only inform, and it says so itself. The
withholding is enforced by the tool whether or not the Skill is installed.
docs/skill.md has
what is in it, how to check it loads, and the difference stated in full.
Two free checks on what your tests are not measuring
Which criteria your data cannot reach. qikly --validate now says when a
criterion names a value no input row holds, because that criterion produces a
test which passes whatever the code does:
MY_TASK.yaml: criterion 2 names 0 for gap_m, and no row holds it.
`qikly --propose-fixtures --tasks MY_TASK` drafts the rows it would take.
What your suite would not have noticed. qikly --score-suite --tasks X
breaks your converged code one place at a time, re-runs the suite against each
break, and lists what went unnoticed. Nothing of yours is modified. Read the
score beside the reachability warning printed above it: a suite cannot catch a
fault in behaviour no row exercises.
Using qikly? Show it
If qikly writes the tests for something you maintain, add the badge to its README. It tells readers the suite was written from the acceptance criteria by an agent kept apart from the code:
[](https://test.qikly.com/?ref=badge)
Contributing a task
Users are encouraged to contribute their own tasks. The most useful is a new
example task from a domain the thirteen bundled ones do not cover, under a name that
follows the naming rules so it never clashes with another. CONTRIBUTING.md
has what a task needs and how to check it before sending it. Every accepted
task is credited in the changelog, and its author gets a contributor badge.
Start with a
task proposal,
so two people do not write the same one.
Further reading
Two reference pages, for looking things up rather than reading through: quick start on your own data and configuration and provider.
The design write-up is in three parts, and each stands on its own.
| What is in it | |
|---|---|
| 1. The case | Why an agent that writes its own tests is grading its own homework, and one CALC_TAX repair followed end to end: what the coding agent was given, the test it failed, the reasoning it produced from the failure alone, and the one-line patch. Start here. |
| 2. How well it works | Three sweeps and 967 runs, the benchmark defect found and corrected between them, the unit-stage gap, what makes a run stall, and the results this project measured and then withdrew. |
| 3. How it is built | What separates this from the alternatives, the five agents and what each may read, the FIX and PATCH separation, the thirteen example tasks, watching a run live, supplying your own code or tests, and the tools for generating and evaluating acceptance criteria. |
Where this came from
The separation this tool enforces is ordinary practice in safety-critical engineering, where verification is required to be independent of implementation as part of a V&V (Verification & Validation) methodology for testing. I worked in that setting on General Motors' autonomous vehicle program before building this toolset.
Built by Gal Arav.
Privacy
qikly runs on your machine and collects nothing. Your specification and code go
only to the model provider you configured, with your own key; the single other
network call is a version check against two public indexes, which
QIKLY_NO_VERSION_CHECK=1 turns off. PRIVACY.md.
License
Apache License 2.0, see LICENSE.
Related MCP servers

Galaxy Nebula MCP Server
MCP server exposing Galaxy UI components — manifests, source code, and framework coverage

MCP server for Galaxy bioinformatics platform—connect, execute tools, and manage workflows

Shared fleet memory for AI agents: nightly self-correction, recall every prompt (supported agents).

On-demand local Apple Mail, Calendar, and Reminders MCP server for macOS.
Local MCP access to approved 1Password fields without exposing plaintext secrets to AI agents.
