NeuroStack MCP Server
io.github.raphasouthall/neurostack
Token-efficient MCP memory for Markdown vaults with tiered search, GraphRAG, and AI-powered memory synthesis.
What is the NeuroStack MCP server?
NeuroStack is a local retrieval layer and optimizer for Markdown knowledge bases that indexes `.md` files into SQLite with full-text search, embeddings, and wiki-link graph analysis. It exposes 33 MCP tools for searching notes, walking connections, and saving memories, while an optimizer loop flags stale notes, harvests decisions from AI sessions, and promotes recurring memories into learnings. All indexing is read-only by default; your files stay untouched unless you opt into git-backed write tools.
NeuroStack turns your Markdown vault (Obsidian, Logseq, Notion exports, or plain files) into a searchable knowledge base that AI agents can query across sessions. It combines keyword and semantic search with graph analysis to surface ranked evidence, detects stale or superseded notes, and automatically harvests and synthesizes learnings from your AI conversations. Works with Claude, Cursor, Windsurf, Gemini CLI, and any MCP client—no model runs during search, so retrieval is instant.
How to install NeuroStack
Copy-paste configuration for popular MCP clients.
NEUROSTACK_VAULT_ROOTPath to your Markdown vault (e.g. ~/brain, ~/notes)
Tools & capabilities
Tools this server exposes to the agent.
vault_search— Hybrid keyword and semantic search across notes with tiered depth (triples, summaries, or full notes) and optional reranking.vault_context— Assemble context from memories, triples, summaries, and sessions within a token budget.vault_graph— Walk the wiki-link graph, analyze communities, detect bridges and gaps between topics.vault_remember— Save a memory (observation, decision, convention, learning, bug, or context) with optional TTL and workspace scope.vault_write_file— Create or edit a note in the vault; commits and pushes to git (opt-in, requires git repo).vault_delete_file— Delete a note from the vault; commits and pushes to git (opt-in, requires git repo).vault_read_file— Read a note by path (opt-in write tool).vault_list_files— List notes in the vault (opt-in write tool).memories_search— Search live memories by content, type, or workspace.memories_add— Add a memory directly via CLI or API.memories_forget— Archive a memory so it no longer appears in search.memories_edit— Update a memory's text or metadata.memories_merge— Combine similar memories into one learning.sessions_search— Search raw AI session transcripts indexed in sessions.db.vault_brief— Get a brief summary of a note or topic.vault_stale— List notes flagged as stale or superseded.vault_coverage— Check which notes cover a given topic or query.vault_promote— Promote a memory to a new note in the vault (opt-in, requires git repo).
Use cases
- Ask your AI about connections across hundreds of research papers or course notes without re-pasting context each session.
- Keep AI-assisted fiction writing consistent: your AI remembers character histories, world-building decisions, and chapter continuity across sessions.
- Flag deprecated APIs, retracted findings, or reversed architecture decisions before your AI cites them as current.
- Build a searchable client or project context that persists across conversations, so your AI remembers decisions and meeting notes without manual re-entry.
- Automatically harvest and synthesize learnings from your AI sessions into a growing knowledge base of decisions, conventions, and insights.
NeuroStack MCP server FAQ
NeuroStack is a local MCP server that indexes your Markdown notes into a searchable database with full-text and semantic search, wiki-link graph analysis, and memory synthesis. It lets AI agents query your knowledge base across sessions and automatically harvests learnings from conversations.
Yes. NeuroStack is open-source (Apache 2.0) and runs entirely on your machine. Lite mode (~130 MB) requires no GPU or external services. Full mode (~560 MB) optionally uses local Ollama for embeddings and summaries, or you can configure external OpenAI-compatible APIs.
Install via npm (`npm install -g neurostack`), run `neurostack init` to set up your vault, then use `neurostack setup-desktop` for Claude Desktop or `neurostack setup-client cursor` for Cursor. For Claude Code, run `claude mcp add neurostack -- neurostack serve`.
No. By default, NeuroStack is read-only: it indexes your files into its own SQLite database and never touches your Markdown. You can opt into write tools (`vault_write_file`, `vault_delete_file`) that commit changes to git, so every edit is visible in `git log` and revertable.
NeuroStack works with any MCP client: Claude Desktop, Claude Code, Cursor, Windsurf, Gemini CLI, VS Code, and Codex. It also exposes an OpenAI-compatible API for custom integrations.
No. If you take notes in Markdown or can export from Obsidian, Notion, Bear, or Roam, the `neurostack init` wizard handles setup. It works for researchers, writers, students, professionals, and engineers.
README (reference)
Source of truth, from the repository.


A local retrieval layer and optimizer for the Markdown knowledge base you already have.
NeuroStack indexes a folder of .md files (Obsidian, Logseq, Notion exports, plain Markdown) into one SQLite database with full-text search, embeddings and a wiki-link graph. Any MCP client can then search it, walk the graph and save memories. A query returns ranked evidence with note paths, and your AI does the reasoning, so no model runs while you wait. Between queries NeuroStack keeps the knowledge base accurate. It flags notes that have gone stale, harvests decisions and root causes from your AI sessions, merges recurring memories into learnings, and queues the proven ones to become notes. Indexing never changes your files, and optional MCP write tools let a client edit notes through your git history.
Works with Claude, Cursor, Windsurf, Gemini CLI, VS Code, Codex and any other client that supports MCP.
60-second start
npm install -g neurostack          # install
neurostack init                    # pick your notes folder, press Enter for the rest
/save                              # in omp or Claude Code, keep what this session learned
neurostack doctor                  # check that everything works
The steps below explain each part and how to connect other AI clients.
Your notes, in your control
By default, NeuroStack is a read-only indexing layer:
- Indexing, search, summaries, and graph analysis never modify your Markdown files
- All index data lives in NeuroStack's own separate database
- To remove it completely, run
neurostack uninstall. Your notes stay untouched. - Nothing ever leaves your machine, unless you configure a third-party LLM provider for summaries and embeddings
If your vault is a git repo, four opt-in MCP write tools let an AI client author and edit notes for you: vault_write_file, vault_delete_file, plus vault_read_file / vault_list_files. Every write commits and pushes to your git remote with a descriptive message, so every change is visible in git log, revertable with git revert, and serialised under a per-vault lock. Writes hard-reject invalid frontmatter, paths outside the vault, and hidden directories (.git, .obsidian, …). Because the tools are exposed to any client talking to neurostack serve, gate them at the transport (auth, tunnel, LAN only) if you put the MCP endpoint on the public internet.
Who this is for
You do not need to be a developer. If you take notes in Markdown, or can export your notes as Markdown from Obsidian, Notion, Bear, or Roam, NeuroStack works for you.
| If you are... | NeuroStack helps you... |
|---|---|
| A researcher | Ask your AI "what do my notes say about X?" across hundreds of papers. Get warned when a note references a retracted finding or superseded paper before your AI cites it confidently. |
| A fiction writer | Your AI knows your world-building bible, character histories, and chapter decisions. It remembers that you agreed in session 4 that Elena's backstory changes in act 2. |
| A student | Ask your AI to explain connections across all your course notes. When a syllabus topic changes, stale revision notes are flagged automatically. |
| A professional | Your AI remembers client context, project decisions, and meeting notes session-to-session. No more re-pasting the same background every time. |
| A developer or DevOps engineer | Notes that reference deprecated APIs or reversed architecture decisions get flagged before your AI cites them as current. |
Get started in three steps
You will need Node.js installed (most computers already have it). The npm package handles the Python setup for you.
Step 1. Install
npm install -g neurostack
Step 2. Set up (takes about two minutes)
neurostack init
The setup wizard asks which vault folder to index, which mode to run (Lite or Full), and which profession pack to apply. Then it finishes the install for you. It adds the NeuroStack hook to omp or Claude Code if you have them, so /save keeps what a session learned. It sets up the AI that turns saved sessions into memories, using the same model as your summaries. If no model answers yet, it leaves that off and tells you so. It also installs one background timer that keeps the index tidy, and a failed background job shows up as a desktop notification. Press Enter at each question to take the default. At the end it runs neurostack doctor and shows what to try first.
Step 3. Connect to your AI
For Claude Desktop:
neurostack setup-desktop
For Claude Code:
claude mcp add neurostack -- neurostack serve
For Cursor, Windsurf, Gemini CLI, or VS Code:
neurostack setup-client cursor # or: windsurf, gemini, vscode
Done. Open a new conversation and ask your AI about something from your notes.
<details> <summary><strong>Lite and Full modes</strong></summary>Everything runs on your machine. Choose a tier during neurostack init:
- Lite (~130 MB) gives you keyword search, link-based connections between notes, stale detection and the MCP server. No GPU or Ollama required.
- Full (~560 MB) adds semantic search by meaning, AI-generated summaries, connections between notes, and topic clustering via local Ollama. GPU or 6+ core CPU recommended.
Non-interactive setup takes every default:
neurostack init --mode lite ~/my-notes --yes    # lite mode
neurostack init --mode full ~/my-notes --yes    # full mode
--no-hooks, --no-schedule and --checkpoint none turn off the hook, the timer and the checkpoint AI.
# PyPI
pipx install neurostack
pip install neurostack        # inside a venv
uv tool install neurostack

# One-line script
curl -fsSL https://raw.githubusercontent.com/raphasouthall/neurostack/main/install.sh | bash

# Lite mode (no ML deps)
curl -fsSL https://raw.githubusercontent.com/raphasouthall/neurostack/main/install.sh | NEUROSTACK_MODE=lite bash
On Ubuntu 23.04+, Debian 12+, and Fedora 38+, bare pip install outside a virtual environment is blocked by the operating system. Use npm, pipx, or uv tool install instead.
To uninstall: neurostack uninstall
What it does
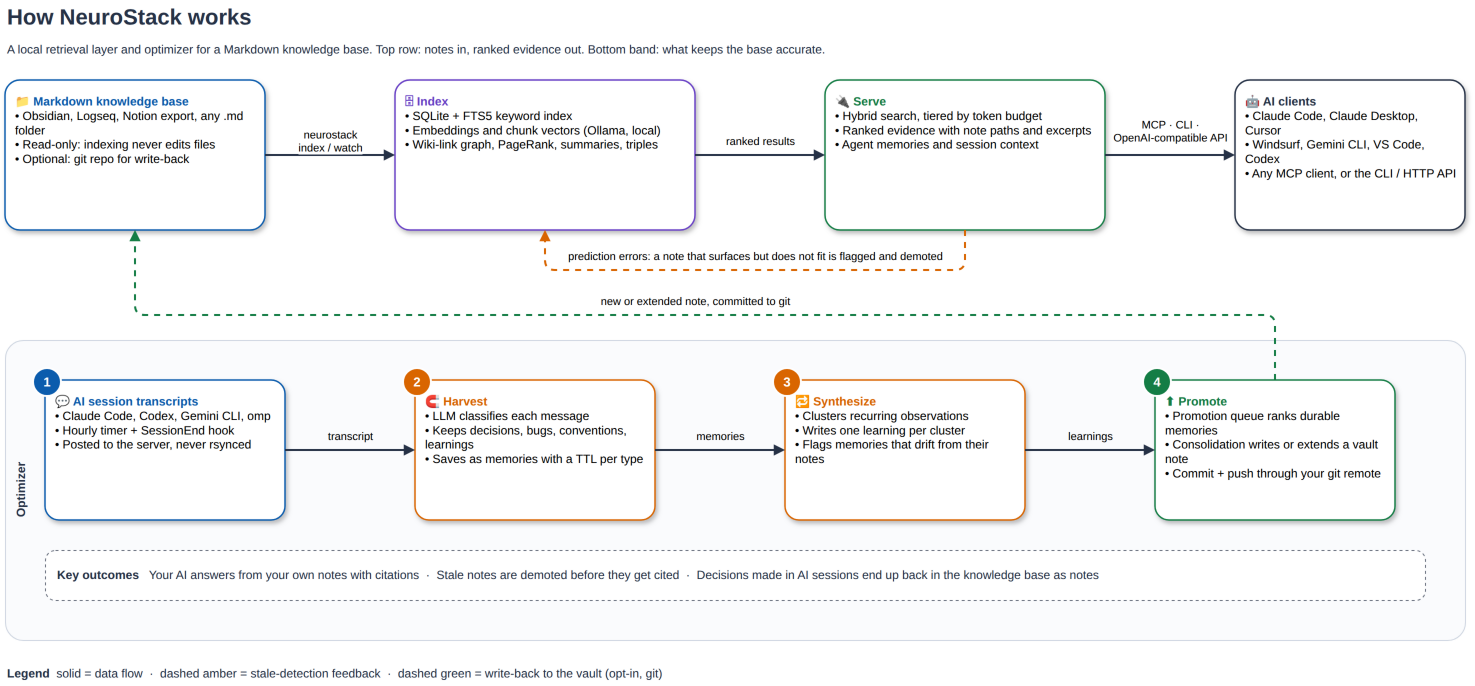
- Hybrid search (FTS5 keyword + semantic) with tiered depth, so a client can fetch triples, summaries or full notes by token budget.
- Ranked evidence with note paths and excerpts over the CLI, MCP, or an OpenAI-compatible API, for your AI to cite and reason over.
- Stale detection. A note that keeps surfacing in contexts where it no longer fits is flagged and demoted in later results.
- Session harvest. A timer scans Claude Code, Codex, Gemini and omp transcripts and saves decisions, bugs, conventions and learnings as memories with TTLs.
- Synthesis and promotion. Recurring memories become learnings; a promotion queue lists which ones are ready to become notes.
- Wiki-link graph with PageRank, community detection, gap and bridge analysis.
- Read-only by default. Opt-in write tools commit and push every change to your git remote.
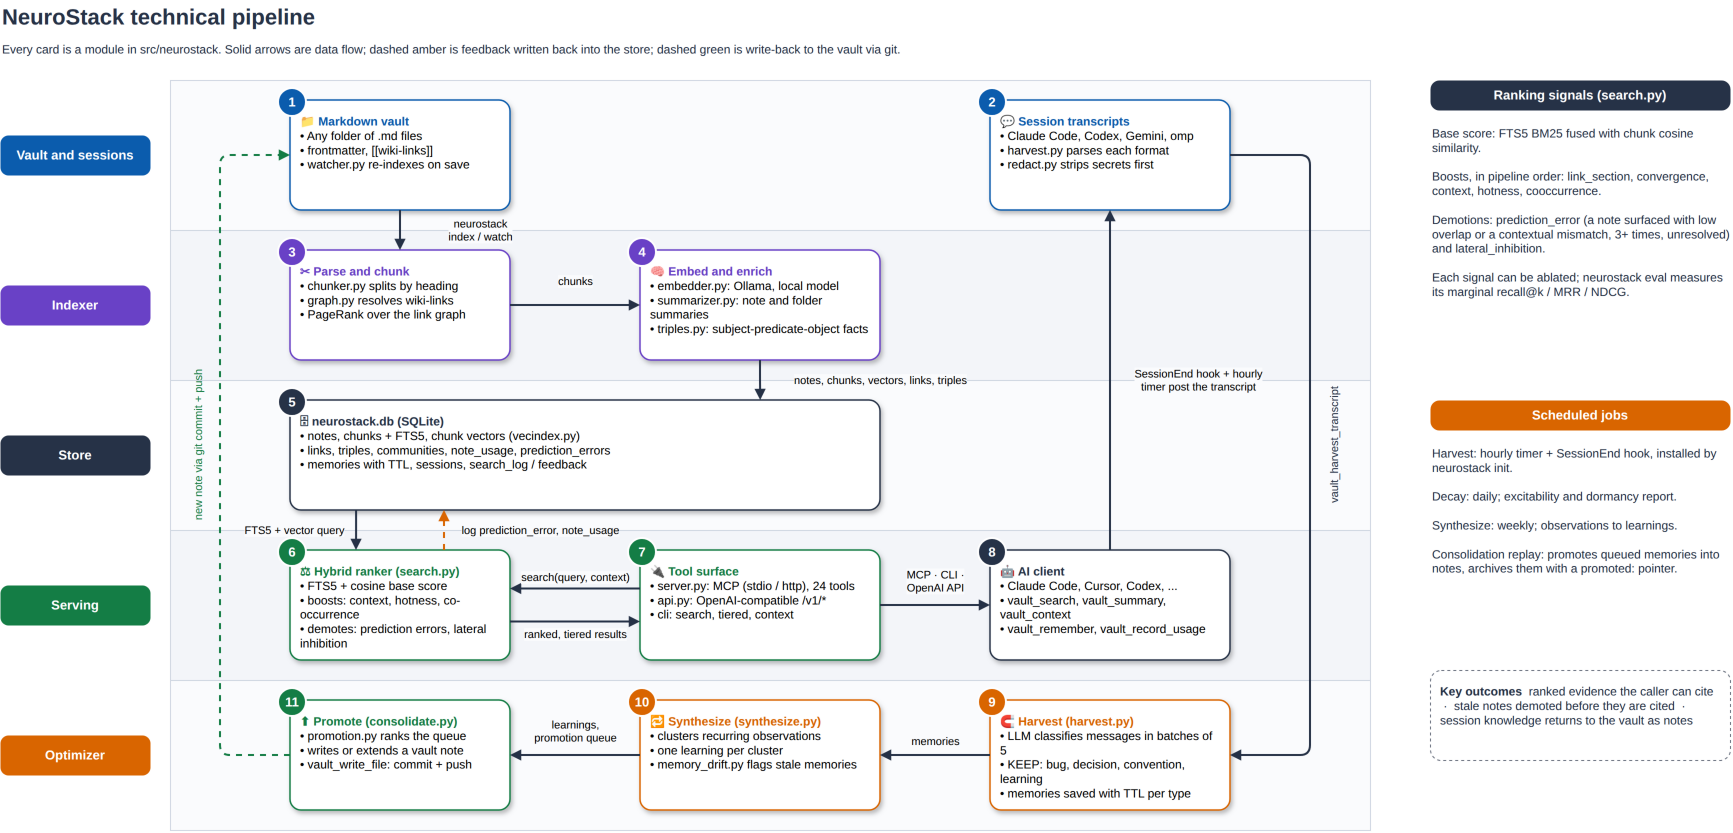
Editable sources live in the .drawio files next to the images.
Design
Philosophy
- Your files stay yours. The index lives in its own database, so deleting it leaves your notes exactly as they were.
- NeuroStack returns evidence and your AI reasons over it. No tool answers questions, and
tests/test_no_answering.pykeeps it that way. - Removing a memory moves it to an archive that search cannot reach, and you can restore it later.
- NeuroStack redacts secrets from text a model wrote, such as harvested summaries. It stores what you or your agent saved on purpose word for word.
- Ranking changes get measured first.
neurostack evalswitches off usage learning while it runs, so one pass cannot skew the next.
Mental model
NeuroStack holds two layers and one loop.
The vault is your Markdown. NeuroStack reads it, splits it into chunks, embeds them, summarises each note, extracts facts as triples and builds the link graph. Note status and tags live in NeuroStack's own note_metadata table, so it never needs to edit your frontmatter.
The memory layer holds what agents learn, typed as observations, decisions, conventions, learnings, bugs or context. These rows belong to NeuroStack and carry an optional workspace and an optional expiry.
The optimizer loop runs on a timer and connects the two. A memory usually starts in an AI session, becomes a learning when it keeps recurring, and becomes a note once no existing note covers it.
Architecture
flowchart LR
    V[/"Markdown vault<br/>never modified"/] --> IX["index<br/>chunk, embed, summarise,<br/>triples, link graph"]
    IX --> DB[("neurostack.db<br/>SQLite + FTS5")]
    S[/"AI session transcripts"/] --> H["harvest"]
    A["MCP client or CLI"] -->|vault_remember| DB
    H --> DB
    DB --> R["search, tiered, context,<br/>graph, brief"]
    R --> A
    DB --> J["timer jobs<br/>synthesize, promotion,<br/>decay, communities"]
    J --> DB
    J -->|opt-in, git commit| V
    DB --> UI["neurostack ui<br/>read-only dashboard"]
One OS timer runs neurostack run-due every minute, and that command runs each due job in turn. neurostack serve exposes 33 MCP tools over stdio or HTTP, and neurostack api serves the same retrieval as an OpenAI-compatible API.
Data model
| Area | Tables | Purpose |
|---|---|---|
| Vault index | notes, chunks + chunks_fts, summaries, triples + triples_fts, graph_edges, note_metadata | Searchable copy of your notes. Deleting a note cascades to its chunks, summaries and triples. |
| Topics | communities, community_members, folder_summaries | Topic clusters and folder summaries for broad questions. |
| Memories | memories + memories_fts, memories_archive, memory_sessions | Live memories and their embeddings. The archive has no full-text index and no embedding, so search cannot reach it. |
| Quality signals | prediction_errors, trigger_log, memory_coverage, note_usage | Stale notes, memories that drifted from the notes they cite, ignored reminders, cached coverage verdicts, and usage for hotness. |
| Feedback and jobs | search_log, search_feedback, job_runs, job_queue | Implicit search feedback (opt-in), job history, and queued checkpoint work. |
A memory row stores its content, tags, type, workspace, source agent, embedding and expiry. It also records embed_pending when the embedder was down, so neurostack backfill can embed it later, plus revision_count and merged_from for edits and merges. A second database, sessions.db, indexes raw session transcripts for neurostack sessions search.
Write mechanics
- Deliberate saves.
vault_rememberandneurostack memories addstore the text as written, embed it once, then report any near-duplicate above 0.85 similarity without refusing the save. If embedding fails, the row still saves and gets flagged for backfill. - Harvest. The index LLM reads each session message and keeps decisions, root causes, rules and facts. A second pass reads the session as a whole and saves up to 3 final conclusions tagged
session-verdict. The judge model then picks each memory's type. Harvest redacts secrets, skips anything above 0.88 similarity to a live memory, and records how many messages of each session it has read. - Synthesis. Observations at least 7 days old that cluster at 0.75 similarity or higher (one anchor plus 3 or more others) become one learning. The originals stay, tagged
superseded_by:<id>. - Removal. Forget, the losing side of a merge, expiry and prune all go through one helper that copies the row into
memories_archivewith a reason and a timestamp, then deletes it from the live table. Search checks expiry before it runs, so an expired memory never shows up. - Vault writes. Only the opt-in tools (
vault_write_file,vault_delete_file) and the promotion job touch the vault, and each one commits and pushes to git.
Read mechanics
- Hybrid search. NeuroStack runs keyword search and embedding search separately, takes the top 50 chunks from each, and merges the two lists by reciprocal rank (k = 60). A chunk found by only one search still competes. It then adds a convergence bonus, a 1.4× boost for the caller's context, usage hotness and co-occurrence, and demotes notes flagged as stale.
- Diversity. Results keep one chunk per note, and similar notes suppress each other, so one long note cannot fill the result list.
- Tiered depth. A client asks for triples (about 15 tokens), summaries (about 75) or full notes (about 300), or lets
autoescalate only when the cheaper tier misses. - Context assembly.
vault_contextsplits its token budget into 40% memories, 20% triples, 30% summaries and 10% sessions, so no single source crowds out the rest. - Hard limits. Every search returns at most
top_kresults. No retrieval path calls an LLM unless you passrerank=True(see below).
Optional reranking. vault_search(rerank=True) asks the judge model to score each whole-note result against your query and returns the judge's order. On 76 real search clicks it raised MRR from 0.503 to 0.652, top-1 hits from 34% to 49% and top-3 hits from 57% to 75% (paired permutation p=0.004). Each search costs about $0.0004 and adds about 0.4 s. It works with depth="full" or reference_only=True and raises an error at the other depths. If the judge fails, you get the normal order back.
Usage makes a note easier to find again. It never marks a note as true.
Known limits
- Harvested memories do not record their workspace yet, so a workspace-scoped search misses them.
- A harvested memory does not link back to the session and message it came from.
- A forgotten memory can come back if a later session says the same thing, because the duplicate check reads only live memories.
- Editing a memory replaces its text, and only
revision_countshows that it changed.
External services
Lite mode needs none of these. Everything below is opt-in and set in ~/.config/neurostack/config.toml, and each one has a matching NEUROSTACK_* env var. When a service is missing, the feature that needs it switches off and the rest keeps working.
| Service | Config keys | Default | What uses it | Without it |
|---|---|---|---|---|
Embedder, any OpenAI-compatible /v1/embeddings | embed_url, embed_model, embed_api_key, embed_timeout_s | Local Ollama, nomic-embed-text | Semantic search, memory similarity, duplicate checks, synthesis clusters | Keyword search only. New memories get flagged for neurostack backfill. |
| Index LLM, Ollama or any OpenAI-compatible chat API | index_llm_url, index_llm_model, index_llm_api_key, or index_llm_command for a CLI such as claude -p | Local Ollama, phi3.5 | Note summaries, triples, topic labels, harvest extraction, synthesis | No summaries or triples. Harvest cannot extract memories. |
| Judge model, OpenRouter decisions API | judge_url, judge_model, judge_api_key | ~typesafe/jev-latest on OpenRouter, fails without a key | Harvest memory types, rerank=True, the promotion queue's "uncovered" check | Harvest keeps the index LLM's type, rerank returns the normal order, and uncovered memories are counted as pending. |
Agent, Pi (@earendil-works/pi-coding-agent) on OpenRouter or a compatible proxy | agent_provider, agent_model, agent_api_key, agent_base_url | anthropic/claude-sonnet-5, needs Node 22.19+ | neurostack agent promotion, which writes notes from the promotion queue, and neurostack agent vault-save, which writes one session transcript into the notes | The promotion job shows as blocked. The queue still builds. |
| Checkpoint command, any shell command that answers a prompt on stdin | checkpoint_command | Off | Server workers that turn queued /save checkpoints and harvest jobs into memories | Queued checkpoints wait. Local harvest still runs. |
| Notify command, any shell command | notify_command | Off | Receives a failed job run as JSON, for example ntfy publish mytopic | Failures show only in neurostack jobs and the dashboard. |
| Git remote on your vault | Your vault's git config | None | vault_write_file, vault_delete_file and promotion commit and push each change | A write rolls back when the push fails. Reading never needs git. |
Only the embedder and the index LLM see your note text. The judge sees queries, memories and the notes being ranked or checked. Point every URL at localhost to keep all data on your machine.
What makes it different
NeuroStack is not a replacement for Obsidian, Notion, or any note-taking app. It sits on top of what you already use and adds what they don't have.
| Capability | Note apps | Basic RAG | NeuroStack |
|---|---|---|---|
| Stores your notes | Yes | No | No (read-only by default; opt-in git-backed write tools) |
| AI can search your notes | Some | Yes | Yes |
| Detects stale/outdated notes | No | No | Yes |
| AI memories persist across sessions | No | No | Yes |
| Works with any MCP-compatible AI | No | Varies | Yes |
| Tiered retrieval (saves 80-95% tokens) | No | No | Yes |
| Profession-specific workflows | No | No | Yes |
| Open source, self-hostable | Varies | Varies | Yes (Apache 2.0) |
Stale detection is the part other tools lack. When a note keeps appearing in contexts where it no longer fits, such as a deprecated API or a superseded paper, NeuroStack flags it and demotes it in later results.
Profession packs
When you run neurostack init, you choose a profession pack. Each one configures NeuroStack with templates, folder structures, and AI guidance suited to how your profession actually uses notes.
| Pack | Built for |
|---|---|
researcher | Literature review, citation tracking, evolving arguments, stale paper detection |
writer | Character sheets, world-building, chapter outlines, continuity tracking |
student | Course notes, spaced repetition, exam prep, syllabus change detection |
developer | Code decisions, architecture notes, runbooks, deprecated API detection |
devops | Infrastructure runbooks, incident notes, change logs |
data-scientist | Experiment tracking, model notes, dataset documentation |
Apply a pack to an existing vault without losing any notes:
neurostack scaffold researcher ~/my-notes # or: writer, student, developer, devops, data-scientist
You can also import an existing Markdown directory:
neurostack onboard ~/my-notes
How retrieval works
Most memory tools give your AI a wall of text and let it figure out what's relevant. NeuroStack is tiered. It starts with the cheapest retrieval that answers the question and escalates only when it needs to.
| Level | Tokens | What your AI gets |
|---|---|---|
| Quick facts | ~15 | Structured facts extracted from your notes: experiment-3 used learning-rate 0.001 |
| Summaries | ~75 | AI-generated overview of a note |
| Full content | ~300 | Actual Markdown content |
| Auto (default) | Varies | Starts at quick facts, escalates only if the answer isn't there |
Simple factual questions resolve at ~15 tokens. Deep dives get full context. Your AI spends its attention budget where it matters.
Your AI remembers decisions
Across sessions, your AI can save and retrieve typed memories: observations, decisions, conventions, learnings, bugs. When you start a new session, those memories are surfaced automatically.
"We decided to keep authentication stateless." "The thesis framing shifted from consolidation to complementary learning systems." "Elena's surname changed from Vasquez to Reyes in the chapter 7 revision."
These aren't just notes. They're things your AI remembers you decided together. They survive /clear. They survive closing the terminal. They survive switching machines.
neurostack memories add "revised thesis framing to CLS, not just consolidation" --type decision --tags "thesis,neuroscience"
neurostack memories search "thesis direction"
Learns from your AI sessions
NeuroStack scans your past AI conversations on a timer, extracts the decisions, observations and learnings, and saves them as memories. You do not have to write them down yourself.
neurostack harvest --sessions 5          # extract insights from last 5 sessions
neurostack schedule install              # one timer runs due jobs every minute
Supports Claude Code, VS Code, Codex CLI, Aider, and Gemini CLI session formats.
Keeps itself current
Your vault changes. NeuroStack watches it.
neurostack watch # auto-index on vault changes
The index updates as you write and stale detection runs continuously, so you do not maintain it by hand.
Scheduling
NeuroStack runs its background jobs from one OS timer. The timer calls neurostack run-due once a minute, and run-due works out which jobs are due and runs them one at a time. neurostack init installs the timer for you. Installing it records each daily job as just run, so the jobs start at their next scheduled time instead of all at once. The commands below manage it by hand.
neurostack schedule install   # install or overwrite the timer
neurostack schedule status    # show whether the timer is active
neurostack schedule remove    # remove the timer
schedule install uses the scheduler your OS already ships:
| OS | Backend | What it writes |
|---|---|---|
| Linux | systemd user timer | ~/.config/systemd/user/neurostack.timer and neurostack.service |
| macOS | launchd agent | ~/Library/LaunchAgents/io.neurostack.run-due.plist |
| Windows | Task Scheduler | a task named NeuroStackRunDue |
The timer calls the neurostack executable it finds on your PATH at install time, so run schedule install again after you move or reinstall NeuroStack. All three subcommands accept --json.
A systemd user timer runs only while you have a login session. On a headless Linux server, or when you run NeuroStack as root, enable lingering for that user so the timer keeps running after you log out:
sudo loginctl enable-linger <user>
neurostack doctor shows when each job last ran.
Checkpoints with a laptop and a server
/save on the laptop uploads the session transcript to the server's queue. The server's checkpoint-worker job turns it into memories within a minute, and harvest-worker does the same for transcripts harvest-scan uploads every 30 minutes. Each host reads its own file.
On the laptop, ~/.config/neurostack/client.toml names the server. Its checkpoint_command turns on harvest-scan and serves any hook checkpoint --run you start by hand:
url = "http://my-server:8001/mcp"
checkpoint_command = "claude -p --model haiku"
On the server, ~/.config/neurostack/config.toml holds the command the workers pipe each checkpoint prompt through. Any command that reads the prompt on stdin and prints the model's reply works, so it can call an OpenAI-compatible endpoint or a local proxy:
checkpoint_command = '''jq -Rs '{model: "qwen/qwen3-30b-a3b", messages: [{role: "user", content: .}]}' \
  | curl -s https://openrouter.ai/api/v1/chat/completions \
      -H "Authorization: Bearer $OPENROUTER_API_KEY" -H "Content-Type: application/json" -d @- \
  | jq -r '.choices[0].message.content' '''
checkpoint_timeout_s = 300     # per checkpoint
checkpoint_max_messages = 40   # largest window one checkpoint summarizes, 0 for no cap
NEUROSTACK_CHECKPOINT_COMMAND, NEUROSTACK_CHECKPOINT_TIMEOUT_S and NEUROSTACK_CHECKPOINT_MAX_MESSAGES override them. With no checkpoint_command in config.toml, neurostack jobs shows both workers off and says why.
Dashboard
neurostack ui serves a read-only dashboard at http://127.0.0.1:8765. It shows six pages. Overview has index coverage, communities, recent notes and memory counts. Automations lists every scheduled job with its last run, next run and 14-run history, and you can click a job to see its runs. Graph draws the top notes by PageRank, and clicking a node opens its summary and links. Memories lists memories with type tabs and search. Search runs note and memory searches with every option the vault_search and vault_memories tools take: mode, depth, result count, workspace, context boost, max tokens, judge rerank and reference-only for notes, and type, workspace and count for memories. A search there embeds the query, so it needs the embedder, and it does not count as note usage. Each note result has a Best result button that stores the search and the note as a label. Tuning runs weight tuning on those labels and on the ones the feedback loop inferred: it tunes on half, scores the other half, and Apply makes the winning weights the ones every search uses, only when they rank the unseen half better. Revert goes back to config.toml. Applying and marking are the dashboard's only writes.
It needs no extra install and makes no model calls. Pass --port to change the port and --open to open a browser. On any address other than localhost, create a login first with neurostack ui user add NAME, which prompts for a password of at least 8 characters (--password-stdin reads it from a pipe). The page then shows a sign-in form, and a session lasts 30 days. neurostack ui user list shows the users and neurostack ui user remove NAME deletes one and ends their sessions.
What changes day-to-day
| Without NeuroStack | With NeuroStack |
|---|---|
| AI answers from training data | AI answers from your actual notes |
| Cites the runbook you deprecated | Flags it as stale, demotes it automatically |
| No memory of yesterday's session | session_brief reconstructs working context |
| Reading 10 notes to find one fact | Tiered retrieval: ~15 tokens for a structured fact |
Decisions lost after /clear | Typed memories persist indefinitely |
How your vault is stored
~/your-vault/                           # your Markdown files (not modified by indexing; AI clients can edit via opt-in MCP write tools)
~/.config/neurostack/config.toml        # configuration
~/.local/share/neurostack/
    neurostack.db                       # SQLite + FTS5 knowledge graph
    sessions.db                         # session transcript index
NeuroStack reads your vault. By default it writes nothing back, and all index data lives in its own SQLite databases. The opt-in MCP write tools (vault_write_file / vault_delete_file) are the one exception: they create or edit .md files in the vault and commit + push the change to your git remote on the spot.
Memory write-back (opt-in)
Memories live in SQLite by default, so they're invisible in Obsidian and vanish if the database is lost. Turn on write-back to persist qualifying memories as markdown files you own:
[writeback]
enabled = true                 # opt-in; default false
path = ".neurostack"           # quarantine dir, relative to vault_root
include_observations = false   # also write the noisier observation/context types
- Files land under
{vault_root}/.neurostack/memories/<type>/<YYYY-MM>/<uuid>.md. NeuroStack only ever writes inside that one directory, so your own notes stay untouched. - Only persistent (no-TTL)
decision/convention/learning/bugmemories are written; ephemeral (TTL) memories never are. - The database stays the source of truth; files are readable exports.
vault_remember/vault_update_memory/vault_forget/vault_mergekeep the files in step automatically. - The directory self-ignores via its own
.gitignoreso memories stay out of git until you opt in (delete that file to version them). NeuroStack never commits on your behalf. neurostack migrate write-back [--dry-run]exports existing memories;neurostack syncreconciles files against the DB (the DB wins on conflict).
<details> <summary><strong>All 24 MCP tools</strong></summary>
Search & retrieval
| Tool | Description |
|---|---|
vault_search | Hybrid search with tiered depth (triples, summaries, full, auto) |
vault_summary | Pre-computed note summary |
vault_graph | Wiki-link neighborhood with PageRank scores |
vault_related | Semantically similar notes by embedding distance |
vault_triples | Knowledge graph facts (subject-predicate-object) |
vault_communities | GraphRAG queries across topic clusters |
vault_context | Task-scoped context assembly within token budget |
Context & insights
| Tool | Description |
|---|---|
session_brief | Compact session briefing |
vault_stats | Index health, excitability breakdown, memory stats |
vault_record_usage | Track note hotness |
vault_prediction_errors | Surface stale notes |
Memories
| Tool | Description |
|---|---|
vault_remember | Store a memory (returns duplicate warnings + tag suggestions) |
vault_update_memory | Update a memory in place |
vault_merge | Merge two memories (unions tags, audit trail) |
vault_forget | Delete a memory |
vault_memories | List or search memories |
vault_harvest | Extract insights from session transcripts |
vault_harvest_transcript | Extract insights from a transcript posted by the client (no server filesystem access) |
Sessions
| Tool | Description |
|---|---|
vault_session_start | Begin a memory session |
vault_session_end | End session, storing a summary you write, plus auto-harvest |
Vault files (opt-in write surface — git-backed)
| Tool | Description |
|---|---|
vault_read_file | Read a .md file under your vault root |
vault_list_files | List .md files; hidden segments (.git, .obsidian, …) always excluded |
vault_write_file | Create or overwrite a .md file; commits + pushes origin/main. Hard-rejects writes without required frontmatter (date, tags, type). On push conflict: git pull --rebase --autostash + retry once, then rollback. |
vault_delete_file | Delete a .md file; commits + pushes origin/main |
# Setup
neurostack init                          # one-command setup: deps, vault, index
neurostack init --mode full ~/brain      # non-interactive full mode
neurostack onboard ~/my-notes            # import existing Markdown notes
neurostack scaffold researcher           # apply a profession pack
neurostack scaffold --list               # see all packs
neurostack update                        # pull latest source + re-sync deps
neurostack uninstall                     # complete removal

# Search & retrieval
neurostack search "query"                # hybrid search
neurostack tiered "query"                # tiered: triples -> summaries -> full
neurostack triples "query"               # knowledge graph triples
neurostack summary "note.md"             # AI-generated note summary
neurostack related "note.md"             # semantically similar notes
neurostack graph "note.md"               # wiki-link neighborhood
neurostack communities query "topic"     # GraphRAG across topic clusters
neurostack context "task" --budget 2000  # task-scoped context recovery
neurostack brief                         # session briefing

# Maintenance
neurostack index                         # build/rebuild knowledge graph
neurostack watch                         # auto-index on vault changes
neurostack decay                         # excitability report
neurostack prediction-errors             # stale note detection
neurostack backfill [summaries|triples|all]
neurostack communities build             # rebuild topic clusters
neurostack reembed-chunks                # re-embed all chunks
neurostack export --include triples -o dump.json  # dump index data as JSON

# Memories
neurostack memories add "text" --type observation
neurostack memories search "query"
neurostack memories list
neurostack memories update <id> --content "revised"
neurostack memories merge <target> <source>
neurostack memories forget <id>
neurostack memories prune --expired

# Sessions
neurostack harvest --sessions 5          # extract session insights
neurostack sessions search "query"       # search transcripts

# Scheduled jobs: one OS timer (systemd, launchd, or Task Scheduler) runs `neurostack run-due`
neurostack schedule install              # install or overwrite the timer
neurostack schedule status               # is the timer active?
neurostack schedule remove
neurostack run-due                       # what the timer calls: run each due job once
neurostack jobs                          # schedule, last run, and next due per job

# Harness hooks (session brief, auto-RAG, trigger memories, checkpoints)
neurostack hooks install --harness claude   # or: omp
neurostack hooks status

# Trigger memories: did the warnings change anything?
neurostack triggers stats                # fired, followed, ignored per memory (30d)
neurostack triggers stats --days 7

# Checkpoint: manual only — a harness never fires one on its own (issue #176).
# `/save` (both harnesses) queues a request instead of running one directly:
neurostack hook enqueue --harness claude    # or: omp — uploads the transcript to the server's queue
neurostack hook checkpoint --run --session <id>  # run one checkpoint by hand on this host
neurostack hook checkpoint --save               # a model's JSON reply on stdin
# Client setup
neurostack setup-client cursor           # or: windsurf, gemini, vscode, claude-code
neurostack setup-client --list
neurostack setup-desktop                 # Claude Desktop

# Diagnostics
neurostack stats                         # index health
neurostack doctor                        # validate all subsystems
neurostack demo                          # interactive demo with sample vault
Checkpoint runners use a nonblocking OS lock per conversation. Overlapping saves for one
conversation return checkpoint already running, while separate conversations can save at
the same time. The runner keeps the extracted reply and a receipt for each acknowledged
item, so a partial retry does not call the model again or repeat confirmed saves. Each
conversation retains the 256 most recent SHA-256 receipts of exact redacted content. Changed
facts produce different receipts. A connection can still fail after the server commits but
before it acknowledges the write. Avoiding that remote duplicate requires server-side
idempotency, which the current vault_remember contract does not provide.
No harness fires a checkpoint on its own: /save is the only trigger, and it hands the
request to the server's queue instead of running one directly. neurostack hook enqueue --harness <claude|omp> reads the session's transcript and uploads it with the queue_add
MCP tool, gzip-compressed. A transcript over 10 MB goes up as its newest records only. The
queue takes 50 checkpoints a day, and the server's checkpoint-worker job in
neurostack run-due runs each one within a minute against the uploaded text. enqueue
prints one line back (queued, already queued, the daily cap reached, or unreachable) and
exits 0 on a landed request, 1 otherwise. The server runs it with the checkpoint_command
from its own config.toml. harvest --pending --enqueue and the client's harvest-scan job
upload pending transcripts to the harvest queue the same way.
Each feature models a specific mechanism from memory neuroscience:
| Feature | Mechanism | Citation |
|---|---|---|
| Stale detection + demotion | Prediction error signals trigger reconsolidation | Sinclair & Bhatt 2022 |
| Excitability decay | CREB-elevated neurons preferentially join new memories | Han et al. 2007 |
| Co-occurrence learning | Hebbian "fire together, wire together" plasticity | Hebb 1949 |
| Topic clusters | Hopfield attractor basin dynamics, inverse temperature | Ramsauer et al. 2020 |
| Convergence confidence | Energy landscape retrieval, basin width = robustness | Krotov & Hopfield 2016 |
| Lateral inhibition | PV+/SOM+ interneuron winner-take-all competition | Rashid et al. 2016 |
| Tiered retrieval | Complementary learning systems | McClelland et al. 1995 |
Full citations: docs/neuroscience-appendix.md
</details>FAQ
Does it modify my vault files? Not by default. Indexing, search, summaries, and every read tool leave your files untouched, and all index data lives in NeuroStack's own SQLite databases. Four opt-in MCP write tools (vault_write_file, vault_delete_file, plus vault_read_file / vault_list_files) let an AI client author and edit notes; every write commits and pushes to your git remote, so changes are tracked and revertable. If your vault is not a git repo, the file is still written to disk but the commit step is skipped. Separately, opt-in memory write-back persists memories as markdown, but only inside the quarantined .neurostack/ directory, away from your own notes.
Do I need a GPU? No. Lite mode has zero ML dependencies. Full mode runs on CPU but summarization is slow without a GPU.
Do I need to know Python? No. The npm package handles everything. You never touch a virtualenv.
How large a vault can it handle? Tested with ~5,000 notes. FTS5 search stays fast at any size.
Can I use it without an AI client? Yes. The CLI works standalone and pipes into any LLM.
Is my vault private? Yes. Nothing leaves your machine, unless you point Full mode at a third-party LLM provider instead of local Ollama. In that case the text you index goes to that provider under its own policy.
What AI clients does it work with? Claude Code, Claude Desktop, Cursor, Windsurf, Gemini CLI, VS Code, Codex and any other client that supports MCP.
Requirements
- Linux, macOS, or Windows
- Lite mode: Node.js + Python 3.11+. No GPU or Ollama required.
- Full mode: Ollama with
nomic-embed-textand a summary model. GPU or 6+ core CPU recommended.
Get started
npm install -g neurostack
neurostack init
neurostack init picks a tier, installs dependencies, indexes the vault and configures your MCP client.
- Contributing: CONTRIBUTING.md
- GitHub: github.com/raphasouthall/neurostack
- Sponsor: GitHub Sponsors | Buy me a coffee
Apache-2.0, see LICENSE. No GPL dependencies.
Related MCP servers

AI-powered search for Korea's 2022 secondary curriculum: 3,838 achievement standards, learning topics, and progression pathways.
한국 특성화고 전문교과 2022 개정 교육과정 학습 그래프 MCP 서버 (528과목·성취기준 47,625건, 공식 원문 전량 수록)

Sourced market and compliance research for Claude Desktop, Claude Code and Cursor.

Cognitive memory for AI coding assistants — persistent memory across sessions

io.github.rarasAI/raras
Disease Twin — Brazil's rare-disease knowledge graph (10,468) over MCP. Source-grounded, PT-BR.

Cardora loyalty program analytics for business owners. Customer joins, stamps, rewards, and trends.
View repository →