Web Researcher MCP MCP Server
io.github.zoharbabin/web-researcher-mcp
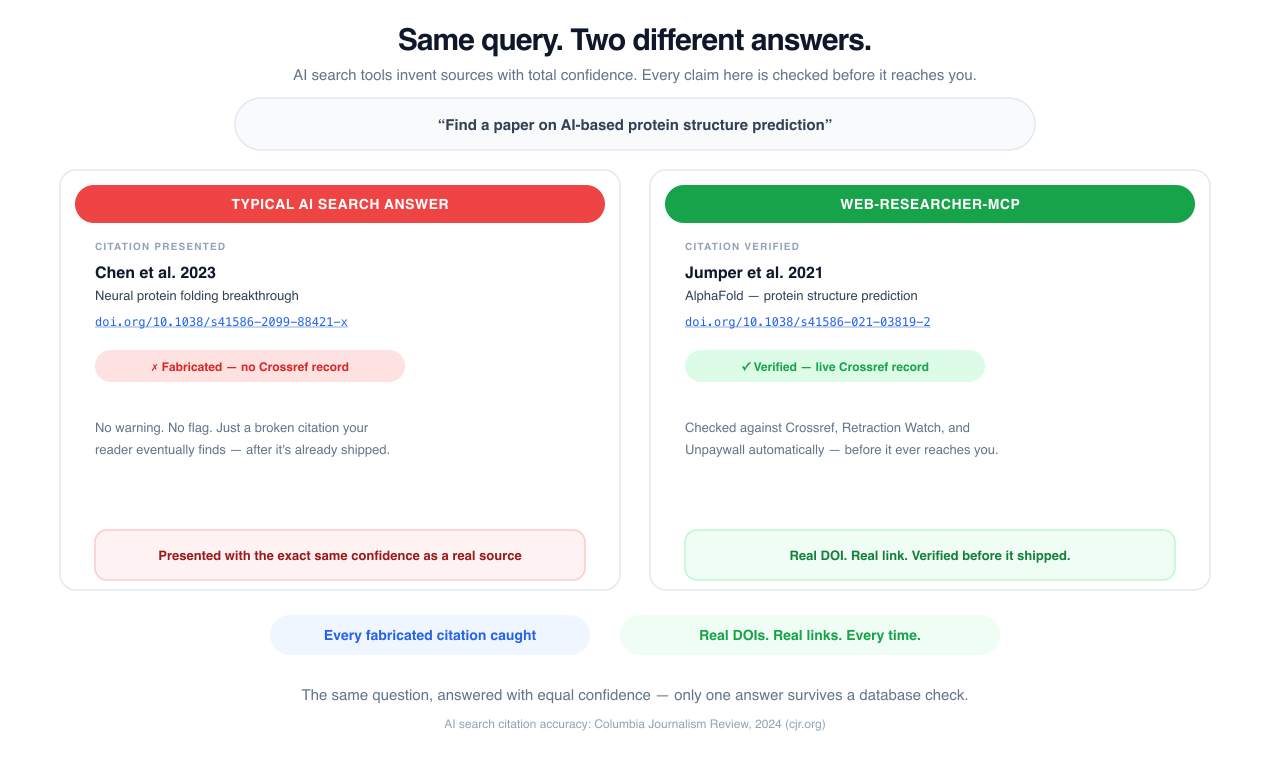
AI research assistant that cites real sources—search trusted sites, read full articles, verify citations, never hallucinate.
What is the Web Researcher MCP MCP server?
Web Researcher MCP is an MCP server that gives AI assistants like Claude and Cursor the ability to search the web, read full articles, verify citations, and conduct multi-step research while ensuring all sources are real and verifiable. It lets you restrict searches to trusted sources (academic journals, court databases, news outlets) and prevents the citation hallucinations common in other AI search tools.
Web Researcher MCP solves the problem of AI-generated fake citations by letting you control exactly which sources your AI searches. Instead of hoping a search engine's results are accurate, you define 'search lenses'—curated lists of trusted sites for your field. It reads full articles (not just snippets), verifies citations before you rely on them, and works inside Claude, Cursor, and other MCP clients. Your research stays private, runs on your machine, and produces citations you can actually defend.
How to install Web Researcher MCP
Copy-paste configuration for popular MCP clients.
GOOGLE_CUSTOM_SEARCH_API_KEYsecretGoogle Custom Search API key
GOOGLE_CUSTOM_SEARCH_IDGoogle Programmable Search Engine ID
SEARCH_PROVIDERSearch provider: google, brave, serper, searxng, searchapi, duckduckgo, tavily, exa, hackernews, reddit, bluesky, github, or xquik
SEARCH_ROUTINGUse multiple search engines with automatic switching if one goes down (e.g. brave,google,serper)
BRAVE_API_KEYsecretBrave Search API key
SERPER_API_KEYsecretSerper.dev API key
SEARCHAPI_API_KEYsecretSearchAPI.io API key
SEARXNG_URLSearXNG instance URL
TAVILY_API_KEYsecretTavily Search API key
EXA_API_KEYsecretExa API key (neural/semantic web search provider)
XQUIK_API_KEYsecretXquik API key (metered X/Twitter post search provider)
EDGAR_CONTACT_EMAILContact email for SEC EDGAR (enables filing_search); falls back to OPENALEX_EMAIL
COURTLISTENER_API_TOKENsecretCourtListener API token (legal_search works without it; a token raises the rate limit)
FRED_API_KEYsecretFRED API key (enables econ_search for Federal Reserve economic data)
Tools & capabilities
Tools this server exposes to the agent.
web_search— Search the web, optionally restricted to trusted sources via search lensesscrape_page— Read any URL in full—web pages, PDFs, Word docs, slideshows, YouTube transcripts, Hacker News threadssearch_and_scrape— Search and read the best results with quality scoring to surface reliable sourcesimage_search— Find images by size, type, color, or formatnews_search— Search recent news with date controls and source filteringacademic_search— Find real papers with real DOIs, authors, citation counts, and open-access linkspaper_fulltext— Fetch a paper's full text from its DOI, Semantic Scholar ID, or URLcitation_graph— Walk a paper's citation neighborhood—works it cites and works that cite itpatent_search— Search patent offices (US, Europe, international) with classification codesfiling_search— Search SEC EDGAR for US public-company filings or pull structured XBRL company factslegal_search— Search US court opinions and dockets via CourtListenerecon_search— Look up economic data from World Bank, OECD, Eurostat, and FREDclinical_search— Search ClinicalTrials.gov for clinical-trial registrations and resultsmonarch_search— Query the Monarch Initiative biomedical knowledge graph for diseases, genes, and phenotypesawesome_list_search— Search community-curated 'awesome-*' lists on GitHub topicslocal_search— Search for physical places (restaurants, shops, services, points of interest)brand_research— Research a company's brand identity—colors, logos, typography, tone of voice, social handlescompany_recon— OSINT company reconnaissance—Certificate Transparency logs, Wayback Machine, subdomains, web-search summaryverify_citation— Check if a citation exists, matches a real record, is retracted, or is a dead linkaudit_bibliography— Audit a whole reference list for retracted, dead-link, and unverifiable citations
Use cases
- Conduct literature reviews with real DOIs and verifiable citations for academic papers
- Audit AI-generated research and catch fabricated citations before submitting to clients or courts
- Search SEC filings, court records, and patent databases for legal and business research
- Verify medical and clinical information by searching peer-reviewed journals and clinical trials
- Build research reports with full-text article access and formatted bibliographies ready for publication
Web Researcher MCP MCP server FAQ
Web Researcher MCP is an open-source MCP server that integrates web research into Claude, Cursor, and other AI assistants. It searches the web, reads full articles, verifies citations, and lets you restrict searches to only trusted sources—preventing the citation hallucinations common in other AI search tools.
Yes, Web Researcher MCP is free and open source (MIT license). Basic web search via DuckDuckGo requires no API key. Image search, news search, and richer providers (academic papers, patents, SEC filings, court records) require free or low-cost API keys (2 minutes to set up).
Easiest: use the one-click install buttons in the README (Cursor, VS Code, LM Studio), or run `uvx web-researcher-mcp` (requires `uv`). For Claude Desktop, download the `.mcpb` bundle and double-click it, or use the `uvx` command. macOS users can also use Homebrew: `brew install zoharbabin/tap/web-researcher-mcp`.
No authentication required for basic web search (DuckDuckGo). Academic search, patents, SEC filings, court records, and economic data work with free or low-cost API keys (FRED, Brave, BrandFetch optional). Your research stays private—it runs on your machine, not through a third-party server.
Yes. It verifies citations against real databases (Crossref for papers, SEC EDGAR for filings, CourtListener for cases), checks for retractions, and audits entire bibliographies. It reads full articles instead of relying on snippets, so it catches when search results misrepresent a source.
Web pages, academic papers (with real DOIs), patents (US, Europe, international), SEC filings, US court opinions, clinical trials, economic data, news, images, and more. You can restrict searches to curated 'search lenses'—trusted sites for your field (PubMed, arXiv, SEC.gov, etc.)—or search the entire web.
README (reference)
Source of truth, from the repository.
⭐ If you're tired of AI making things up, and web-researcher-mcp helps you, give us a star ⭐ — it helps more teams discover the project.
<video src="https://github.com/user-attachments/assets/cbf46fe1-f629-4540-b2bf-1282c69729a3" width="352" height="720"></video>
<p align="center"> <a href="https://github.com/zoharbabin/web-researcher-mcp/actions/workflows/ci.yml"><img src="https://github.com/zoharbabin/web-researcher-mcp/actions/workflows/ci.yml/badge.svg" height="20" alt="CI"></a> <a href="https://goreportcard.com/report/github.com/zoharbabin/web-researcher-mcp"><img src="https://goreportcard.com/badge/github.com/zoharbabin/web-researcher-mcp" height="20" alt="Go Report Card"></a> <a href="https://scorecard.dev/viewer/?uri=github.com/zoharbabin/web-researcher-mcp"><img src="https://api.scorecard.dev/projects/github.com/zoharbabin/web-researcher-mcp/badge" height="20" alt="OpenSSF Scorecard"></a> <a href="https://pkg.go.dev/github.com/zoharbabin/web-researcher-mcp"><img src="https://pkg.go.dev/badge/github.com/zoharbabin/web-researcher-mcp.svg" height="20" alt="Go Reference"></a> <a href="https://opensource.org/licenses/MIT"><img src="https://img.shields.io/badge/License-MIT-yellow.svg" height="20" alt="License: MIT"></a> <a href="https://github.com/zoharbabin/web-researcher-mcp/releases"><img src="https://img.shields.io/github/v/release/zoharbabin/web-researcher-mcp" height="20" alt="Release"></a> <a href="https://hub.docker.com/r/zoharbabin/web-researcher-mcp"><img src="https://img.shields.io/docker/pulls/zoharbabin/web-researcher-mcp?cacheSeconds=3600" height="20" alt="Docker"></a> <a href="https://pypi.org/project/web-researcher-mcp/"><img src="https://img.shields.io/pypi/v/web-researcher-mcp?label=PyPI" height="20" alt="PyPI"></a> <a href="https://glama.ai/mcp/servers/zoharbabin/web-researcher-mcp"><img src="https://glama.ai/mcp/servers/zoharbabin/web-researcher-mcp/badges/score.svg" height="20" alt="web-researcher-mcp MCP server"></a> <a href="https://github.com/zoharbabin/web-researcher-mcp/stargazers"><img src="https://img.shields.io/github/stars/zoharbabin/web-researcher-mcp?style=social" height="20" alt="GitHub Stars"></a> <a href="https://mcptoplist.com/server/io.github.zoharbabin%2Fweb-researcher-mcp"><img src="https://mcptoplist.com/badge/io.github.zoharbabin%2Fweb-researcher-mcp.svg" height="20" alt="MCP Toplist"></a> </p>Get started in 30 seconds
Python users — uvx (no compile, any OS):
# One-time: install uv (skip if you already have it)
curl -LsSf https://astral.sh/uv/install.sh | sh        # macOS/Linux  (Windows: winget install astral-sh.uv)

claude mcp add --scope user web-researcher -- uvx web-researcher-mcp
uv fetches the right prebuilt binary for your platform and runs it — no Go, no compile, no manual PATH. Point any MCP client at uvx web-researcher-mcp. Also works with uv tool install web-researcher-mcp or pip install web-researcher-mcp.
Python SDK
from web_researcher_mcp import WebResearcherClient

async with WebResearcherClient() as client:
    response = await client.web_search("CRISPR off-target effects 2024", num_results=5)
    for r in response.results:
        verified = await client.verify_citation(r.url)
        print(r.title, "—", "✓" if verified.exists else "?")
Full documentation: docs/PYTHON_CLIENT.md

Sync wrapper (for scripts and notebooks that don't use async):
with WebResearcherClient.sync() as client:
    response = client.web_search("climate change 2024")
    print(response.results[0].title)
macOS (Homebrew):
brew install zoharbabin/tap/web-researcher-mcp
claude mcp add --scope user web-researcher -- web-researcher-mcp
macOS / Linux (no package manager):
curl -fsSL https://raw.githubusercontent.com/zoharbabin/web-researcher-mcp/main/install.sh | sh
Windows (PowerShell):
powershell -ExecutionPolicy Bypass -c "irm https://raw.githubusercontent.com/zoharbabin/web-researcher-mcp/main/install.ps1 | iex"
No dev tools needed — every method ships the same signed binary (the PyPI wheels vendor it; the others download it and verify its checksum) and puts it on your PATH. The curl/PowerShell installers also register it with Claude Code automatically when the claude CLI is present; Homebrew installs the binary, so run the claude mcp add line above to connect it.
One-click install:
<p> <a href="https://cursor.com/en/install-mcp?name=web-researcher&config=eyJjb21tYW5kIjoidXZ4IiwiYXJncyI6WyJ3ZWItcmVzZWFyY2hlci1tY3AiXX0%3D"><img src="https://cursor.com/deeplink/mcp-install-dark.svg" alt="Add to Cursor" height="28"></a> <a href="https://vscode.dev/redirect?url=vscode%3Amcp%2Finstall%3F%257B%2522name%2522%253A%2522web-researcher%2522%252C%2522command%2522%253A%2522uvx%2522%252C%2522args%2522%253A%255B%2522web-researcher-mcp%2522%255D%257D"><img src="https://img.shields.io/badge/VS_Code-Install_Server-0098FF?style=flat-square" alt="Install in VS Code" height="28"></a> <a href="https://lmstudio.ai/install-mcp?name=web-researcher&config=eyJjb21tYW5kIjoidXZ4IiwiYXJncyI6WyJ3ZWItcmVzZWFyY2hlci1tY3AiXX0%3D"><img src="https://img.shields.io/badge/LM_Studio-Add_MCP-4A2DB8?style=flat-square" alt="Add to LM Studio" height="28"></a> </p>The Cursor / VS Code / LM Studio buttons install the zero-config uvx setup (your editor prompts to confirm before adding it; needs uv — see above). It runs DuckDuckGo web search with no API key — great to try instantly; image_search/news_search and richer providers need a key (2 min, see Configuration). Claude Desktop: download the .mcpb bundle for your platform and double-click it (Settings → Extensions), or use the uvx line above.
Using a different MCP client or want to pass API keys? See Connect to Your AI Assistant for the per-app config, and Configuration to pick a search provider.
Your AI can now search the web, read full articles, find academic papers, look up patents, and run multi-step research — only from sources you pick.
Why does this exist?
Perplexity gets its citations wrong over a third of the time. It links to papers that don't exist, invents DOIs, and presents SEO spam with the same confidence as peer-reviewed research. ChatGPT's web search isn't much better — it can't tell a blog post from a court filing.
If your work gets cited, published, submitted to a court, or shown to a client — you can't afford "probably real" sources.
This tool fixes the root cause: instead of searching the entire web and hoping, you tell your AI exactly which sources to search. We call these "search lenses" — curated lists of trusted sites for each field.
| What you get | What that means for you |
|---|---|
| Search lenses — choose your sources by field | Your AI only sees the sites you trust (PubMed, SEC.gov, arXiv — not random blogs) |
| Research tools for every source type | Papers, patents, SEC filings, US court records, economic data, news, web pages, images, full-text reading, grounded answers with citations, structured extraction, and multi-step deep research |
| Always has a backup | Multiple search engines working together — if one has issues, the others pick up automatically |
| Reads full articles | Doesn't just give you snippets — extracts and reads entire pages, PDFs, Word docs, even YouTube transcripts and Hacker News threads |
| Real citations, formatted | Every source comes with a proper APA/MLA citation and a link that actually works |
| Your queries stay private | Runs on your machine — nobody sees what you're researching. Not us, not anyone. |
| Paper trail | Every search is logged so you can reproduce your research process months later |
Works with Claude, Claude Desktop, Cursor, and any AI assistant that supports tool use.
Who uses this
- Academic researchers — "I need a literature review with real DOIs, not made-up citations"
- Business analysts — "My deliverable needs sources a client can actually click and verify"
- Lawyers — "If I cite a case that doesn't exist, I get fined $50,000"
- Journalists — "I need to cross-check government records and court filings, not Perplexity summaries"
- Medical researchers — "Clinical decisions based on a health blog could hurt someone"
- Graduate students — "I spent 3 hours tracking down a citation my AI invented"
- Enterprise teams — "Our competitive research can't go through a third party's servers"
How It Compares
| web-researcher-mcp | Perplexity | Scite.ai | Elicit | |
|---|---|---|---|---|
| You pick which sources are searched | Yes (built-in + custom lenses) | No | No | No |
| Makes up citations | Never — every link is real | ~37% incorrect | Rare (journals only) | Rare |
| Works across all fields | Yes — legal, medical, news, patents, everything | Yes | Journals only | Papers only |
| Keeps your research private | Yes — runs on your machine | No (they see everything) | No | No |
| Works inside your existing AI (Claude, Cursor, etc.) | Yes | No (separate app) | Partially | No (separate app) |
| Can read full articles, not just snippets | Yes — pages, PDFs, Word docs, YouTube | No | No | Limited |
| Cost | Free forever (open source) | $20/mo | $20/mo | $10-49/mo |
When to use what
- Perplexity — Quick casual lookups where you don't need to cite your sources
- Scite.ai / Elicit — Browsing a specific database of academic papers
- web-researcher-mcp — Anything where your reputation is attached to the research: client work, court filings, publications, grant proposals, medical decisions, journalism
- Claude built-in search — Quick one-off lookups mid-conversation
What your AI can do with this
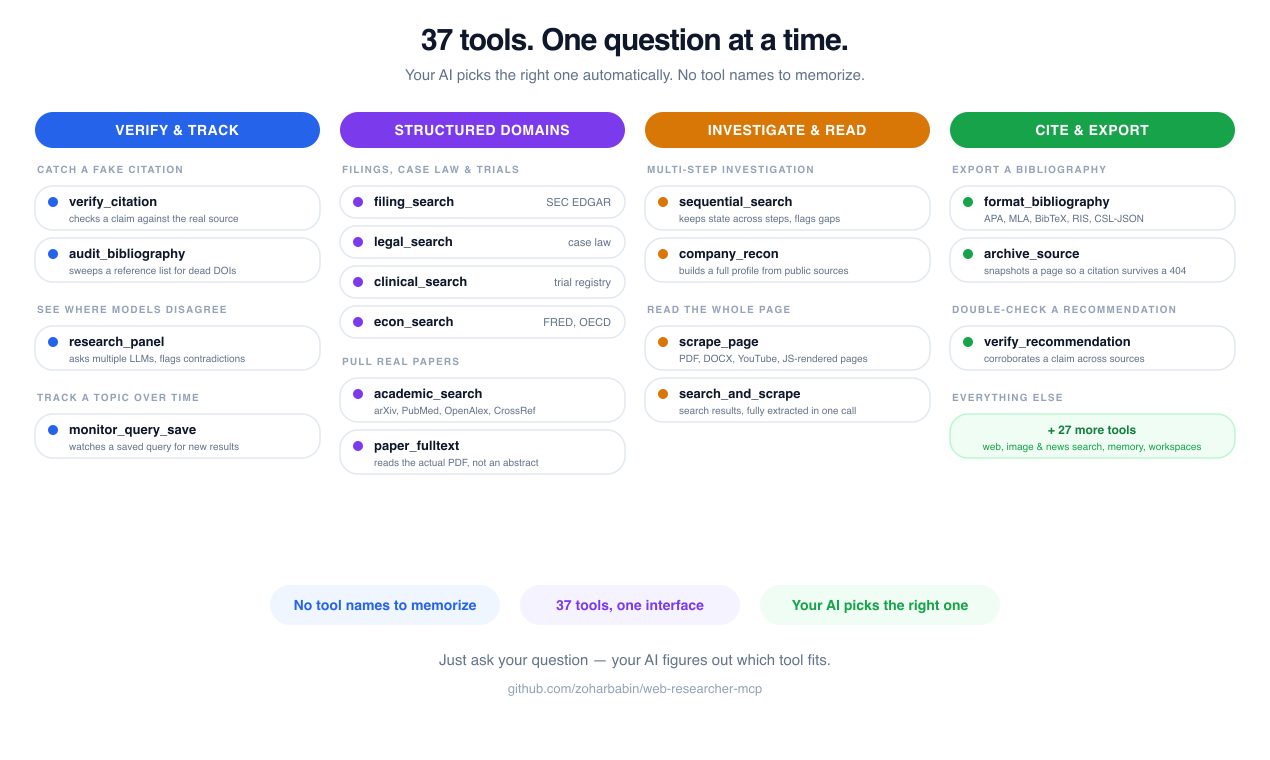
| Tool | What it does |
|---|---|
web_search | Search the web — optionally restricted to only the sources you trust via lenses |
scrape_page | Read any URL in full — web pages, PDFs, Word docs, slideshows, YouTube transcripts, Hacker News threads (read natively via the HN API); supports mode: raw for verbatim, unsanitized source (e.g. inspecting JSON or HTML) |
search_and_scrape | Search and then read the best results — with quality scoring to surface the most reliable sources |
image_search | Find images by size, type, color, or format |
news_search | Search recent news with date controls and source filtering |
academic_search | Find real papers with real DOIs — authors, citation counts, open-access links |
paper_fulltext | Fetch a paper's full text in one call from its DOI, Semantic Scholar ID, or URL — no need to chain academic_search then scrape_page |
citation_graph | Walk a paper's citation neighborhood — works it cites and works that cite it, with intent/influence signals |
patent_search | Search patent offices (US, Europe, international) with classification codes |
filing_search | Search SEC EDGAR for US public-company filings (10-K, 10-Q, 8-K, …) — or pull structured XBRL company facts |
legal_search | Search US court opinions and dockets via CourtListener — real cases with real citations |
econ_search | Look up economic data — World Bank global development indicators, OECD economic indicators, Eurostat European statistics (all keyless), and FRED US macro series (GDP, CPI, unemployment, rates; requires FRED_API_KEY) |
clinical_search | Search ClinicalTrials.gov — clinical-trial registrations with status, phase, sponsor, and whether results are posted (discovery, not medical advice) |
monarch_search | Query the Monarch Initiative biomedical knowledge graph — rank diseases and genes by phenotype similarity, look up disease/gene/phenotype entities, traverse gene-disease-phenotype associations |
awesome_list_search | Search the ecosyste.ms Awesome API for community-curated "awesome-*" lists on a GitHub topic — structured, filterable coverage (stars, curated-entry count, topics) beyond free-text search |
local_search | Search for physical places (restaurants, shops, services, points of interest) by local intent query — structured POI details and descriptions. Requires BRAVE_API_KEY |
brand_research | Research a company's complete brand identity — colors (hex), logos, typography, tone of voice, and social handles — from any domain or company name. Returns structured JSON for AI content generation. No API key required; BrandFetch key optional for richer data |
company_recon | OSINT company reconnaissance — Certificate Transparency log SANs, Wayback Machine historical URL inventory, derived subdomains, and a web-search company summary. Each phase fails soft and is independently selectable |
verify_citation | Check a citation before you rely on it — does it exist, match a real record, and is it retracted or a dead link? Evidence, not a verdict |
audit_bibliography | Audit a whole reference list in one pass — paste a CSL-JSON/RIS/BibTeX file (or a session) and get per-entry + corpus-level flags for retracted, dead-link, and unverifiable citations |
verify_recommendation | Audit an AI-generated recommendation list (listicle, product ranking) for self-promotion, author conflicts of interest, domain reputation, and dead links — catches GEO-gamed picks. Evidence, not a verdict |
archive_source | Capture a fresh Internet Archive (Wayback Machine) snapshot of a URL via Save Page Now so a cited source stays verifiable if the page later changes or disappears — returns snapshot URL + timestamp (write tool) |
sequential_search | Multi-step deep research — your AI remembers what it already found and builds on it |
get_research_session | Recover a research session after context loss — picks up right where you left off |
research_export | Export a research session as a shareable report (markdown or JSON), with full per-step provenance |
format_bibliography | Turn collected sources into a formatted bibliography — APA, MLA, BibTeX, RIS, or CSL-JSON (Zotero/EndNote/Mendeley-ready) |
research_panel | Ask the same question to a panel of independently configured LLMs and compare answers — consensus, contradictions, and model-unique points, computed deterministically, never smoothed over by an arbiter model |
Most tools above are always available. A few activate only when the right provider or config is present: citation_graph and research_panel require at least one configured backing provider; filing_search requires EDGAR_CONTACT_EMAIL; local_search requires BRAVE_API_KEY. Operators can also enable opt-in, consent-gated tools (per-user analytics, long-term memory, shared workspaces, saved-query monitoring) that appear only when their feature is turned on — see docs/TOOLS.md for the authoritative, CI-verified tool list and full schemas.
Ready-made research templates
The server also ships guided prompt templates your AI assistant can pull in with one click — they walk it through a proven, multi-step process so you don't have to spell out every instruction:
| Template | What it guides your AI to do |
|---|---|
comprehensive-research | Run a structured, multi-step deep dive on a topic |
fact-check | Verify a claim against multiple independent sources |
competitive-analysis | Size up a company and its market (news, patents, web) |
literature-review | Systematically review academic literature on a topic |
brand-guidelines | Research a brand and produce use-case-specific creative direction (landing page, email, video brief) — calls brand_research and interprets the structured JSON for you |
company-recon | Deep OSINT reconnaissance on a company — maps infrastructure, filings, personnel, and public footprint |
curriculum-research | Research a subject's syllabus coverage, institutional climate, and academic-freedom context — calls web_search with the curriculum lens |
In most AI apps these show up wherever you pick a prompt or "/" command. The server exposes live status resources (stats://tools, stats://sessions, stats://rate-limits, stats://providers), a lens catalog (lenses://catalog), diagnostics (diagnostics://errors/recent, diagnostics://health), and a large-payload artifact store (research://artifact/{id}) so you — or your AI — can check usage, limits, and which providers are active. See docs/DEPLOYMENT.md for the full list.
Quick Start
Option 1: Homebrew (macOS / Linux — recommended)
brew install zoharbabin/tap/web-researcher-mcp
claude mcp add --scope user web-researcher -- web-researcher-mcp
Homebrew handles trust, updates, and PATH for you — no signing warnings.
Option 2: One-command install (any OS — no dev tools needed)
macOS / Linux:
curl -fsSL https://raw.githubusercontent.com/zoharbabin/web-researcher-mcp/main/install.sh | sh
Windows (PowerShell):
powershell -ExecutionPolicy Bypass -c "irm https://raw.githubusercontent.com/zoharbabin/web-researcher-mcp/main/install.ps1 | iex"
Downloads the binary, verifies its SHA-256 checksum against the signed release, puts it on your PATH, and registers it with Claude Code if installed. Customize the install location:
INSTALL_DIR=/opt/tools curl -fsSL https://raw.githubusercontent.com/zoharbabin/web-researcher-mcp/main/install.sh | sh
AUR (Arch Linux):
# Using any AUR helper (yay, paru, etc.)
yay -S web-researcher-mcp
Or manually: git clone https://aur.archlinux.org/web-researcher-mcp.git && cd web-researcher-mcp && makepkg -si
Nix / NixOS:
# Run without installing
nix run github:zoharbabin/web-researcher-mcp

# Add to your flake inputs
nix profile install github:zoharbabin/web-researcher-mcp
See packaging/nix/flake.nix for NixOS module usage.
Continue.dev:
Add to your Continue ~/.continue/config.json:
{
  "mcpServers": {
    "web-researcher": {
      "command": "uvx",
      "args": ["web-researcher-mcp"]
    }
  }
}
Or copy packaging/continue/config.json as a starting point.
WinGet (Windows):
winget install zoharbabin.web-researcher-mcp
Scoop (Windows):
scoop bucket add zoharbabin https://github.com/zoharbabin/scoop-bucket
scoop install web-researcher-mcp
Chocolatey (Windows):
choco install web-researcher-mcp
Homebrew Cask (macOS — Developer ID-signed + notarized binary):
brew install --cask zoharbabin/tap/web-researcher-mcp
The cask ships the notarized darwin binary (Gatekeeper-clean). Most users want the formula above (brew install zoharbabin/tap/web-researcher-mcp), which the bare name resolves to; pass --cask explicitly for the notarized artifact.
Go install (if you have Go):
go install github.com/zoharbabin/web-researcher-mcp/cmd/web-researcher-mcp@latest
claude mcp add --scope user web-researcher -- web-researcher-mcp
Docker:
# STDIO mode needs -i so the container's stdin stays attached for MCP JSON-RPC
docker run -i --rm \
           -e GOOGLE_CUSTOM_SEARCH_API_KEY=YOUR_KEY \
           -e GOOGLE_CUSTOM_SEARCH_ID=YOUR_CX \
           docker.io/zoharbabin/web-researcher-mcp:latest
Build from source:
git clone https://github.com/zoharbabin/web-researcher-mcp.git
cd web-researcher-mcp
go build -o web-researcher-mcp ./cmd/web-researcher-mcp
Connect to Your AI Assistant
The install script registers with Claude Code automatically. For other apps, add to your AI's config file:
{
  "mcpServers": {
    "web-researcher": {
      "command": "web-researcher-mcp",
      "env": {
        "GOOGLE_CUSTOM_SEARCH_API_KEY": "YOUR_GOOGLE_API_KEY",
        "GOOGLE_CUSTOM_SEARCH_ID": "YOUR_SEARCH_ENGINE_ID"
      }
    }
  }
}
Any provider works — pick one and set its key. For example, Brave (no Google keys needed):
{
  "mcpServers": {
    "web-researcher": {
      "command": "web-researcher-mcp",
      "env": {
        "SEARCH_PROVIDER": "brave",
        "BRAVE_API_KEY": "YOUR_BRAVE_API_KEY"
      }
    }
  }
}
Swap in any provider from the Configuration table by setting SEARCH_PROVIDER and that provider's key. Done — your AI assistant now has access to all research tools.
Configuration
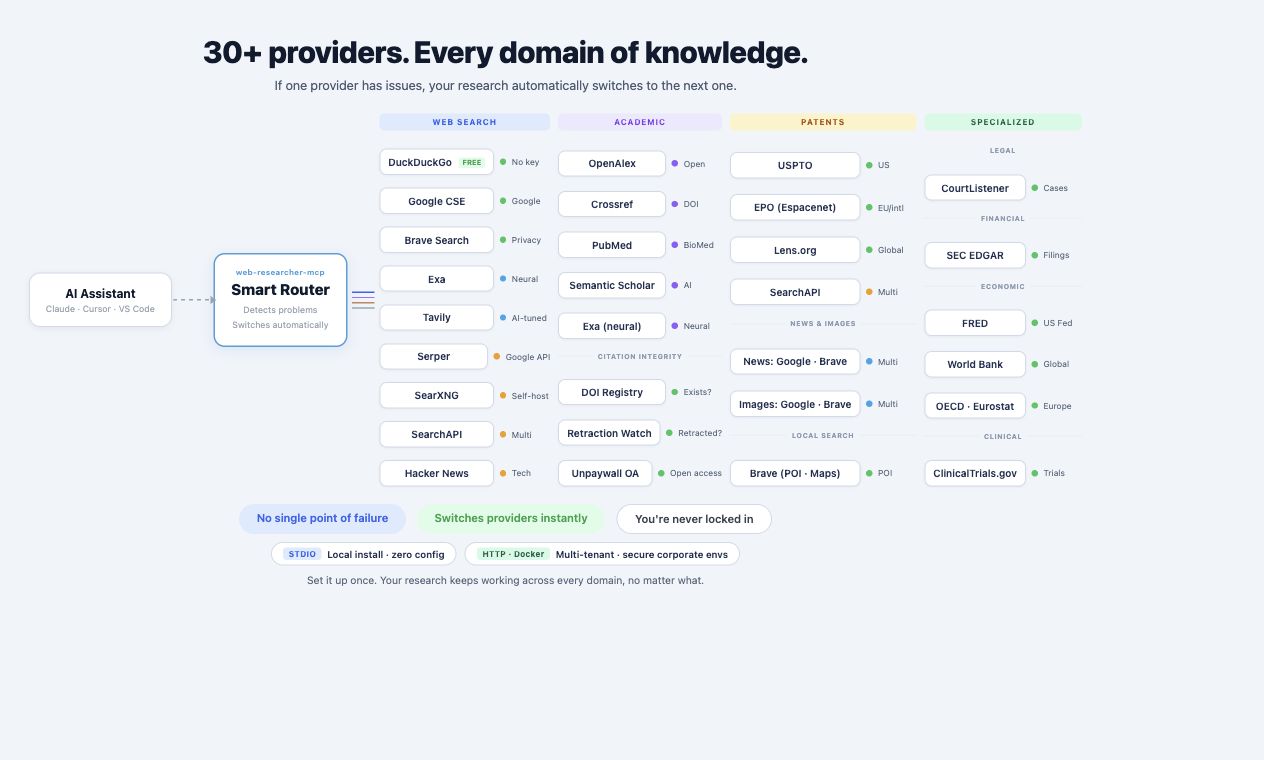
No API key required. DuckDuckGo is the built-in zero-config fallback — install and go. To raise result quality and unlock image/news search, add any one of the providers below. They're all optional and interchangeable — pick whichever you already use or prefer; the server treats them equally.
Search providers
Set SEARCH_PROVIDER=<name> and supply that provider's key. Every provider works with search lenses, and any of them can be combined for automatic failover (see Search Providers).
| Provider | SEARCH_PROVIDER | Key variable(s) | Get a key |
|---|---|---|---|
| DuckDuckGo | duckduckgo | none | Built in — zero config |
| Google PSE | google | GOOGLE_CUSTOM_SEARCH_API_KEY + GOOGLE_CUSTOM_SEARCH_ID | cloud console + engine |
| Brave | brave | BRAVE_API_KEY | brave.com/search/api |
| Serper | serper | SERPER_API_KEY | serper.dev |
| SearchAPI.io | searchapi | SEARCHAPI_API_KEY | searchapi.io |
| You.com | youcom | YOUDOTCOM_API_KEY | you.com/docs/api-reference/search/v1-search |
| SearXNG | searxng | SEARXNG_URL | self-hosted |
| Tavily | tavily | TAVILY_API_KEY | app.tavily.com |
| Exa | exa | EXA_API_KEY | dashboard.exa.ai |
| Hacker News | hackernews | none | Built in — zero config (HN Algolia index) |
reddit | none | Built in — zero config (public RSS) | |
| Bluesky | bluesky | none | Built in — zero config (public AT Protocol API) |
| GitHub | github | none (GITHUB_TOKEN optional, raises rate limit) | Built in — zero config (public REST Search API) |
| Xquik | xquik | XQUIK_API_KEY | dashboard.xquik.com |
Each provider has its own free tier, signup flow, and capability mix (images, news, freshness). See docs/PROVIDERS.md for a full comparison (index classification, capability matrix, quick-pick guide) and docs/API_SETUP.md for step-by-step key setup. Set up more than one and the server fails over automatically — see Search Providers.
When SEARCH_PROVIDER is unset, the server uses Google if its keys are present and otherwise falls back to the zero-config DuckDuckGo provider — so it always works out of the box, with or without keys.
Academic Search (Optional — no signup needed)
Academic search providers (OpenAlex, CrossRef) accept a contact email to unlock faster access via the polite pool — no registration, just an email. See docs/API_SETUP.md for setup and docs/DEPLOYMENT.md for the full variable reference.
With these set,
academic_searchreturns real papers with DOIs, authors, citation counts, and open-access PDF links. Without them, it still works but uses web search as a fallback.
Patent Search (Optional)
Patent providers (EPO, USPTO, The Lens) require API keys for structured patent data. See docs/API_SETUP.md for step-by-step setup and docs/DEPLOYMENT.md for the full variable reference.
<details> <summary><strong>Advanced: HTTP mode, OAuth, and all other settings</strong></summary>With these,
patent_searchreturns structured patent data with classification codes, dates, and inventors. Without them, it falls back to web search.
HTTP mode, OAuth, rate limiting, cache, scraping, and observability settings are documented in docs/DEPLOYMENT.md.
</details>Under the Hood
<details> <summary><strong>Architecture (for developers and contributors)</strong></summary>The full per-package map and the layered diagram (MCP transports → tool dispatch → service layer → infrastructure) live in ARCHITECTURE.md — kept in one place to avoid drift.
<details> <summary><strong>Design Principles (for developers)</strong></summary>- Zero global state -- all dependencies injected via constructors
- Interface-driven -- every external dependency behind an interface for testing and swapping
- Bounded concurrency -- explicit semaphores for external API calls
- Defense in depth -- SSRF protection, rate limiting, content sanitization at every layer
- Fail loud -- errors returned, never swallowed; validation at boundaries
Search Providers
You choose which search engine powers your research. All of them work with lenses.
| Provider | Whole-Web | Images | News | Notes |
|---|---|---|---|---|
| DuckDuckGo | Yes | — | — | Zero-config default (no API key needed); rate-limited for heavy use |
| Google PSE | Yes | Yes | Yes | Programmable Search Engine; free tier: 100 queries/day |
| Brave Search | Yes | Yes | Yes | Independent index; free tier available |
| Serper.dev | Yes | Yes | Yes | Google-identical results |
| SearXNG | Yes | Yes | Yes | Self-hosted, privacy-first, air-gapped deployments |
| SearchAPI.io | Yes | Yes | Yes | Unified API with multiple engine backends |
| Tavily | Yes | — | Yes | AI-agent search; clean, LLM-ready content |
| Exa | Yes | — | Yes | Neural/semantic search; also backs academic_search and the optional paid scrape tier |
| Hacker News | HN only | — | Yes | Zero-config (HN Algolia index); searches HN threads, not the full web |
| Reddit only | — | Yes | Zero-config (public RSS); searches Reddit posts, not the full web | |
| Bluesky | Bluesky only | — | — | Zero-config (public AT Protocol API); searches Bluesky posts, not the full web |
| GitHub | GitHub only | — | Yes | Zero-config (public REST Search API); searches issues/PRs, not the full web |
Multiple Providers (recommended)
Set up multiple search engines so if one has issues, your research doesn't stop:
export SEARCH_ROUTING=brave,google,serper
If Brave is down, it automatically tries Google. If Google is rate-limited, it falls through to Serper. Your research just works.
See docs/PROVIDERS.md for a full provider comparison (index classification, capabilities, free tiers) and docs/DEPLOYMENT.md for advanced routing options (per-topic routing, patent-specific providers, etc.).
Single Provider
If you only have one search API key, that works too — just set it up and go.
<details> <summary><strong>Provider Setup Examples</strong></summary>Multi-provider routing (recommended):
export SEARCH_ROUTING=brave,google,serper
export BRAVE_API_KEY=BSAxxxxxxxxxx
export GOOGLE_CUSTOM_SEARCH_API_KEY=AIza...
export GOOGLE_CUSTOM_SEARCH_ID=017...
export SERPER_API_KEY=...
Single provider — Brave Search:
export SEARCH_PROVIDER=brave
export BRAVE_API_KEY=BSAxxxxxxxxxx
Single provider — SearXNG (self-hosted, privacy-first):
export SEARCH_PROVIDER=searxng
export SEARXNG_URL=http://localhost:8080
Single provider — Exa:
export SEARCH_PROVIDER=exa
export EXA_API_KEY=...
Single provider — Google PSE:
export SEARCH_PROVIDER=google
export GOOGLE_CUSTOM_SEARCH_API_KEY=AIza...
export GOOGLE_CUSTOM_SEARCH_ID=017...
Any provider from the Configuration table works the same way — set SEARCH_PROVIDER and its key(s).
Search Lenses
Search lenses let you control which websites your AI is allowed to search. Instead of searching the entire web (and getting blogs, spam, and AI-generated junk), a lens restricts results to only the sources you trust for that topic.
Built-in Lenses
| Lens | Focus |
|---|---|
docs | Official documentation and API references only |
academic | Preprint servers, repositories, open-access journals |
academic-extended | Preprint servers, OA aggregators, and repositories beyond core journal indexes |
biomed | Rare-disease and biomedical knowledge-graph sources — ontology portals, gene-disease databases, curated rare-disease registries |
clinical | Clinical trials, drug safety, evidence-based medicine |
curriculum | Academic curriculum data, institutional free speech climate, and global education statistics |
security | CVEs, advisories, vulnerability research |
investigative_records | Public records, corporate filings, FOIA |
programming | Code docs, tutorials, Q&A |
programming-goggle | Developer-first results re-ranked by Brave's Programming Goggle — surfaces docs, repos, and authoritative technical content (requires Brave) |
devops | Infrastructure and operations — Kubernetes, Docker, Terraform, cloud, CI/CD |
news | Current events, journalism |
tech | Technology industry |
legal | Law, cases, statutes |
medical | Health, medicine |
finance | Markets, filings |
science | Research, papers |
government | Policy, regulations |
osint | Open-source intelligence — public records, corporate registries, social footprint, infrastructure |
awesome-lists | Community-curated "awesome-*" lists on GitHub — PR-reviewed tool and resource collections across every domain |
You can also create your own lenses for any field — just list the domains you trust.
How it works
When you (or your AI) use a lens, results come only from the sites in that lens. For example, using the medical lens means your AI searches PubMed, WHO, NIH, and other clinical sources — never health blogs or supplement ads.
Your AI uses lenses automatically when you ask it to. For example: "Search for recent findings on SGLT2 inhibitors using the clinical lens."
<details> <summary><strong>Creating Your Own Lens</strong></summary>Create a directory for your custom lenses and add a JSON file for each one:
{
  "name": "my-industry",
  "description": "Only searches sources I trust for my field",
  "domains": [
    "trusted-source.com",
    "industry-journal.org",
    "official-database.gov"
  ],
  "cx": "",
  "routing": ""
}
Then point the server to your lens directory:
export CUSTOM_LENSES_PATH=/path/to/my-lenses
Your AI will now have my-industry as an available lens. Custom lenses load after the built-in set — a custom lens with the same name as a built-in one overrides it. You can add up to ~10 domains per lens.
Advanced options (optional — most users can ignore these):
- cx — If you have a Google Programmable Search Engine with up to 5,000 domains, put the engine ID here
- routing — Force this lens to use a specific search provider (e.g.,
"google")
Privacy & Security
Your research queries go directly from your machine to the search provider you chose. They never pass through our servers (we don't have servers). The tool runs entirely on your computer.
<details> <summary><strong>Technical security details (for enterprise / compliance teams)</strong></summary>- SSRF protection — blocks internal network access, cloud metadata endpoints, DNS rebinding attacks
- OAuth 2.1 (HTTP mode) — JWKS token validation, per-tenant isolation, audience/issuer validation
- Rate limiting (HTTP mode) — per-tenant + global limits to protect upstream APIs
- Content sanitization — HTML cleaned via whitelist policy, deduplication, quality scoring
For the full threat model, see docs/SECURITY.md.
</details>Setup for Each AI App
Claude Code
Add to your MCP config (~/.claude.json). Set SEARCH_PROVIDER and the matching key for whichever provider you use (see the Configuration table) — this example uses Google:
{
  "mcpServers": {
    "web-researcher": {
      "command": "/path/to/web-researcher-mcp",
      "env": {
        "SEARCH_PROVIDER": "google",
        "GOOGLE_CUSTOM_SEARCH_API_KEY": "AIza...",
        "GOOGLE_CUSTOM_SEARCH_ID": "017..."
      }
    }
  }
}
Claude Desktop
Add to ~/Library/Application Support/Claude/claude_desktop_config.json (macOS) or %APPDATA%\Claude\claude_desktop_config.json (Windows):
{
  "mcpServers": {
    "web-researcher": {
      "command": "/path/to/web-researcher-mcp",
      "env": {
        "GOOGLE_CUSTOM_SEARCH_API_KEY": "AIza...",
        "GOOGLE_CUSTOM_SEARCH_ID": "017..."
      }
    }
  }
}
Cursor
Add to .cursor/mcp.json in your project root:
{
  "mcpServers": {
    "web-researcher": {
      "command": "/path/to/web-researcher-mcp",
      "env": {
        "GOOGLE_CUSTOM_SEARCH_API_KEY": "AIza...",
        "GOOGLE_CUSTOM_SEARCH_ID": "017..."
      }
    }
  }
}
HTTP Mode (Teams / Shared Server)
For teams that want one shared instance everyone connects to:
PORT=3000 \
OAUTH_ISSUER_URL=https://auth.example.com \
OAUTH_AUDIENCE=https://api.example.com \
./web-researcher-mcp
Then connect any AI app to http://localhost:3000/mcp/.
services:
  web-researcher:
    image: zoharbabin/web-researcher-mcp
    ports:
      - "3000:3000"
    environment:
      PORT: "3000"
      SEARCH_PROVIDER: brave
      BRAVE_API_KEY: ${BRAVE_API_KEY}
Note: Tool behavior is identical across all connection modes (STDIO and HTTP). The only differences are auth (HTTP requires OAuth) and rate limiting (HTTP enforces per-tenant limits; STDIO has only upstream API quotas). See docs/DEPLOYMENT.md for details.
Performance
Searches come back in under a second. Previously-seen results are cached so repeats are instant. Full article extraction works on 95%+ of the web — including sites that try to block bots. Heavy JavaScript sites get a real browser behind the scenes (automatic, no setup needed).
Development
go build -o web-researcher-mcp ./cmd/web-researcher-mcp   # Build
go test -race ./...                                        # Test (with race detector)
make verify                                                # Full CI gate (see Makefile for steps)
The lint, gosec, and govulncheck tools are pinned as go.mod tool directives, so make verify runs them at the exact versions CI uses (no global installs needed). Branch protection requires the Lint, Test, Security, and E2E checks to pass.
See CONTRIBUTING.md for the full development workflow, code style guide, and PR process.
Troubleshooting
<details> <summary><strong>Server starts but tools fail with "API key" errors</strong></summary>The server starts even with missing credentials (to allow MCP handshake). Set your API keys in the env block of your MCP client config, not in your shell profile.
For JavaScript-heavy sites, the tool uses a real browser (Chromium). With the binary install it auto-downloads on first use (~200MB). If you already have Chrome installed, set CHROME_PATH to point to it. The Docker image ships with Chromium bundled (CHROME_PATH preset), so JavaScript rendering works out of the box — no download.
The disk cache lives at your OS cache directory (e.g., ~/Library/Caches/web-researcher-mcp/ on macOS, ~/.cache/web-researcher-mcp/ on Linux). Delete that directory to clear it, or set CACHE_DIR to a custom path.
If your provider's free tier runs out (e.g. Google PSE allows 100 searches/day):
- Switch to a different provider — set
SEARCH_PROVIDERto any other option (see Configuration); each has its own free tier - Set up multiple providers (e.g.
SEARCH_ROUTING=brave,google) — if one is rate-limited, it automatically falls through to the next - Or upgrade your provider's plan
This happens only if you replaced the binary by copying new bytes over the existing file in place (cp new /path/to/web-researcher-mcp). On Apple Silicon, macOS caches the binary's ad-hoc code signature against the file, and overwriting it in place can make the next launch get killed before it starts. The official installers (Homebrew, the one-command install.sh, and the Claude Code plugin) avoid this by installing to a fresh file. To fix a manual install, replace it cleanly and re-sign:
rm -f /path/to/web-researcher-mcp
cp /path/to/new-build /path/to/web-researcher-mcp
codesign --force -s - /path/to/web-researcher-mcp   # ad-hoc re-sign
Then reconnect your client. (Re-running install.sh does this correctly for you.)
Contributing
Contributions are welcome. Please see CONTRIBUTING.md for code style guidelines, development workflow, and how to submit pull requests.
Documentation
| Document | Description |
|---|---|
| ARCHITECTURE.md | Design decisions, technology stack, dependencies |
| CONTRIBUTING.md | Development setup, code style, PR workflow |
| docs/TOOLS.md | Tool specifications and parameter schemas |
| docs/EXAMPLES.md | Usage examples with JSON tool calls |
| docs/API_SETUP.md | Search provider API key setup for all providers |
| docs/SECURITY.md | Threat model, SSRF, auth, compliance (SOC2/GDPR/FedRAMP) |
| docs/PRIVACY.md | What data goes where, third-party processors, retention |
| docs/DEPLOYMENT.md | Build, Docker, Kubernetes, client configs, scaling |
| docs/PYTHON_CLIENT.md | Python SDK — WebResearcherClient reference, sync wrapper, installation |
| docs/LESSONS_LEARNED.md | Node.js to Go migration story and lessons |
| docs/SESSION_PERSISTENCE.md | How sessions survive context loss — design, data flow, citations |
| docs/MIGRATION.md | Migrating from the deprecated google-researcher-mcp |
License
<p align="center"> Built by <a href="https://zoharbabin.com">Zohar Babin</a>, with <a href="https://go.dev">Go</a> and the <a href="https://modelcontextprotocol.io/">Model Context Protocol</a> </p>
Related MCP servers

io.github.zoharbabin/brand-voice
Enforce brand writing guidelines in Claude Code — PostToolUse hook + MCP server
io.github.zoharbabin/google-researcher
Deprecated Node.js research server; migrate to web-researcher-mcp for multi-source search with citation verification.

io.github.zombico/mojulo
A 3D compiler for coding agents: objects, worlds and games as small recipes. Emits Godot and STL.

QuantContext
Deterministic stock screening, backtesting, and factor analysis for AI trading agents using real market data.

io.github.zoom/zoom-docs
Zoom Docs server for creating and retrieving Zoom documents and notes in Markdown.
io.github.zoom/zoom-meetings
Zoom Meetings server for meeting search, recordings, transcripts, summaries, and meeting assets.